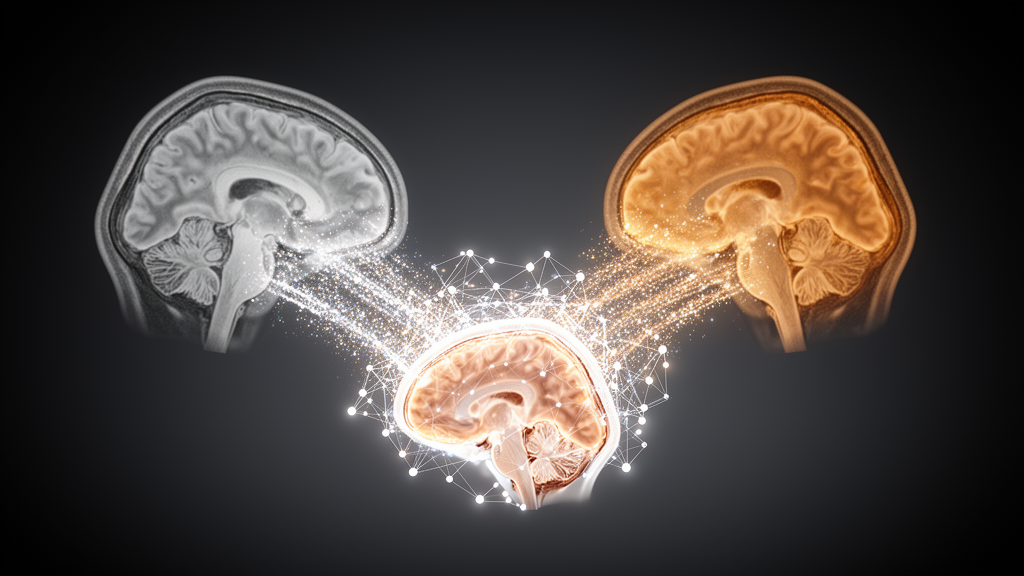
Researchers have proposed a new deep learning architecture, called FADFNet, designed to improve the fusion of multimodal medical images, a task that combines different imaging types of the same anatomy into a single, more informative picture for diagnosis. The work, published in Cluster Computing, addresses a stated weakness of Transformer-based fusion methods: while these models capture global context well, the authors say they tend to lose local details and do not compensate for information that disappears during feature extraction, which can make fused images look unrealistic. FADFNet operates as a two-stage network built around feature aggregation and decomposition with feedback.
The first stage uses a parallel feature extraction module, or PFM, that extracts features along two complementary paths: one focused on fine local detail and the other on global structure. Running these in parallel is intended to give the network a more comprehensive representation of the source images than either approach alone. A key component of this first stage is what the authors call an information compensation mechanism, or ICM.
Instead of letting the network rely solely on its learned intermediate features, the mechanism incorporates the original source images directly into the parallel extraction module. According to the paper, this simple step supplies the network with richer target information and helps counteract the loss of detail that can occur as data pass through successive layers. The second stage goes further with a decomposition feedback network, or DFN, paired with its own associated loss function.
The idea is to decompose the fused result and feed information back into the generation process. This loop is designed to compensate for information loss a second time, enriching the final fused image with finer details than a single forward pass would produce. The authors report that experiments on public datasets showed their approach outperforming other leading fusion methods both visually and quantitatively.
They also state that FADFNet demonstrated satisfactory generalization performance. The published abstract does not specify which imaging modalities were used in the evaluation, nor does it report downstream diagnostic outcomes. The significance of the work lies in the diagnostic role that image fusion plays.
The paper describes multimodal medical image fusion as holding considerable importance for accurate disease diagnosis, because combining complementary imaging information into one image can give clinicians a more complete view than any single modality. The combination of parallel local and global extraction, direct source-image injection, and a decomposition-based feedback stage represents a layered strategy against that problem. The full experimental details, including the quantitative metrics and comparisons with competing methods, are available in the journal article, which appears in Volume 29 of Cluster Computing as article number 891.
Subject of Research: A two-stage deep learning network for multimodal medical image fusion
Article Title: FADFNet: Multimodal medical image fusion based on feature aggregation and decomposition feedback two-stage network
Article References: Li, C., Li, Y., Chan, S., Hu, J., & Hong, F. (2026). FADFNet: Multimodal medical image fusion based on feature aggregation and decomposition feedback two-stage network. Cluster Computing, 29(16), Article 891. https://doi.org/10.1007/s10586-026-06680-y
Image Credits: AI Generated
DOI: 10.1007/s10586-026-06680-y
Keywords: medical image fusion, deep learning, Transformer, feature extraction, feedback network, information compensation, diagnostic imaging, FADFNet, Cluster Computing, computer vision, Multimodal, medical
News Source: Blake Davidson. (October 23, 2026). Two-Stage Feedback Network Aims to Sharpen Multimodal Medical Image Fusion. Scienmag.