A trajectory-analysis system designed for moving objects combined noise filtering, data compression, similarity mining and deep sequence modelling in one pipeline, outperforming three comparison systems in tests on vehicle records and drone flights. The system, named KDDHCBT, reached 93.12% position-analysis accuracy at a 300-second time unit and 93.33% at 600 seconds, while processing at median speeds of 95.23 and 95.17 frames per second, respectively. These results apply to the study’s tested datasets, hardware and time settings; the authors said broader validation is still needed for pedestrians, maritime traffic and other moving-object types.
The project addresses a practical problem in analysing how vehicles, aircraft, people and other objects move through space over time. Sensor-derived trajectories can contain measurement noise, redundant observations, missing values and irregular timestamps, all of which can impair the calculation of movement patterns and future positions. KDDHCBT was designed as an end-to-end system: Kalman filtering first estimates cleaner states, the Douglas–Peucker algorithm compresses the trajectories, dynamic time warping measures similarities between them, hierarchical clustering groups related movement patterns, and a hybrid convolutional neural network, bidirectional long short-term memory network and Transformer-XL model performs spatiotemporal analysis. A final module displays the results on a geographic base map. Kalman filtering provides the first stage of noise reduction by recursively estimating the state of a moving object from its previous state and the latest observation. The model is expressed as s_t = A_t s_(t−1) + ε_t, with observed values represented by y_t = H s_t + v_t, where the matrices describe state transitions and observation relationships and the noise terms represent uncertainty in the trajectory records. After this smoothing step, Douglas–Peucker compression retains selected key points rather than every recorded location. The algorithm joins the beginning and end of a trajectory with a straight line, measures the greatest deviation of intermediate points and recursively retains a point when that deviation exceeds a specified threshold. This stage is intended to balance fidelity against the computational burden of later analysis.
The processed trajectories are then compared with dynamic time warping, a dynamic-programming method that aligns data sequences and finds a minimum cumulative path. Euclidean distances between trajectory points are accumulated along that path, allowing the system to calculate similarity between two movement sequences. The resulting similarity values feed a hierarchical clustering procedure, which constructs a tree of groups and repeatedly merges the clusters with the smallest weighted Euclidean distance. Cluster centers are calculated from the mean values of their trajectory points. In this way, the system combines pairwise trajectory similarity with group-level clustering before passing the results into the spatiotemporal model.
The central spatiotemporal model has three complementary components. Convolutional layers apply multiple filters to the trajectory input, extracting local spatial features; max pooling then reduces the feature-map size and is intended to limit overfitting. Bidirectional LSTM units process the extracted information in forward and backward directions, retaining or discarding information through input, forget and output gates. Their output is passed to Transformer-XL, whose positional encoding and multi-head self-attention allow it to model dependencies across longer trajectory sequences. The authors describe this as a dual-time strategy in which the recurrent network captures shorter-term changes and the transformer captures longer-range patterns. The final layer produces continuous position coordinates with a linear activation function.
Training used the Adam optimizer with an initial learning rate of 0.001, reduced by a factor of 0.9 every 20 epochs, although the experimental configuration separately lists a learning rate of 0.01. The network used 64-sample batches and a maximum of 100 training epochs, with early stopping when test loss failed to improve for 10 consecutive epochs. Its loss combined mean squared error with smooth L1 loss to limit the influence of outliers. ReLU was used in convolutional layers, tanh in the LSTM units and hidden states, and a linear function in the output layer. These implementation details mean that the reported performance reflects a particular combination of architecture, optimization schedule and evaluation protocol rather than an architecture-independent property.
For its principal performance test, the researchers used an internal radio-frequency-identification vehicle dataset supplied by a city traffic management bureau. It contained 2.8 million records from 519 base stations during September 2024, covering approximately 126,000 vehicles and recording passage times, base-station numbers, licence-plate numbers and lanes. About 4.7% of the original records had missing licence-plate information or abnormal timestamp formats. The team completed missing position information with linear interpolation, standardized timestamps into continuous seconds and marked stays longer than 600 seconds at one base station as stopping points. The records were divided into training and test sets at an 8:2 ratio. Because the dataset is internal, it was not publicly available, and the findings cannot yet be independently assessed on the same records.
In that RFID evaluation, KDDHCBT’s steady-state position-analysis accuracy was 96.01%, compared with 92.78% for CNN-LSTM-Att, 92.33% for trajectory image structure matching with a convolutional autoencoder, and 89.05% for a real-time heuristic trajectory-prediction system based on spatiotemporal databases. Its steady-state loss was 0.67, reported as lower than those of the comparisons. The test set’s median trajectory-prediction accuracy was 95.17%, while the training-set median was 96.31%. All comparative experiments were repeated five times with shuffled data partitions, and the trajectory-prediction differences were evaluated with a Wilcoxon signed-rank test; the paper reports p-values below 0.05 for the proposed system’s advantage over the comparison models. These are model-based estimates and accuracy measures, not evidence that every real-world trajectory forecast will be correct.
Separate ablation experiments examined the contribution of each component. The complete system was compared with configurations in which major modules were removed or replaced, with paired t-tests used for each indicator across 10 random data partitions. Removing Transformer-XL produced the largest reported decline in trajectory-prediction performance, with a t-statistic of 8.47, followed by BiLSTM at 7.63 and CNN at 6.91. The corresponding statistics for removing Kalman filtering, dynamic time warping and hierarchical clustering were 5.24, 4.18 and 3.92. Differences from the complete system in position-analysis accuracy were reported as significant at p below 0.01. By contrast, speed differences were significant only when hierarchical clustering was removed, suggesting that its computational contribution was more pronounced than those of the other ablated components under the tested setup.
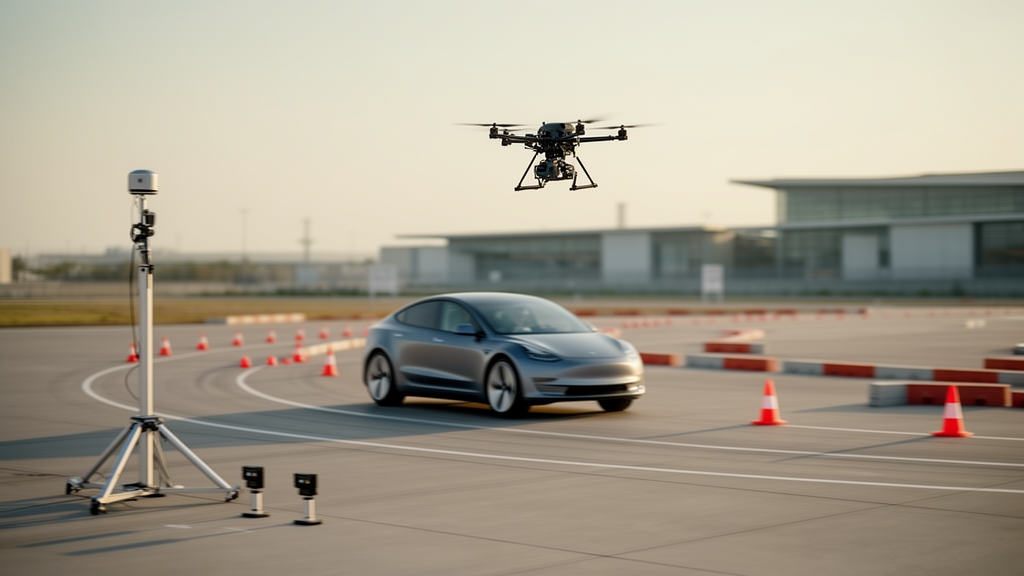
A second practical evaluation used trajectories collected by a drone flying in an open outdoor area through straight, circular-hovering and octagonal manoeuvres. Each manoeuvre was repeated five times, yielding 53 valid trajectories with approximately 300–500 points apiece at a sampling frequency of 10 hertz, or about 21,000 points in total. Missing data were filled by spline interpolation, and motion-mode labels were assigned manually. KDDHCBT achieved 92.67% position-analysis accuracy, above 83.16% for CNN-LSTM-Att, 88.64% for the autoencoder-based system and 90.12% for the database-based system. At the 300- and 600-second time units, its reported accuracies were 93.12% and 93.33%, while median processing speeds reached 95.23 and 95.17 frames per second. The results were obtained on an Nvidia RTX 3070 and AMD Ryzen 7 platform, leaving performance on lower-powered hardware unresolved. The visualization module, implemented with Matplotlib and Basemap, adds a geographic view of the model’s outputs. Scatter plots place timestamped positions on a base map, using different colours or symbols for objects or movement states. Flow visualizations convert trajectories into directional streamlines or bands, with density and colour depth indicating how frequently a route is travelled. Together, these displays are intended to reveal activity ranges, hotspots and the spatial separation among trajectory groups during a selected period. The system’s central achievement is therefore not a single new neural-network algorithm, but the integration of filtering, compression, similarity analysis, clustering, prediction and visualisation into a coherent pipeline. Its reported gains were observed against selected benchmarks, but validation across other object classes, environments, time resolutions and streaming workloads is required before its general effectiveness can be established.
Subject of Research: An integrated trajectory-mining, deep-learning and visualisation system for moving-object analysis and prediction
Article Title: Spatiotemporal analysis and visualization system design for moving objects based on trajectory data mining
Article References: Ye, X. (2026). Spatiotemporal analysis and visualization system design for moving objects based on trajectory data mining. Discover Artificial Intelligence, 6(1), Article 1083. https://doi.org/10.1007/s44163-026-02031-3
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02031-3
Keywords: trajectory mining, moving-object analysis, spatiotemporal modelling, trajectory prediction, Transformer-XL, Kalman filtering, dynamic time warping, hierarchical clustering, vehicle tracking, drone trajectories, Spatiotemporal, analysis
News Source: Denise Maddox. (October 26, 2026). Trajectory system outperforms benchmarks in vehicle and drone tests. Scienmag.