A machine-learning framework that combines learners’ expressed attitudes with their academic performance and tool-use behavior outperformed conventional and deep-learning baselines across four educational tasks. The study used 50,000 anonymized records from students and teachers to classify sentiment, predict learning improvement, estimate intention to adopt AI tools and rank personalized learning resources. The proposed Dual-Channel Fusion Performance Encoder achieved 0.91 accuracy and an 0.89 F1-score for sentiment classification, a mean absolute error of 3.8 and R² of 0.72 for learning-outcome regression, and 0.88 accuracy with a 0.90 area under the ROC curve for adoption-intention prediction. Its adaptive recommendation component reached a Precision@5 of 0.78 and mean reciprocal rank of 0.80. These results describe performance on the study’s benchmark dataset and do not establish that the system itself improves learning in a classroom.
The research treats adoption as a multi-part problem rather than a single yes-or-no decision. The dataset includes sentiment-labelled feedback, pre- and post-test scores, task completion, adaptive difficulty progression, session logs, usage frequency, time on task and perceptions of usefulness, ease of use, trust and ethical concern. Adoption intention was treated as an ordinal outcome with five levels, from “Very Low” to “Very High.” The records span students and teachers, different educational levels, academic disciplines and AI-assisted learning environments. Because the study used an existing anonymized dataset and did not report a prospective classroom trial, its results primarily show that the combined model can predict measured outcomes in the available data.
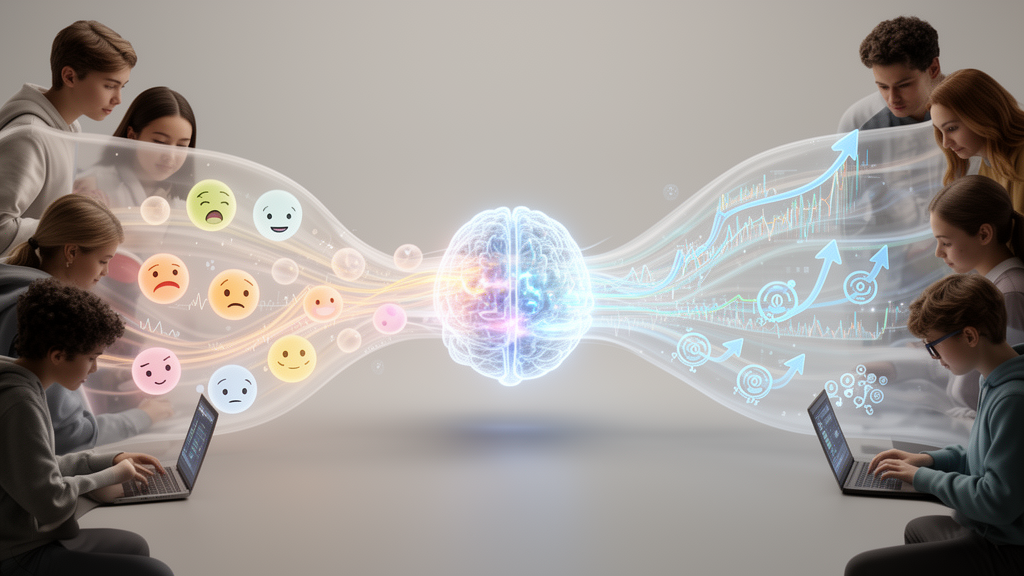
At the centre of the architecture is a two-channel neural network. One channel processes sentiment-focused representations, including polarity, subjectivity and emotional expression; the other represents performance and adaptive behavior, including test results, engagement logs and AI use. Text was first cleaned through tokenization, lemmatization and stop-word handling. A domain-tuned RoBERTa encoder supplied contextual semantic embeddings, while an affective lexicon contributed features for valence, arousal and polarity. The system aggregated these features with attention, normalized the affective representation and used an emotion-aware gate to balance semantic and emotional signals. Feature-wise linear modulation with residual scaling then refined the fused representation.
The authors subsequently connected the two channels through bidirectional cross-attention. Sentiment embeddings queried performance features, while performance embeddings queried sentiment information, allowing the network to model relationships between expressed attitudes and measurable academic activity. Contrastive representation learning aligned sentiment representations with performance and learning-outcome representations so that related affective and outcome patterns were pulled closer together. The resulting representation supported three jointly trained tasks: categorical sentiment classification, continuous prediction of post-test minus pre-test improvement, and ordinal prediction of adoption intention. Cross-entropy, mean-squared error and cumulative-link loss were combined with weights of 1.0, 0.8 and 0.7, respectively, selected through five-fold cross-validation.
For deployment efficiency, the design added curriculum-based knowledge distillation. A larger teacher model, described as a RoBERTa and TabNet ensemble, transferred softened output distributions to a smaller student network, beginning with high-confidence examples and progressing toward harder cases. The agentic layer was trained with Proximal Policy Optimization. It observed sentiment representations, trust scores, engagement statistics and learning-performance indicators, then selected among actions such as changing difficulty, generating motivational feedback, recommending resources and modifying study strategy. Its reward combined predicted score improvement, predicted satisfaction change and an intervention cost, with coefficients of 0.5, 0.4 and 0.1. Importantly, the paper describes this component as simulating and evaluating interventions; it is not evidence from a live deployment.
Sentiment classification improved as the representation became more context-sensitive. A logistic-regression bag-of-words model reached 0.74 accuracy and a 0.72 F1-score, while a BiLSTM using GloVe embeddings rose to 0.82 accuracy and 0.80 F1-score. Fine-tuned RoBERTa achieved 0.88 accuracy and 0.86 F1-score, and adding the affective lexicon produced a smaller gain to 0.89 and 0.87. The full hybrid encoder achieved the reported 0.91 accuracy and 0.89 F1-score. For learning-outcome prediction, a simple linear regression using pre- and post-test scores had a mean absolute error of 7.1 and R² of 0.48. Random forest improved these to 5.6 and 0.60, TabNet reached 4.7 and 0.66, and a transformer encoder achieved 4.2 and 0.70. The dual-channel model recorded the lowest reported error, with mean absolute error of 3.8, root mean squared error of 5.1 and R² of 0.72.
Adoption-intention results showed a similar pattern. Logistic regression based on perception features alone achieved 0.77 accuracy and an area under the ROC curve of 0.78, while a random forest using numeric usage patterns reached 0.81 and 0.83. A multilayer perceptron improved nonlinear modeling, and late fusion of RoBERTa with TabNet added a further advantage. The full dual-channel model produced 0.88 accuracy and a 0.90 area under the ROC curve, exceeding the perception-only and behavior-only alternatives. The paper’s interpretation was that adoption cannot be explained by scores or subjective impressions alone: attitude, trust, satisfaction and sustained engagement each contributed information that the combined architecture could use.
Recommendation tests likewise favored the integrated system. Matrix factorization achieved a Precision@5 of 0.61, NDCG@5 of 0.63 and mean reciprocal rank of 0.62, while neural collaborative filtering improved Precision@5 to 0.66 and NDCG@5 to 0.69. Graph-based LightGCN and the sequential model SASRec performed better again, but the agentic dual-channel transformer led the reported comparison with a Precision@5 of 0.78 and mean reciprocal rank of 0.80. The authors attributed this result to the incorporation of sentiment cues and performance histories into the ranking process. These figures measure the relevance and ordering of recommended items in the dataset; they do not quantify the learning benefit of following those recommendations.
Several analyses were intended to make the model’s decisions more inspectable. SHAP analyses indicated that perceived usefulness and observed improvement contributed strongly to some positive sentiment predictions, while ease of use, trust and satisfaction were prominent in adoption-intention modeling. Session logs and engagement features strongly influenced recommendations, with difficulty progression and sentiment polarity providing additional signals. Attention visualization assigned relatively high weights to words including “very” and “useful,” while counterfactual analysis examined how changes in sentiment or engagement could alter predicted adoption probability. An ablation study supported the architecture’s component design: removing the affective lexicon reduced sentiment accuracy to 0.88 and adoption AUC to 0.87, removing contrastive alignment increased outcome mean absolute error to 4.1, and removing cross-attention lowered outcome R² to 0.68 and adoption AUC to 0.86. A sentiment-only model performed especially poorly for outcome prediction, with mean absolute error of 6.0 and R² of 0.55.
Exploratory analyses also revealed substantial variation among users and tools. Positive responses formed the largest sentiment group, with neutral responses next and negative responses relatively uncommon. AI tutors, quiz generators and large-language-model assistants were associated with greater perceived educational value than curriculum planners or explainability bots. Students generally completed more sessions and tasks than teachers, and both groups showed higher post-test than pre-test scores in the dataset. A hierarchical correlation analysis placed satisfaction, perceived usefulness and adoption intention in a related cluster, with a reported correlation of approximately 0.31 between usefulness and adoption intention. The study’s authors called for future work using larger and more diverse datasets across cultural and institutional settings, as well as further development of real-time adaptive interventions. Until then, the strongest defensible conclusion is that sentiment-aware fusion can improve prediction and ranking in this educational AI-adoption dataset; whether it delivers durable academic benefits in real classrooms remains unproven.
Subject of Research: Sentiment-aware machine learning for predicting educational AI-tool adoption and adaptive learning outcomes
Article Title: Agentic AI dual channel fusion for sentiment aware adaptive learning in educational AI tool adoption
Article References: Wang, H., & Bai, R. (2026). Agentic AI dual channel fusion for sentiment aware adaptive learning in educational AI tool adoption. Discover Artificial Intelligence, 6(1), Article 1077. https://doi.org/10.1007/s44163-026-02118-x
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02118-x
Keywords: educational artificial intelligence, sentiment analysis, adaptive learning, AI-tool adoption, machine learning, student performance, explainable AI, recommender systems, multi-task learning, agentic AI, Agentic, dual
News Source: Blake Davidson. (October 26, 2026). Dual-Channel AI Model Links Sentiment, Performance and Educational Tool Adoption. Scienmag.