Compact Multimodal Transformer Boosts Collaborative Robot Manipulation Success to 87 Percent
The Collaborative Robot Transformer integrates vision, language, and proprioception to achieve an 87.14 percent success rate on mobile manipulation tasks.
The Collaborative Robot Transformer integrates vision, language, and proprioception to achieve an 87.14 percent success rate on mobile manipulation tasks.
Researchers have developed HFCSNet, a dual-backbone neural network combining vision transformers and convolutional layers to achieve highly accurate, topologically connected ...
Researchers evaluating self-supervised vision transformers on potato leaf disease classification found that the DINO-ViT framework achieved 83.44 percent accuracy, outperforming ...
Researchers have developed an integrated deep-learning framework combining attention-guided segmentation and multi-resolution transformer learning that achieves 96.0 percent accuracy and ...
A systematic review of 280 studies reveals that while deep learning models achieve high diagnostic discrimination across twelve disease categories, ...
A new adapter-learning framework enables visual foundation models to identify Parkinson’s disease from optical coherence tomography images with 77.66 percent ...
A simulation study of split deep neural network inference reveals that running lightweight vision models locally with voltage scaling emits ...
Researchers have introduced H-ViT, a post-training quantization method that uses power-of-two scaling factors to achieve efficient integer-only vision transformer inference ...
A PRISMA-guided systematic review of 81 deep-learning studies details how text-and-image multimodal fake news detection has transitioned toward transformer encoders ...
Researchers have introduced Suppression-Absence-Competition eXplanations, a structured visual framework that isolates why neural network classifiers select a predicted class while ...
A rigorous comparative study revealed that while MambaVision achieved the highest nominal benchmark accuracy for avian species classification, standard Vision ...
A comprehensive literature survey reveals that vision-based driver distraction classification systems suffer significant accuracy drops when evaluated on unseen drivers ...
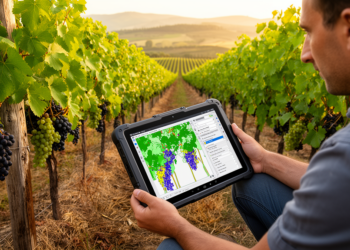
Agricultural engineers demonstrated that explainable artificial intelligence can guide the development of hybrid convolutional-transformer networks that improve grapevine component segmentation ...
Researchers designed a quantum vision adversarial attention network that achieved 99.98 percent accuracy in evaluating artificial intelligence disclosures across Indian ...
Researchers developed EARS-Net, a hybrid deep learning model combining generative oversampling, dual attention, and transformers that achieves superior facial expression ...
A comprehensive review of a decade of road scene parsing reveals that while drivable surface detection is well-solved, detecting road ...
A novel explainable Vision Transformer framework integrating paired mammographic views achieved high diagnostic classification accuracy and superior explanation faithfulness across ...
A narrative review and multi-dataset benchmark shows deep learning algorithms outperform classical thresholding methods in segmenting cell nuclei across major ...
A comprehensive review reveals that deep learning artificial intelligence systems achieve over ninety percent accuracy in bladder cancer detection, though ...
Evaluating lung adenocarcinoma whole-slide images revealed that mild JPEG2000 compression reduces storage requirements by approximately 90% while maintaining deep learning ...