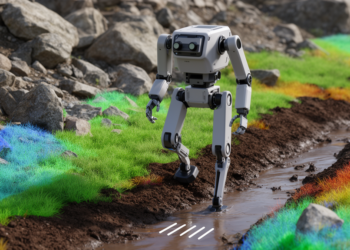
Semantic Labels Guide Terrain-Specific Humanoid Behavior in Simulation
A simulator study found that semantic terrain labels guided a unified behavior-cloning policy to select flat-ground and stairway behaviors for ...
A simulator study found that semantic terrain labels guided a unified behavior-cloning policy to select flat-ground and stairway behaviors for ...
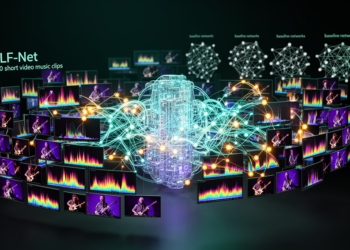
SALF-Net outperformed self-supervised baselines on a 30,000-clip short-video test set, while a distilled version retained 95% of its quality at ...
A new multimodal model called MusicFormer fuses audio, sheet music, lyrics and regional cultural labels to recognize regional music styles ...
Fed-DATrust is a cross-stage risk-coordination framework that improves the reliability of federated multimodal learning for disaster damage assessment.
A new mini-review maps what happens when multimodal sensing, federated privacy and continual adaptation must work simultaneously in human activity ...
A PSO-fused model combining text, speech and video representations reached 94.0% accuracy on 690 labeled television-dialogue utterances in the MUStARD ...
A DETR-CLIP study of 5,000 children’s drawings reported stronger detection and semantic performance than several baselines, with lower results on ...
AgriMamba combines field images with pathological descriptions to locate diseased leaves, segment lesions and grade severity, reporting competitive performance across ...
A new multimodal AI model from South Korea classifies five neurological language disorders from spontaneous speech while also estimating severity ...
A federated multimodal AI framework improved motor skills and social inclusion for preschoolers in a 16-week trial while keeping all ...
A South Korean pilot study shows that a multimodal AI framework combining video features and wearable motion sensor data, trained ...
A systematic review of 38 studies finds that protein language models excel on benchmarks but largely lack experimental validation, prompting ...
Researchers have developed MMA-HNS, a framework that keeps multimodal knowledge graph completion accurate even when the textual descriptions of entities ...
A new multimodal AI framework ranks classroom features by importance with 88.6 percent prediction accuracy, identifying linguistic coherence, student engagement, ...
Researchers in South Korea have developed a multimodal deep learning model that fuses visual analysis and textual rubrics to automatically ...
Researchers have introduced HGA-Net, a hypergraph-based adapter that connects related examples within each mini-batch and achieves near-perfect fine-grained recognition with ...