• HOME
  • NEWS
  • EXPLORE
    • CAREER
      • Companies
      • Jobs
    • EVENTS
    • iGEM
      • News
      • Team
    • PHOTOS
    • VIDEO
    • WIKI
  • BLOG
  • COMMUNITY
    • FACEBOOK
    • INSTAGRAM
    • TWITTER
Monday, October 26, 2026
BIOENGINEER.ORG
No Result
View All Result
  • Login
  • HOME
  • NEWS
  • EXPLORE
    • CAREER
      • Companies
      • Jobs
        • Lecturer
        • PhD Studentship
        • Postdoc
        • Research Assistant
    • EVENTS
    • iGEM
      • News
      • Team
    • PHOTOS
    • VIDEO
    • WIKI
  • BLOG
  • COMMUNITY
    • FACEBOOK
    • INSTAGRAM
    • TWITTER
No Result
View All Result
Bioengineer.org
No Result
View All Result
Home NEWS Science News Technology

SALF-Net outperforms baselines on 30,000 short-video music clips

by
October 26, 2026
in Technology
Reading Time: 2 mins read
0
SALF-Net outperforms baselines on 30,000 short-video music clips

SALF-Net outperforms baselines on 30,000 short-video music clips

Share on FacebookShare on TwitterShare on LinkedinShare on RedditShare on Telegram

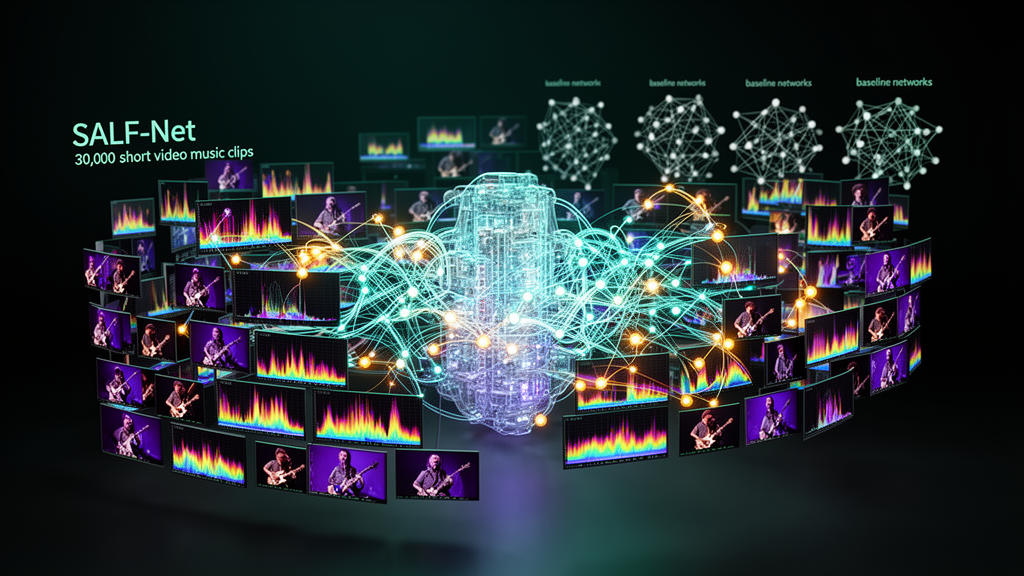
A self-supervised audio-lyric fusion network called SALF-Net outperformed strong self-supervised baselines at identifying emotion-related tags in short-video music, according to a study in Scientific Reports. On a newly constructed test collection of 30,000 clips, the model achieved a precision-recall area under the curve of 0.389 and a ROC-AUC of 0.921. The researchers also developed a distilled student version that preserved 95% of the teacher model’s quality while reducing inference time to 2% of the teacher’s latency.

The work focuses on background music in short videos, including clips lasting 15 to 60 seconds and recorded in uncontrolled environments. Such audio may be truncated, degraded or unavailable in the form of lyrics, including when a track is instrumental. The study notes that emotion-related metadata for these clips is still produced mainly through manual annotation or generic audio taggers that were not designed for short-video recordings. SALF-Net was designed to address these constraints by combining acoustic information with lyric information when available while remaining functional when one modality is missing.

The audio branch adapts a music-domain self-supervised transformer encoder to clip-level inputs through masked segment sampling and statistics pooling. A separate lyric branch uses a pretrained language model to encode lyrics obtained through automatic transcription or metadata. Between them, a gated cross-modal fusion module combines the two representations. Modality dropout is used during training so that the system can continue operating when lyrics are absent or unreliable, a condition described as common for instrumental tracks and noisy recordings. SALF-Net also has a multi-task objective that jointly predicts multi-label emotion tags and valence-arousal values, using the dimensional task to regularize the geometry of the learned tag representation.

Evaluation combined the mood-and-theme subset of the MTG-Jamendo dataset, the DEAM dimensional emotion benchmark and the newly assembled short-video test collection of 30,000 clips. The reported results indicate that SALF-Net performed better than strong self-supervised baselines under the tested conditions. The student model’s latency result suggests that much of the teacher model’s performance can be retained in a form suited to faster deployment. The authors interpret the findings as evidence that accurate, robust and deployable emotion tagging is feasible at short-video scale without relying on platform-private annotation budgets. The supplied study abstract does not provide genre-specific results, platform-wide testing, human-judgment comparisons or performance across every uncontrolled recording environment, so those aspects remain outside the reported evidence.

Subject of Research: Self-supervised audio-lyric fusion for emotion tagging of short-video music

Article Title: Automatic music emotion tag generation for short-video platforms: a self-supervised audio-lyric fusion network with valence-arousal regularization

Article References: Liu, Z., & Hong, H. (2026). Automatic music emotion tag generation for short-video platforms: a self-supervised audio-lyric fusion network with valence-arousal regularization. Scientific Reports. https://doi.org/10.1038/s41598-026-76372-5

Image Credits: AI Generated

DOI: 10.1038/s41598-026-76372-5

Keywords: music emotion recognition, short-video metadata, self-supervised learning, audio-lyric fusion, valence-arousal regression, multimodal learning, modality dropout, model distillation, emotion tags, short-video audio, Automatic, music

News Source: Denise Maddox. (October 26, 2026). SALF-Net outperforms baselines on 30,000 short-video music clips. Scienmag.
Tags: audio-lyric fusionautomaticemotion tagsmodality dropoutmodel distillationmultimodal learningmusicmusic emotion recognitionSelf-Supervised Learningshort-video audioshort-video metadatavalence-arousal regression
Share12Tweet7Share2ShareShareShare1

Related Posts

Clinically guided machine learning stratifies dental implant risk in European dataset

Clinically guided machine learning stratifies dental implant risk in European dataset

October 26, 2026
Molecular weight of hyaluronic acid emerges as a master switch in cancer nanomedicine

Molecular weight of hyaluronic acid emerges as a master switch in cancer nanomedicine

October 26, 2026

Computational model shows how the brain dodges obstacles while reaching for goals

October 26, 2026

Two Drone Flights, One Better Forecast: Bare-Soil Imagery Boosts Soybean Yield Prediction

October 26, 2026

POPULAR NEWS

  • Bundled payments modestly reduced Dutch joint-replacement spending, study finds

    Bundled payments modestly reduced Dutch joint-replacement spending, study finds

    29 shares
    Share 12 Tweet 7
  • Ultrasound produces faster-dissolving simvastatin particles in laboratory study

    29 shares
    Share 12 Tweet 7
  • Clinically guided machine learning stratifies dental implant risk in European dataset

    29 shares
    Share 12 Tweet 7
  • SALF-Net outperforms baselines on 30,000 short-video music clips

    29 shares
    Share 12 Tweet 7

About

We bring you the latest biotechnology news from best research centers and universities around the world. Check our website.

Follow us

Recent News

Bundled payments modestly reduced Dutch joint-replacement spending, study finds

Ultrasound produces faster-dissolving simvastatin particles in laboratory study

Clinically guided machine learning stratifies dental implant risk in European dataset

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 85 other subscribers
  • Contact Us

Bioengineer.org © Copyright 2023 All Rights Reserved.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Homepages
    • Home Page 1
    • Home Page 2
  • News
  • National
  • Business
  • Health
  • Lifestyle
  • Science

Bioengineer.org © Copyright 2023 All Rights Reserved.