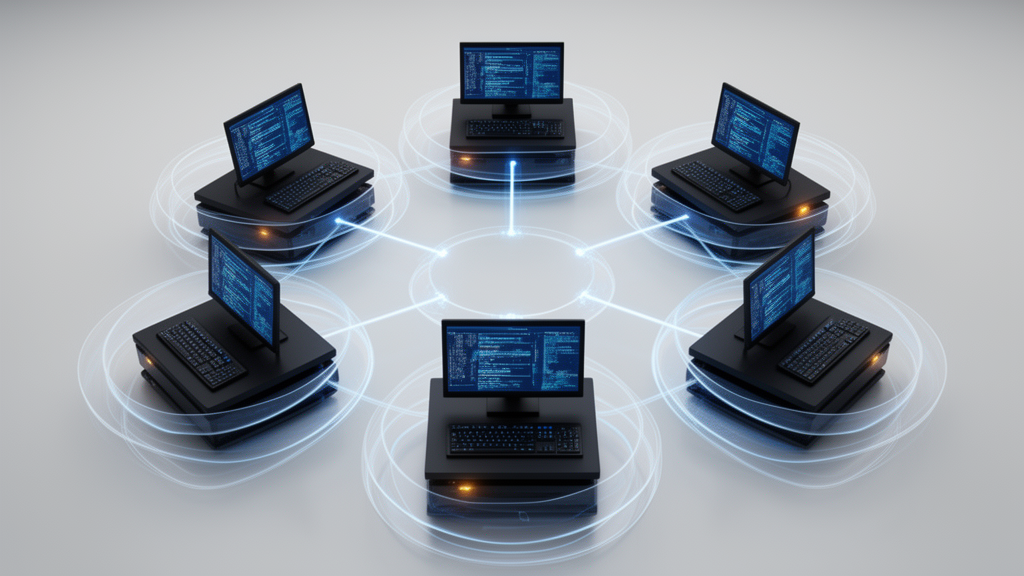
A multi-layered security framework for decentralized federated learning improved classification accuracy and resistance to poisoning and adversarial perturbations in an experiment involving six peers and the CIFAR-10 image-classification benchmark. The complete framework achieved 86.12% clean accuracy, compared with 83.10% for a vanilla decentralized model, while retaining substantially more accuracy under Fast Gradient Sign Method, Projected Gradient Descent and Carlini–Wagner attacks. The system combined public-data pretraining, differentially private fine-tuning, local data sanitization, peer model verification, robust aggregation and runtime screening, rather than relying on a single protection mechanism.
Federated learning enables participating clients to train a shared artificial intelligence model without transferring their raw records to a central server. Decentralized federated learning removes the central coordinator as well, replacing it with peer-to-peer communication among clients. That arrangement can reduce dependence on one trusted institution and support distributed systems, but the lack of central oversight also creates opportunities for compromised participants to manipulate shared model updates. The study examined a threat model in which up to two of six clients could be malicious, corresponding to a maximum client-compromise ratio of 33.3%. Unless otherwise specified, each compromised client poisoned 20% of its local training samples, and the malicious clients operated independently rather than coordinating their attacks.
For the privacy component, the researchers first trained a convolutional neural network on a clean public dataset. This stage incurred no differential-privacy cost and supplied general feature representations before the model was adapted to client data. The model was then fine-tuned using differentially private stochastic gradient descent, with gradients clipped to an L2 norm of 1.0 and Gaussian noise applied at a noise multiplier of 1.1. Training used a batch size of 64, one local epoch per communication round and 50 rounds across the six peers. Accounting with the Rényi differential privacy accountant produced a reported final guarantee of ε = 4.8 and δ = 10⁻⁵. These parameters define the configured privacy mechanism and its reported accounting; the experiment did not directly compare leakage from the defended and undefended systems using a gradient-reconstruction or membership-inference benchmark.
The public-pretraining strategy appeared to reduce the accuracy loss associated with noisy private gradients in the tested setup. End-to-end differentially private training remained below 40% accuracy, whereas public pretraining followed by differentially private fine-tuning reached approximately 77%. In a separate differential-privacy fine-tuning curve, accuracy rose from about 28% in early rounds to more than 42% in later rounds as the accumulated privacy loss increased. These observations support the reported improvement in the privacy–utility balance for this particular CIFAR-10 configuration, but they should not be interpreted as a direct measurement of how much sensitive information an attacker could recover. Without the privacy constraints, the reference model reportedly converged rapidly to approximately 84–85% training accuracy, illustrating the utility penalty associated with noisy optimization.
Against malicious participants, the framework applies several defenses in sequence. At the data level, FLARE estimates the likelihood of each sample, embeds the examples with UMAP and groups the representations with HDBSCAN. The method assumes that benign data form a principal dense cluster, while poisoned or anomalous examples form smaller, distinct clusters that can be removed. The surviving samples undergo augmentation with Kornia and AlbumentationsX, together with occasional single-step FGSM adversarial training. Local updates are then exchanged among peers. Candidate models are examined with TeCo, STRIP and SentiNet before entering the aggregate, allowing suspicious training samples and suspicious peer models to be addressed at different stages of collaborative training.
Peer verification begins with TeCo and STRIP. TeCo applies 15 standard corruptions at five severity levels to validation images and records the point at which predictions break; unusually consistent breaking points across corruption types can indicate a backdoor. STRIP measures prediction entropy after strong perturbations, with suspiciously low entropy serving as another warning sign. A candidate flagged by either check is escalated to SentiNet, which uses Grad-CAM saliency maps to look for concentrated attention on a possible trigger. The acceptance gate is conservative: inconsistency, abnormal entropy or trigger sensitivity leads to rejection of the update. This approach prioritizes security over retaining every peer contribution, but the paper does not provide a complete quantitative ablation of each module. Some descriptions of the individual techniques in the article differ from their implementation in the experimental pipeline, so the reported end-to-end results should not be attributed to one component in isolation.
Accepted models are combined through a trimmed-mean aggregation rule. For each model parameter, values are sorted across participating models, the two largest and two smallest values are discarded, and the remaining values are averaged. Choosing two values at each end corresponds to the stated assumption that no more than two of six clients are compromised and satisfies the condition that twice the trimming parameter must be smaller than the number of participants. The authors note that trimming only one value at each end could leave a malicious update with excessive influence, whereas trimming more could discard useful contributions when client data are heterogeneous. The selected configuration was therefore tied to the experiment’s threat model and six-client topology rather than demonstrated as optimal for larger or non-IID networks.
Under inference-time attacks, the defended model retained considerably more accuracy than the vanilla model. Accuracy under the Fast Gradient Sign Method rose from 37.71% to 53.88%, while Projected Gradient Descent accuracy increased from 21.75% to 46.40%. Carlini–Wagner accuracy rose from 40.62% to 67.35%. These were white-box evaluations in which FGSM and PGD used perturbations of ε = 8/255; PGD used a step size of 2/255 and 10 iterations. The differences show better performance than the baseline under these specific attack settings. They do not establish robustness to adaptive attacks, colluding clients, non-image models or attacks outside the selected image-classification testbed.
The strongest training-time results involved structured backdoors. For the adversarially trained model, adding the defense pipeline increased accuracy under BadNets poisoning from 80.5% to 86.0% and under the Blended attack from 80.0% to 85.9%. Attack success rates for the defended framework were reported as 18.5% for BadNets and 19.2% for Blended, compared with corresponding undefended figures of 92.8% and 91.4%. The runtime shield achieved a reported true-positive rate of 96.8% and false-positive rate of 2.4%. Label flipping was less successfully addressed: accuracy changed only from 78.5% to 78.6% for the adversarially trained model because the defense’s trigger-oriented screening had less to detect when class annotations, rather than visible trigger patterns, were corrupted. The authors identify dedicated label-noise detection as a direction for further work.
The added safeguards carried measurable costs in the tested system. Local sanitization required approximately 312 milliseconds per client, peer verification 458 milliseconds per communication round and trimmed-mean aggregation 214 milliseconds. The runtime protection layer added 12.7 milliseconds to inference, while lightweight verification metadata increased communication by approximately 11.4% per round without requiring an additional synchronization round. These timings describe a small experimental platform rather than a large heterogeneous network. The evaluation was limited to CIFAR-10, a lightweight CNN, six clients receiving approximately equal IID partitions, a clean public dataset for pretraining and a white-box threat model. It also did not directly benchmark the framework against other decentralized backdoor defenses under identical conditions. Adaptive and colluding adversaries, non-IID data, larger deployments, transformer models and label-noise defenses remain unevaluated and are identified by the authors as subjects for future research.
Subject of Research: Evaluation of layered privacy and poisoning defenses in six-client decentralized federated learning
Article Title: Trustworthy and privacy-preserving decentralized federated learning with multi-layer defense for secure collaborative AI
Article References: Sivan, D., Shanmugam, U. M., Vasily, S., & Sellappa Gounder, M. (2026). Trustworthy and privacy-preserving decentralized federated learning with multi-layer defense for secure collaborative AI. Discover Artificial Intelligence, 6(1), Article 1041. https://doi.org/10.1007/s44163-026-02045-x
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02045-x
Keywords: decentralized federated learning, differential privacy, model poisoning, backdoor attacks, adversarial robustness, peer verification, robust aggregation, CIFAR-10, public-data pretraining, runtime detection, Trustworthy, privacy-preserving
News Source: Denise Maddox. (October 26, 2026). Layered defenses improve resilience in six-client decentralized AI study. Scienmag.