Financial fraud detection has always been one of machine learning’s most unforgiving proving grounds. Fraudulent transactions are vanishingly rare, adversaries adapt their tactics the moment a detector is deployed, and the patterns that defined last month’s fraud can quietly dissolve into next month’s legitimate traffic. A new open-access study published in Discover Artificial Intelligence argues that the field’s latest enthusiasm—using large language models to generate human-readable explanations for fraud decisions—introduces a dangerous weakness precisely where it promises strength: the explanations themselves may be fabricated. The research team, led by Md Sultanul Arefin Sourav and colleagues, proposes a framework called VR-FraudNet that treats the language model not as an authority but as a fallible proposer whose every claim must survive an independent, deterministic audit before it can influence an automated decision.
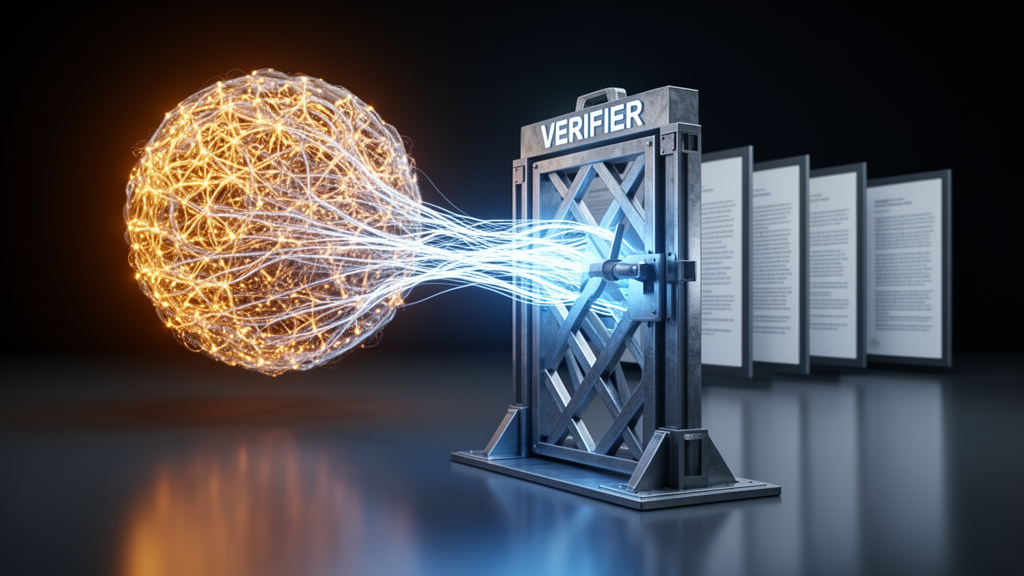
The core insight is deceptively simple. Language models can produce fluent, persuasive rationales for why a transaction looks suspicious, but fluency is not evidence. A model might assert that a transaction amount exceeds a customer’s historical average, or that an account connects to a known mule cluster, without any of those statements actually being true of the underlying record. In a financial institution, such hallucinated justifications are worse than useless—they can misdirect investigators, contaminate audits, and create regulatory exposure. VR-FraudNet therefore separates explanation generation from explanation validation. The language model proposes structured, machine-checkable claims; a fixed, non-trainable verifier then checks each claim against the transaction record, temporal information, and graph context. Only rationales that pass every check are allowed to feed into the final fraud probability. Everything else is routed to human reviewers.
Architecturally, the system unfolds in five stages. Stage 0 is a time-conditioned spectral graph encoder that compresses the transaction’s relational neighborhood—accounts, merchants, money flows—into a compact 64-dimensional embedding, using four Beta-kernel spectral filters whose coefficients shift with evaluation time so the representation can track how fraud networks evolve. Stage 1 is a LightGBM triage classifier with 500 trees that assigns an initial fraud probability and applies two validation-tuned thresholds: transactions below the lower threshold sail through the fast path as low risk, those above the upper threshold are rejected as high risk, and only the uncertain middle band escalates to the expensive language-model pathway. This routing design matters operationally, because invoking a multi-billion-parameter model on every transaction would be prohibitively slow and costly.
Stage 2 is where the language model enters, and the constraints placed on it are unusually strict. The generator is Meta-Llama-3.1-8B-Instruct, adapted with low-rank adapters rather than full fine-tuning, and it must emit a structured JSON object containing a proposed verdict, a rationale-side probability, and at most eight typed claims drawn from five primitives: numeric comparisons, set memberships, temporal relations, graph paths, and entity matches. Grammar-masked decoding enforces the schema during generation itself—an incremental parser masks any token that would break JSON syntax or introduce an unsupported field—so the model literally cannot produce free-form text. Retrieval supplies up to four similar, verifier-approved training examples as demonstrations, but retrieved cases can never be cited as evidence for the current transaction. Inference is deterministic, with temperature set to zero.
Stage 3 is the deterministic verifier, the component the authors identify as the system’s grounding mechanism. It is not a learned model and cannot be trained, fine-tuned, or subtly influenced by the language model’s output. It simply executes fixed rules: does the asserted numeric comparison hold against the transaction fields, does the claimed temporal relation match the timestamps, does the asserted graph path exist in the observable graph, does the entity match check out, and is the proposed verdict logically consistent with the verified claims? If any check fails—if generation was incomplete, an evidence identifier is invalid, or a claim is unsupported—the rationale is rejected outright, its probability is excluded from the final mixer, and the transaction is escalated to human review. This same pathway is what neutralizes prompt injection: malicious text embedded in transaction fields may reach the language model, but any rationale it produces must still survive structured verification, and injected content that fails verification triggers escalation rather than automated action.
Stage 4 closes the loop with calibration. An isotonic regression mixer combines the triage probability, the verifier-gated rationale signal, and the verifier’s accept-or-reject status into a final fraud probability, which is then passed through split-conformal calibration to meet a nominal 95 percent coverage target. The authors are careful to note that the formal coverage guarantee applies only to the conformal layer under exchangeability assumptions—not to the whole framework—and that empirical miscoverage remained below the stated bounds in the reported settings. The system also trains with three auxiliary objectives: a cost-sensitive loss that weights missed fraud more heavily than unnecessary reviews, adversarial training on validity-preserving fraud edits such as transaction splitting and mule routing, and a counterfactual loss that forces rationales to change when their supporting evidence changes while remaining stable otherwise.
The empirical evaluation spans five public benchmarks. On the three primary datasets, VR-FraudNet outperformed the strongest baseline, TabTransformer, in area under the precision-recall curve: from 0.5012 to 0.5247 on the Bank Account Fraud dataset, from 0.5137 to 0.5824 on the extremely imbalanced AMLworld HI-Small graph, and from 0.7234 to 0.7456 on IEEE-CIS. Ablations show the design is not decorative: removing the language-model branch cost 2.78 and 3.52 percentage points of AUPRC on the first two datasets, removing the deterministic verifier cost 2.18 and 2.78 points, and removing the schema constraint also degraded performance. Under budgeted adversarial edits, the full system’s mean evasion rate was 0.0667 at attack budget one, 0.1016 at budget two, and 0.1672 at budget four—dramatically lower than TabTransformer’s 0.2592, 0.3692, and 0.5370 at the same budgets. Latency stayed within a 200-millisecond budget, with a p99 of 10.23 milliseconds on the common path and 175.23 milliseconds on the escalation path on the reported hardware.
The study is equally notable for what it refuses to claim. On the Elliptic++ temporal graph, performance before a simulated dark-market-shutdown shock degraded by an acceptable 2.89 percentage points, but the post-shock AUPRC fell from 0.6823 to 0.6087—an absolute reduction of 7.36 percentage points that exceeds the predeclared 5-point robustness target. The authors report this failure plainly, noting that the framework remains vulnerable to substantial distributional change. They also decline to make cross-dataset transfer claims, since the five benchmarks use incompatible feature schemas, and they caution that their adversarial results cover only four predefined edit families, not unrestricted adaptive attacks. Mule-routing modification proved the hardest attack in every budget tier, peaking at a 0.2098 evasion rate, which the authors attribute to its disruption of relational rather than purely numerical context.
What emerges is a template for how language models might safely enter high-stakes decision systems: not by trusting their prose, but by demoting them to structured proposers whose claims are checked by code that cannot be fooled by eloquence. The verifier’s acceptance means only that encoded claims satisfy the implemented checks—it does not certify completeness, legal sufficiency, or correctness beyond the schema. Yet the ablation evidence suggests that this disciplined division of labor improves not just auditability but raw detection performance, particularly under adversarial pressure. The authors are explicit that the findings support verifier-grounded fraud detection only under the evaluated public datasets and protocols, and that deployment readiness, regulatory sufficiency, and universal adversarial safety remain unproven. Future work, they note, should test the framework on institution-level streams with delayed labels, adaptive attackers, poisoned retrieval indexes, and prospective studies with the fraud investigators who would actually read the rationales. For now, VR-FraudNet offers a compelling answer to a question the generative AI era has made urgent: how to harvest the explanatory power of large language models without ever letting them grade their own homework.
Subject of Research: Verifier-grounded language models for financial fraud detection
Article Title: Grounding language models with deterministic verifiers for fraud detection
Article References: Sourav, M. S. A., Rozario, E., Islam, M. A., Chy, K. S., Akter, S., Shahiduzzaman, M., Hossain, M. S., Kabtia, M., Chakraborty, P., & Basit, A. (2026). Grounding language models with deterministic verifiers for fraud detection. Discover Artificial Intelligence, 6(1), Article 1403. https://doi.org/10.1007/s44163-026-02355-0
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02355-0
Keywords: fraud detection, large language models, deterministic verification, graph neural networks, adversarial robustness, temporal drift, probability calibration, explainable AI, machine learning, financial transactions, prompt injection, LightGBM
News Source: Denise Maddox. (October 8, 2026). AI Fraud Detector Puts a Deterministic Verifier in Charge of the Language Model. Scienmag.