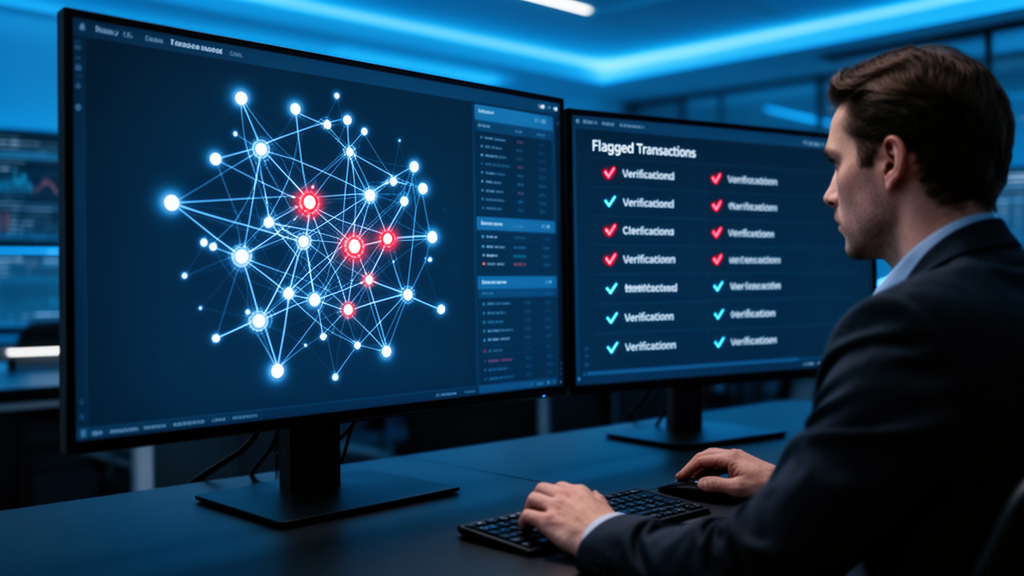
Machine learning models that flag fraudulent card transactions are getting better at ranking suspicious activity, but a new study argues that ranking alone is not enough. A team led by Mohammad Sazzad Hossain and Samia Akter has built a framework called TEMPLAR-Fraud that combines prediction, explanation, calibration and cost-aware decision-making in a single pipeline, and then audits itself before any flagged transaction reaches an analyst. The work, published as open access research in the journal Discover Data on 8 September 2026, reports controlled benchmark results on two widely used public fraud datasets rather than claims of deployment readiness.
The framework’s architecture is deliberately layered. A SAINT transformer encoder first learns a representation of each transaction, capturing interactions among numeric, categorical and temporal attributes such as amount, device, merchant and timing. A CatBoost triage model then produces an initial risk score that serves two purposes: it is an early fraud estimate, and it is a routing variable. Transactions judged confidently low-risk and unambiguous follow a fast route that skips expensive reasoning entirely. Uncertain or high-risk cases enter an escalation pathway, where a constrained symbolic template module generates a structured rationale and a deterministic verifier checks it before the case can influence the final decision.
The explanation mechanism is one of the study’s most distinctive elements. Instead of free-form generated text, which the authors warn can read fluently while citing features that were never observed or magnitudes that were never measured, the template module restricts rationales to predefined slots and admissible feature references. The deterministic verifier then checks three things: whether the rationale follows the required schema, whether every referenced feature is actually present in the transaction record, and whether numerical or categorical statements are consistent with admissible ranges. Rationales that fail are not used for automatic decisioning; the transaction is routed to human review instead. The authors stress that the verifier is a rule-based safeguard, not an oracle for explanation correctness, and that verifier failure does not mean the transaction is fraudulent or legitimate.
Downstream, the framework aggregates its available risk signals through Bayesian stacking, which combines the triage score, an optional escalation-side score and an auxiliary prediction derived from the shared embedding, with weights estimated only on validation data. A one-dimensional optimal transport calibration map, fitted on 100,000 validation-fold predictions with 256 quantile knots, then aligns predicted probabilities with observed fraud frequencies. Finally, a cost-sensitive threshold is selected on validation data by minimizing a weighted sum of false-positive, false-negative and review costs under a predefined experimental cost model. The selected thresholds were 0.034 for the first dataset and 0.033 for the second, and they remained fixed throughout all subsequent evaluations.
Evaluation was conducted on two public benchmarks with very different profiles. The first, BAF Base, contains 1,000,000 transactions of which 10,290 are fraudulent, a prevalence of 1.029 percent, with 30 mixed features over an eight-month period. The second, IEEE-CIS Fraud Detection, supplied by Vesta Corporation through Kaggle, contains 590,540 transactions with 20,663 frauds, a prevalence of 3.499 percent, and 434 features over roughly six months. Both datasets were split chronologically into 70 percent training, 15 percent validation and 15 percent test partitions, because random splitting can leak future patterns into training and produce optimistic estimates that collapse in deployment. All imputation statistics, scaling parameters, encodings and target-derived statistics were fitted strictly within the training fold, and synthetic oversampling with SMOTE was deliberately avoided because it can create temporal artifacts.
On the internal chronological test sets, TEMPLAR-Fraud achieved an AUROC of 0.918, an AUC-PR of 0.498 and an F1-score of 0.557 on BAF Base, and 0.972, 0.701 and 0.747 respectively on IEEE-CIS. The strongest baseline on both datasets was FraudGT, an edge-aware graph transformer, which reached AUROC 0.907 and 0.962. The margins over FraudGT were modest but consistent: +0.011 and +0.010 in AUROC and +0.023 and +0.025 in F1, with adjusted p-values between 0.011 and 0.029 after Holm correction. The largest absolute gains were in AUC-PR, reaching +0.027 and +0.033, although adjusted p-values for that metric were not reported. Gains over the classical tree ensembles XGBoost, LightGBM and CatBoost, and over the standalone deep tabular models SAINT and FT-Transformer and the graph model GTAN, were larger.
Performance declined for every model when evaluated on the final 10 percent of each dataset as a temporal future slice, a same-dataset stress test that the authors explicitly distinguish from independent external validation. TEMPLAR-Fraud retained AUROC 0.901, AUC-PR 0.452 and F1 0.518 on BAF Base and 0.951, 0.642 and 0.687 on IEEE-CIS, with smaller AUC-PR reductions than FraudGT on both datasets. Ablation analyses supported the layered design: removing the SAINT representation, replacing CatBoost triage with logistic regression, or swapping Bayesian stacking for mean fusion each degraded performance, with logistic-regression triage producing the largest drop. Disabling the deterministic verifier actually raised AUROC slightly, to 0.921 and 0.975, which the authors interpret as a predictive-safety trade-off rather than evidence that verification is unnecessary, since the verifier’s function is to keep unsupported rationales out of automatic decisions.
Calibration and cost outcomes were central to the study’s argument. One-dimensional optimal transport calibration reduced expected calibration error from 0.038 to 0.014 on BAF Base and from 0.037 to 0.013 on IEEE-CIS, the lowest post-calibration values among the evaluated models. At the validation-selected thresholds, the framework produced net savings of 56,485 per 100,000 evaluated transactions on BAF Base, exceeding FraudGT by 3,015 and XGBoost by 9,695, and net savings of 221,283 on IEEE-CIS against 212,078 for FraudGT. The authors are careful to state that these figures reflect author-defined experimental cost assumptions and should not be read as realized banking profit or guaranteed institutional savings. Temporal analysis of routing also showed a gradual rise in review demand across the test period, with escalation-route shares increasing from 11.6 to 15.6 percent on BAF Base and from 9.6 to 13.0 percent on IEEE-CIS.
The framework’s safeguards come at a measurable price. TEMPLAR-Fraud was the most computationally expensive method compared, with 3.1 million neural parameters plus 4,000 trees, 8.2 hours of training time and 11.6 gigabytes of peak GPU memory, against 0.6 hours and sub-millisecond latency for XGBoost. Mean inference latency was 8.3 milliseconds per transaction, split between 5.8 milliseconds on the fast route and 14.2 milliseconds for escalated cases. Under Gaussian noise, feature dropping, simulated covariate drift and adversarial stress tests including FGSM, PGD and a black-box attack, all models degraded, though TEMPLAR-Fraud retained higher discrimination and lower attack success rates than the strongest baseline under the stated protocols. Explanation-safety auditing reported SHAP fidelity of 0.762 and 0.781, verifier-routed shares of 7.8 and 6.3 percent, and verifier precision of 0.751 and 0.764 on the two datasets.
The authors are explicit about the limits of what these results show. The evaluation covers two public benchmarks, not live transaction traffic, proprietary bank pipelines or prospective analyst workflows, and the future-slice experiments are a distribution-shift proxy rather than external validation. Reported latency, memory use and review volumes may change under different infrastructure and fraud prevalence, and the study does not implement online learning or continuous prequential evaluation. The deterministic verifier reduces schema-invalid, unsupported and inconsistent rationales but cannot guarantee that accepted explanations are causally correct, and formal assessment by fraud analysts was not performed. The team points to independent institutional datasets, longer temporal streams, adaptive recalibration, analyst-in-the-loop studies and prospective deployment testing as the necessary next steps before any claim of production readiness could be made.
Subject of Research: A verifier-grounded, calibrated and cost-sensitive machine learning framework for transaction fraud detection evaluated on two public benchmarks
Article Title: TEMPLAR fraud a verifier grounded calibrated and cost sensitive framework for transaction fraud detection
Article References: Hossain, M. S., Akter, S., Chy, K. S., Islam, M. A., Shahiduzzaman, M., Kabtia, M., Sourav, M. S. A., & Raihan, D. I. (2026). TEMPLAR fraud a verifier grounded calibrated and cost sensitive framework for transaction fraud detection. Discover Data, 4(1), Article 20. https://doi.org/10.1007/s44248-026-00117-y
Image Credits: AI Generated
DOI: 10.1007/s44248-026-00117-y
Keywords: fraud detection, machine learning, TEMPLAR-Fraud, explainability, calibration, cost-sensitive thresholding, BAF dataset, IEEE-CIS, Bayesian stacking, SAINT, CatBoost, temporal drift
News Source: Denise Maddox. (October 28, 2026). New fraud detection framework pairs machine predictions with machine-checked explanations. Scienmag.