Large language models are increasingly used by clinicians for decision support, medical question answering, and automated document writing, yet they remain prone to hallucination, generating confident statements that have no basis in the underlying evidence. A new study published in Scientific Reports proposes a unified framework, called CARE-Med, that combines retrieval, generation, and verification in a single pipeline designed to make medical LLM outputs safer and more reliable.
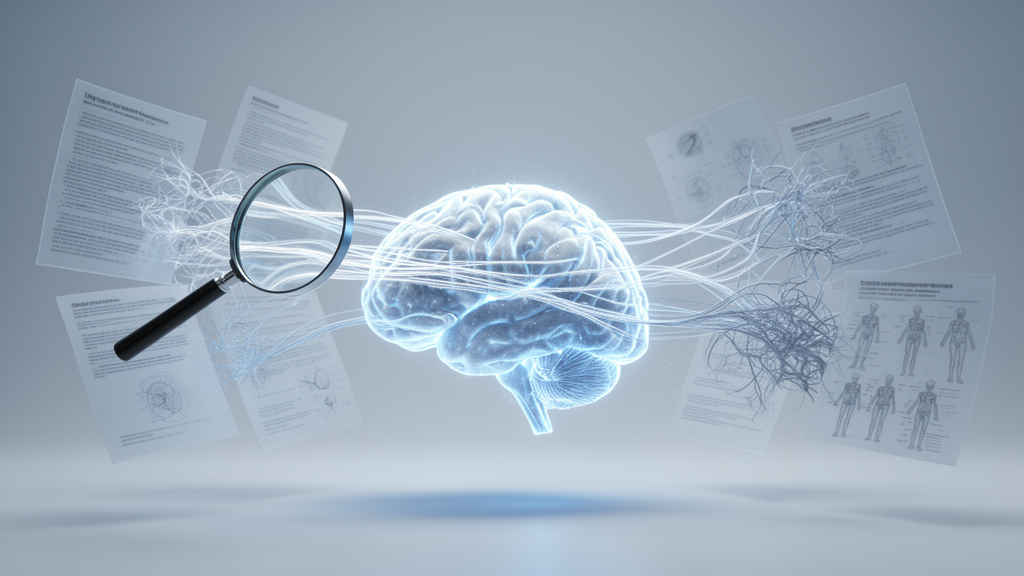
The framework addresses a known weakness of standard retrieval-augmented generation, or RAG. While RAG improves factuality by supplying relevant documents to the model, it does not guarantee that the generated response is actually consistent with those supporting documents. CARE-Med reframes the problem of reducing unsupported responses, measured with natural language inference (NLI) methods, as a confidence-aware inference task. It layers three components on top of the generator: dense retrieval to fetch relevant biomedical evidence, NLI-based verifiers that check whether each generated claim is entailed by that evidence, and a confidence scoring mechanism that weighs how trustworthy the final output should be considered.
The authors validated their approach on three widely used biomedical benchmarks: MIMIC-III, PubMedQA, and BioASQ. The results show substantial reductions in the NLI-based unsupported-response rate. The baseline LLM produced unsupported responses at a rate of 32 percent, while CARE-Med brought this down to 10 percent, a 22-percentage-point improvement that corresponds to a 68.8 percent relative reduction. Compared with conventional RAG, the gains remain clear: the unsupported-response rate fell from 21 percent to 10 percent, an 11-percentage-point drop, or a 52.4 percent relative reduction.
According to the study, the improvement comes from combining explicit verification with uncertainty reasoning, so that the system not only checks its claims against retrieved evidence but also accounts for how confident it should be in each output. The authors argue that this dual mechanism is what allows the framework to meet the stricter reliability requirements associated with safe clinical deployment, where an unsupported statement in a clinical context could carry real safety risks.
The findings suggest that retrieval alone is not sufficient for trustworthy medical AI, and that pairing dense retrieval with NLI verification and confidence scoring can meaningfully close the gap between fluent generation and evidence-consistent output. The work was published as an open-access article on 26 October 2026 by Sudheer Reddy and Shirina Samreen, and the published version notes that the early-release text is subject to further editorial edits before the final Version of Record replaces it.
Subject of Research: A hybrid retrieval–verification framework for reducing hallucinations in medical large language models
Article Title: Hybrid retrieval–verification framework for hallucination reduction in medical LLMs
Article References: Reddy, S., & Samreen, S. (2026). Hybrid retrieval–verification framework for hallucination reduction in medical LLMs. Scientific Reports. https://doi.org/10.1038/s41598-026-75909-y
Image Credits: AI Generated
DOI: 10.1038/s41598-026-75909-y
Keywords: large language models, hallucination, retrieval-augmented generation, natural language inference, clinical decision support, CARE-Med, MIMIC-III, PubMedQA, BioASQ, confidence scoring, biomedical AI, Scientific Reports
News Source: Denise Maddox. (October 27, 2026). Hybrid retrieval and verification framework cuts hallucinations in medical AI. Scienmag.