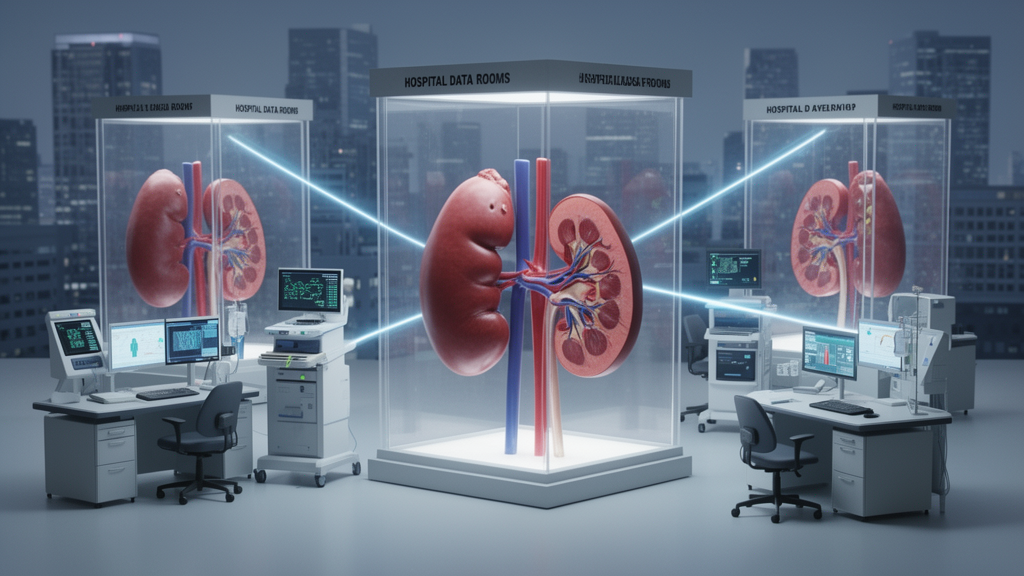
A privacy-preserving federated framework classified chronic kidney disease with mean cross-validation accuracy of 98.85% and an F1-score of 98.58% in a study based on a 400-patient benchmark dataset. The system trains separate ensemble models at three simulated hospital clients, combines their prediction probabilities without exchanging patient records, and adds Gaussian noise before aggregation. It also uses federated SHAP explanations and a simulated communication-reduction strategy. The results suggest that decentralized CKD prediction can combine high discrimination with data-sharing controls, but the findings come from small or synthetic datasets and simulated clients rather than a live multi-hospital deployment.
The study’s central model combines three tree-based algorithms—Extra Trees, LightGBM and CatBoost—through a logistic-regression meta-learner. Before modelling, the researchers used a diversity-aware pipeline to handle missing laboratory values, categorical variables, skewed measurements and redundant features. Iterative imputation was applied to variables with moderate missingness, while K-nearest-neighbour imputation, with five neighbours, was used for more incomplete variables. Robust scaling reduced the influence of outliers, and mutual-information filtering retained 15 attributes from an initial set described in the paper as 25 after the target variable was removed from the 26-variable dataset.
Each simulated client trained its own copy of the stacking model on a subset containing 134, 134 and 132 records. The clients included 83, 84 and 83 CKD cases respectively, with the remainder classified as non-CKD. Rather than sending model parameters or patient-level observations to a central server, each client transmitted calibrated prediction probabilities. The server averaged these outputs to produce a global classification. This prediction-level design simplified aggregation across different model instances, although it did not amount to continuous collaborative model training of the kind used in many federated-learning systems.
To limit information that might be inferred from shared probabilities, the framework first applied temperature scaling and then added Gaussian noise with standard deviations of 0.01, 0.05, 0.10 or 0.30. It then normalized the perturbed probabilities and averaged them across clients. With δ fixed at 10−5 and unit sensitivity assumed, the corresponding approximate privacy budget decreased from ε = 484.48 at the lowest noise level to ε = 16.15 at the highest. Accuracy declined from 98.80% to 97.00% across that range, while F1 fell from 98.50% to 96.80%. Thus, the measured utility was relatively stable, but the estimated privacy budgets were high under the stated assumptions.
Robustness was tested separately by adding Gaussian noise with a standard deviation of 0.05 to the preprocessed input features, a perturbation intended to represent measurement variability. Accuracy under noisy conditions was 97.50%, about 1.3 percentage points below the unperturbed result, with the F1-score showing a similar decline. Cross-client evaluation produced accuracies above 99%, including a reported maximum of 99.25%. Because all clients were partitions of the same 400-record benchmark with relatively balanced class distributions, these results indicate consistency across artificial data splits rather than generalization among genuinely independent hospitals or patient populations.
Discrimination and calibration were also strong in the study. The framework achieved a ROC-AUC of 0.998 and a precision-recall AUC of 0.997, while its Brier score was 0.00038. The calibration curve reportedly followed the diagonal reference closely. These measures were accompanied by a 95% confidence interval of 0.982 to 0.995 for one reported performance estimate. However, Wilcoxon signed-rank comparisons between the proposed model and baseline classifiers did not reach statistical significance at the 95% level. The authors attributed this partly to the benchmark’s small size and consistently high scores, meaning the added privacy and explainability functions should not be interpreted as having improved predictive accuracy beyond comparable centralized models.
For interpretability, SHAP values were calculated locally using each client’s own data and background distribution. Patient-level explanations and background samples remained at the client, while only mean absolute feature-importance values were aggregated centrally. The global analysis ranked red blood cells, albumin, specific gravity, hypertension and packed cell volume among the most influential variables, with substantial overlap in the highest-ranked features across clients. Haemoglobin replaced packed cell volume in the leading group at the third client. The authors described these patterns as clinically meaningful, but the SHAP aggregation itself did not receive differential-privacy noise, which they identified as an important subject for future work.
The communication analysis estimated that a baseline round required 0.82 MB. Simulating generic compression at a 50% reduction lowered the estimate to 0.41 MB, and combining this with a simulated sparse-update factor of 30% produced 0.25 MB, about 70% less than the baseline. These savings were calculated from serialized model sizes rather than measured with concrete compression algorithms or a functioning low-bandwidth network. The experiments were run in Python with Scikit-learn, LightGBM, CatBoost and SHAP on a computer containing an Intel Core i7 processor and 24 GB of memory, without a GPU, indicating that the tested pipeline did not require specialized acceleration in that environment.
When the complete pipeline was applied to two additional datasets, accuracy fell to 92.53% on a 1,659-record CKD dataset and 92.11% on a 2,059-record dataset, although F1-scores remained 96.07% and 95.58%, respectively. One of these sources was explicitly described as synthetic. The authors also noted that preprocessing steps had not all been confined to training folds within the cross-validation and federated pipeline, and they proposed fold-wise imputation, scaling and feature selection for future work to reduce possible leakage. These qualifications, along with the modest number of simulated clients and binary classification task, mean that the study establishes a promising computational proof of concept rather than verified clinical readiness.
Subject of Research: Federated explainable machine learning for privacy-preserving chronic kidney disease prediction
Article Title: A privacy preserving federated meta ensemble stacking framework with explainability and differential privacy for chronic kidney disease prediction in resource constrained settings
Article References: Napa, K. K., Sathyanarayanan, D., Purushothaman, R., Allasi, H. L., Soosaimariyan, M. V., Karunakaran, C., & Rao, M. S. (2026). A privacy preserving federated meta ensemble stacking framework with explainability and differential privacy for chronic kidney disease prediction in resource constrained settings. Discover Artificial Intelligence, 6(1), Article 1035. https://doi.org/10.1007/s44163-026-02143-w
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02143-w
Keywords: chronic kidney disease, federated learning, differential privacy, explainable AI, machine learning, healthcare data, ensemble stacking, SHAP, privacy-preserving analytics, privacy, preserving, federated
News Source: Jerry Hayes. (October 22, 2026). Federated ensemble framework predicts chronic kidney disease without sharing records. Scienmag.