A data-efficient pyramid vision transformer that combines knowledge distillation with linear spatial reduction attention achieved the highest reported accuracy and F1-score among the models compared on three low-resolution image-classification benchmarks. In the authors’ experiments, the model, called DE-PVT, recorded an accuracy of 91.54% and an F1-score of 90.92% on ImageNet-1K images resized to 32 × 32 pixels. It achieved 97.76% for both accuracy and F1-score on CIFAR-10 and 94.59% for both metrics on CIFAR-100.
The study was published in 2026 as an open-access research article. These results apply to the authors’ 32 × 32-pixel experimental setting and do not directly establish performance at the standard 224 × 224-pixel resolution used in many ImageNet evaluations. The design targets two constraints associated with vision transformers.
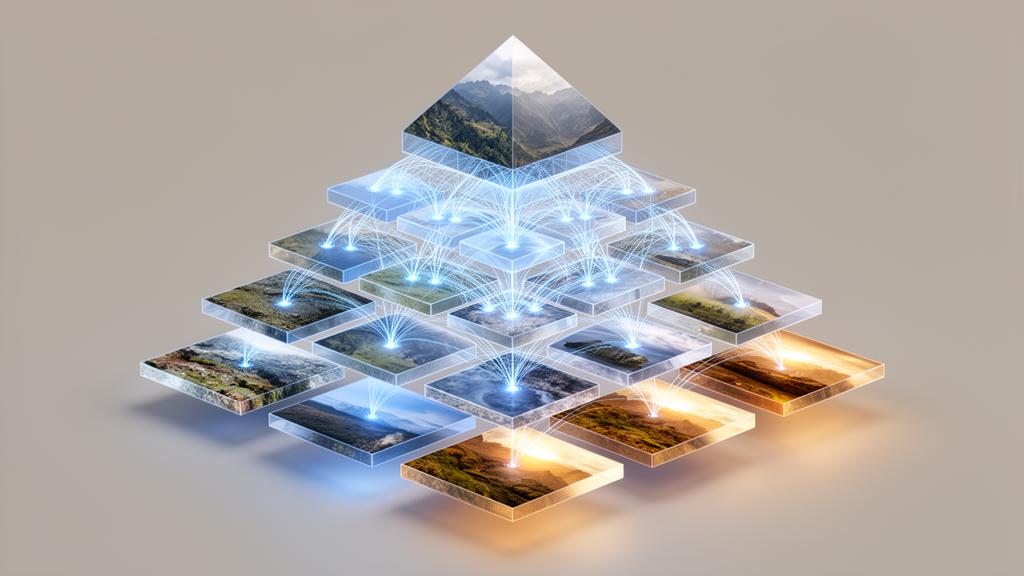
Conventional self-attention compares every token with every other token, producing a computation term that grows quadratically with the number of patches, while many transformer architectures also require large training datasets to achieve their strongest results. DE-PVT addresses the first constraint by replacing standard multi-head self-attention with linear spatial reduction attention, and it addresses the second through teacher–student training. The student is a hierarchical transformer built from four stages of overlapping patch embedding and transformer encoding.
A lightweight convolutional neural network serves as the teacher during training, transferring information to the student without requiring a large pretrained teacher at inference time. Input images are divided into overlapping patches through a convolution with a stride of S, a kernel size of 2S − 1 and padding of S − 1. Adjacent patch windows therefore share half their area, which the authors call soft splitting.
Each patch is normalized and projected into a visual token. The token sequence also contains a trainable classification token and a distillation token, allowing the transformer to represent both ordinary class prediction and knowledge learned from the teacher. In the first stage, a 32 × 32 × 3 image is divided into 64 patches of 4 × 4 pixels and projected to a feature dimension of 64; the two added tokens bring the sequence length to 66.
Later stages use strides of 2 to produce progressively coarser feature maps, while four identical transformer encoders are used at each stage. Linear spatial reduction attention preserves the query feature map at its original resolution but reduces the spatial dimensions of the key and value maps by average pooling them to a fixed P × P size. The number of key–value pairs is therefore constant as the number of image patches grows.
Standard self-attention has an estimated complexity of 4Nc² + 2N²c, where N is the number of tokens and c the channel dimension, whereas the reduced-attention calculation becomes 4Nc² + 2NP²c. With P fixed, both terms scale linearly with N. The authors’ calculations gave DE-PVT’s student network 78,292 multiply-accumulate operations in total, compared with 9,040,326 for the evaluated DeiT configuration and 329,236 for PVT version 1; the corresponding encoder-block counts were 30,592, 740,829 and 66,560. These are the study’s operation-count comparisons, not direct measurements of energy use or wall-clock time on every computing platform.
The teacher network contains 10 layers and uses conventional convolution alongside depthwise and pointwise convolution. Depthwise convolution processes spatial information independently within each channel, while pointwise convolution combines features across channels. The teacher is trained with CutOut, CutMix and MixUp augmentation, which respectively mask an image region, exchange regions between two images, and blend two images and their labels.
The lightweight teacher was reported to contain 12,769 parameters, and its classification accuracies were 85.00% on ImageNet-1K at 32 × 32 resolution, 91.23% on CIFAR-10 and 88.85% on CIFAR-100. It participates in training through a distillation loss but is not called during inference, so the final test-time result is not a teacher–student ensemble. The source describes the teacher as helping convey fine-grained information to the student through the distillation token and reducing the total cross-entropy loss.
Training combines two cross-entropy objectives. One measures the classification token’s predictions against the true labels, while the other treats the teacher’s probability distribution as a soft target for the distillation token. A weighting parameter determines how much each loss contributes, with 0.5 producing the best accuracy and F1-score in the authors’ tuning experiment.
At test time, the outputs of the classification and distillation heads are also combined with equal weighting, yielding 0.5 for each. The network was trained for 85 epochs with AdamW, a learning rate of 0.001 and a batch size of 256. Its transformer encoder replaces global self-attention with linear spatial reduction attention, followed by a multilayer perceptron containing a 3 × 3 depthwise convolution, GELU activation, residual connections and normalization.
The experiments were implemented in Python with TensorFlow and Keras on Google Colab. Ablation experiments indicated that each major component contributed to the reported performance. Adding teacher–student distillation increased F1-score over the comparison with the standard pyramid vision transformer by 6.97 percentage points on ImageNet-1K at 32 × 32 resolution, 5.63 points on CIFAR-10 and 8.30 points on CIFAR-100.
Comparing linear spatial reduction attention with the self-attention-based DeiT configuration produced F1-score gains of 6.59, 6.09 and 7.47 points across the same datasets. Overlapping patch embedding contributed gains of 2.27, 2.54 and 2.2 points. GELU performed better than the other tested MLP activation functions, while adding depthwise convolution to the MLP raised F1-score by 3.99, 3.96 and 3.71 points.
The customized teacher also outperformed the ResNet-50 and conventional CNN alternatives examined by the authors in the reported comparisons. Timing comparisons favored DE-PVT as well. The paper reports a training time of 120 seconds per epoch and an inference time of 5.2 milliseconds per image, describing these as the lowest and fastest values among ViT, DeiT and PVT version 1 in its experimental setup.
Relative to those three comparators, the reported training-time reductions were 33%, 20% and 14%, while inference-time reductions were 37%, 32% and 29%. These measurements were made within the study’s software and hardware environment and should not be interpreted as universal speed differences across devices or implementations. The paper also visualizes attention maps on three samples and reports that linear spatial reduction attention preserved significant pixels in target regions where self-attention removed them, although it explicitly describes this evidence as qualitative and identifies quantitative attention analysis as future work.
The results suggest that combining a compact convolutional teacher, overlapping local representations, hierarchical feature processing and reduced attention can produce strong classification results at 32 × 32 resolution. Nevertheless, important limits remain. Every experiment used 32 × 32-pixel inputs because of GPU memory constraints and consistency across the three datasets; empirical scaling tests at 64 × 64, 128 × 128 and 224 × 224 were not conducted.
The evaluation covered classification only, not object detection or segmentation, and the authors report mean results with standard deviations over five runs but no formal statistical-significance tests. Quantitative attention measures such as entropy and token sparsity were also left for future work. The evidence therefore supports DE-PVT as a promising low-resolution classification architecture, while its performance on higher-resolution images, dense-prediction tasks and broader real-world datasets remains unverified.
Subject of Research: Evaluation of a data-efficient pyramid vision transformer for low-resolution image classification
Article Title: A data efficient pyramid vision transformer for image classification
Article References: Ferdous, G. J., Chowdhury, M. H., Hossain, M. A., & Dewan, M. A. A. (2026). A data efficient pyramid vision transformer for image classification. Discover Artificial Intelligence, 6(1), Article 1104. https://doi.org/10.1007/s44163-026-02100-7
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02100-7
Keywords: vision transformers, image classification, knowledge distillation, linear attention, data efficiency, CIFAR-10, CIFAR-100, ImageNet-1K, teacher-student learning, computational complexity, data, efficient
News Source: Denise Maddox. (October 26, 2026). Pyramid vision transformer cuts attention cost and boosts image classification. Scienmag.