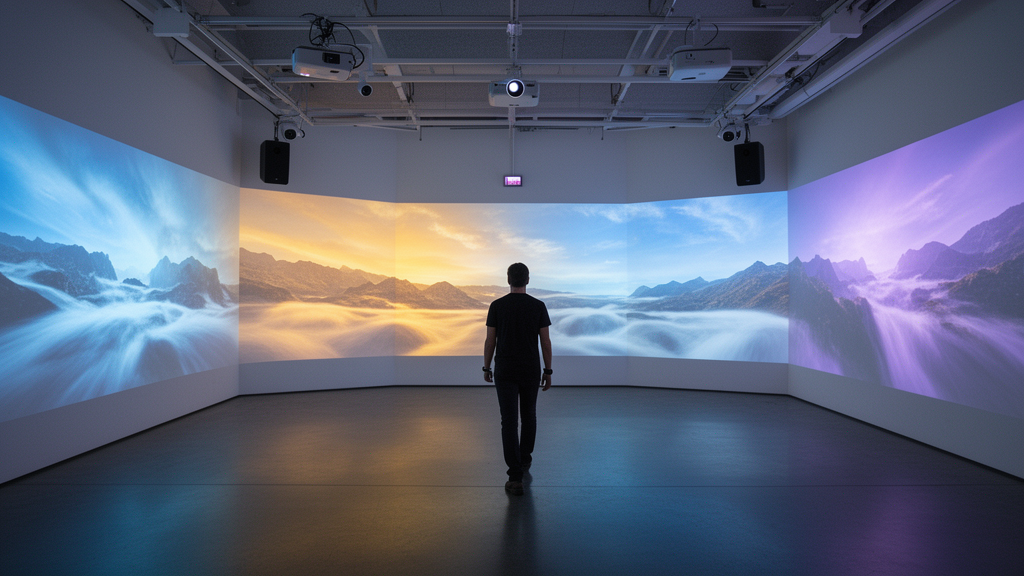
A physiology-driven control system can decode visitors’ emotional states and adjust exhibition lighting, sound, projection, scent, and interactive equipment with policy-inference latency of 7.8 milliseconds, according to a 2026 study combining laboratory datasets, a digital-twin simulator, and a field test in a 40-square-metre exhibition hall. Its hierarchical attention fusion network, called SAF-Net, classified emotional valence with 92.7% accuracy and arousal with 93.5% accuracy in subject-independent testing. The authors also report that the adaptive control strategy, DRL-ADT, outperformed static and alternative reinforcement-learning controls in the digital-twin simulation. These findings apply to the study’s selected datasets, simulated visitors, prototype system, and 30-person field experiment; they do not establish that emotion-sensing systems can autonomously improve every real exhibition.
The central problem is that immersive halls usually depend on explicit inputs such as controllers, touchscreens, and voice commands, which can interrupt attention and reveal little about a visitor’s rapidly changing emotional state. The proposed alternative creates a four-stage loop: multimodal perception, emotional decoding, reinforcement-learning decision-making, and spatial response. Physiological signals including electroencephalography, electrocardiography, galvanic skin response, and eye tracking are converted into valence and arousal estimates, which become feedback for an agent that chooses how to modify the environment. The system therefore treats the exhibition as something that can respond continuously to a participant rather than a sequence of manually selected scenes.
SAF-Net was designed to cope with signals that differ sharply in sampling rate, dimensionality, noise, and temporal behaviour. Electroencephalography was filtered from 0.5 to 50 hertz, divided into one-second segments, and transformed into features describing band power, differential entropy, spatial patterns, sample entropy, and Lempel–Ziv complexity. Wavelet processing and R-wave detection produced electrocardiography features such as heart rate and heart-rate variability, while filtered skin-conductance data yielded baseline and response measures. Sliding-window normalization and temporal alignment reduced differences in units and individual baselines. The model then used separate convolutional branches, staged fusion and separation, two Transformer layers, and dual-pooling cross-attention to combine neural, autonomic, and temporal information.
Attention was applied at two levels because the authors reasoned that transient emotional peaks and sustained emotional baselines carry different information. Max pooling was intended to preserve short-lived arousal responses, while average pooling represented more stable valence patterns. A reduction factor and Swish activation were used in the staged separation process to limit the tendency of the higher-dimensional EEG branch to dominate peripheral signals. In ablation tests, replacing staged fusion and separation with direct concatenation lowered arousal accuracy from 93.5% to 86.2%. Removing dual-pooling cross-attention reduced the macro F1 score by 5.4%, while reverting Swish and adaptive reduction to ReLU and fixed reduction factors lowered overall accuracy to 88.1%, according to the reported analysis.
For adaptive control, the researchers formulated the exhibition as a continuous-control problem and used Soft Actor-Critic, an algorithm whose objective combines cumulative reward with policy entropy. The state combined six emotional variables, environmental settings, and six behavioural variables, including dwell time, gaze, blink frequency, and position. The eight action dimensions represented changes in overall lighting, red, green and blue channels, volume, projection, scent, and interactive devices. Its reward function rewarded positive and moderately arousing states, penalized sharp emotional and environmental changes, and promoted dwell time up to a specified ceiling. Continuous adjustments were passed through a low-pass filter, while a KL-divergence threshold of 0.05 constrained policy updates to limit abrupt changes.
Several additional mechanisms were intended to make online learning safer and more personal. When the difference between actual and predicted emotional valence exceeded a threshold of 0.2, the system reduced action magnitude by 50% and increased sampling in the uncertain region. Per-action confidence estimates suppressed dimensions judged especially sensitive. A preference vector was updated from finite-difference estimates of how environmental actions changed valence, with a learning rate of 0.01. The authors report that this vector converged in approximately 50–100 decision cycles in the simulation, although the simulated responses came from parameterized heuristics rather than observed relationships between real visitors and exhibition controls.
Most control results came from a digital twin containing a GRU model of emotional dynamics, literature-derived functions linking environmental settings to emotion, and simulated actuator lag for lights, audio, and scent. Five virtual profiles represented different visitor sensitivities. Each simulated visit lasted 25 minutes, equivalent to 1,500 one-second decision steps, and the policy was pre-trained for 500,000 steps with five random seeds. In this environment, DRL-ADT produced an immersion score of 8.9 ± 0.5 and an arousal score of 6.8 ± 0.6, both the highest among the tested strategies. Its total immersion score was 44.6 ± 2.5, compared with 38.2 ± 3.1 for PPO-RL, 35.4 ± 3.6 for PID-CT, and 31.2 ± 4.7 for a static environment. These are model-generated measures, not ratings supplied by human participants.
Hardware tests were performed on a Jetson AGX Orin edge server, with latency measured across 30 independent runs of 10,000 decision cycles. DRL-ADT averaged 7.8 ± 0.3 milliseconds, with a 95% confidence interval of 7.5–8.1 milliseconds, using GPU computation and TensorRT optimization. CPU-only execution took 18.9 milliseconds, GPU execution without TensorRT took 10.6 milliseconds, and an RTX 4090 workstation took 5.1 milliseconds. The 7.8-millisecond value represents policy inference alone, not the complete sensor-to-actuator path; the study states that the latter remained below 300 milliseconds for electronic lighting, audio, and projection channels. Average processor load was reported as 28.6%, and memory use as 216 megabytes.
In the physical exhibition, the researchers used non-contact behavioural sensing rather than asking visitors to wear physiological equipment, which they said could itself disrupt immersion. Thirty participants were randomly assigned to individual or paired visits, with 10 participants completing the paired condition. An overhead ultra-wideband positioning system and RGB-D cameras recorded trajectories, turning, dwell time, and spatial coverage. A bracelet occasionally prompted visitors to provide brief arousal ratings after they had remained at an exhibit for more than 45 seconds. During control, facial features and positioning data served as proxies for the reinforcement-learning state, meaning the field test did not validate the full physiological decoding pipeline under live conditions. DRL-ADT was associated with an average exhibit dwell time of 24.3 seconds, compared with 16.5 seconds under static control, and an arousal-score decline of 0.4 points after 15 minutes, compared with 1.8 points under static control.
The paired-visit test recorded 18 spatial-conflict events, defined by proximity below 1.2 metres while the visitors were looking in different directions. The system reported an 83.3% conflict-mitigation success rate, using local spotlighting and directional audio in response to the observed focus of one visitor. That result remains preliminary: the study used a small sample, proxy signals, one prototype hall, and relatively short visits. Privacy was addressed by keeping trajectories and facial features on the edge server, encrypting them locally, discarding raw video, and avoiding cloud transmission. The authors also identify unresolved problems, including sensor comfort, cold starts for new users, multi-user control, privacy for continuous physiological data, and the need to calibrate simulator responses with real observations. The clearest supported result is therefore technical rather than universal: combining staged multimodal fusion with carefully constrained reinforcement learning can support fast, smoothly adjusted exhibition responses, while each component still requires validation under realistic, privacy-conscious and larger-scale conditions.
Subject of Research: Closed-loop emotion sensing and reinforcement-learning control for immersive exhibition spaces
Article Title: Adaptive optimization and interaction method for immersive exhibition space experiences integrating multimodal physiological sensing
Article References: Li, S., & Ye, Y. (2026). Adaptive optimization and interaction method for immersive exhibition space experiences integrating multimodal physiological sensing. Discover Artificial Intelligence, 6(1), Article 1160. https://doi.org/10.1007/s44163-026-02246-4
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02246-4
Keywords: multimodal emotion recognition, physiological sensing, reinforcement learning, immersive exhibitions, adaptive environments, electroencephalography, soft actor-critic, edge computing, Adaptive, optimization, interaction, method
News Source: Denise Maddox. (October 26, 2026). Physiology-driven system adapts immersive exhibition spaces in real time. Scienmag.