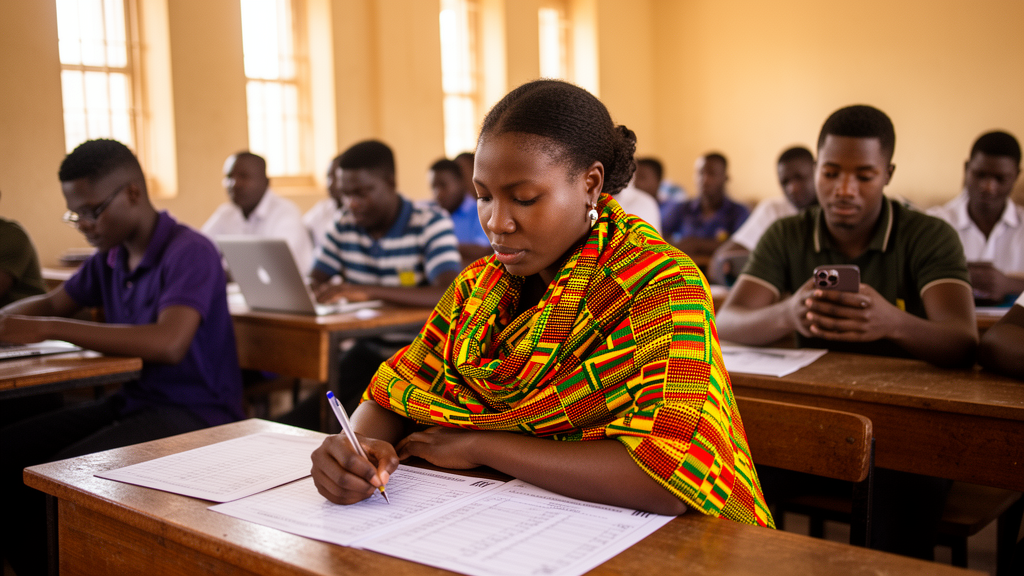
A cross-sectional survey of 408 students at six Ghanaian higher education institutions has put a proposed 23-item measure of student susceptibility to artificial intelligence through its first formal statistical evaluation, and the results are deliberately double-edged. The Student Susceptibility to AI (SAI) index was designed to capture four dimensions of academic risk: Over-Reliance, Misuse/Academic Integrity, Cognitive Vulnerability, and a protective dimension called Resilience & Reflection. Three of the four subscales showed acceptable internal consistency and clear factorial identity. The fourth, Misuse/Academic Integrity, fell well short of conventional reliability standards, and the study’s authors conclude that the item pool is promising but not yet stable, requiring revision and independent confirmation before it can be treated as a validated instrument.
The context for the measurement exercise is striking in itself. Among the students surveyed between September and November 2025, generative AI use was already near-universal: 65.7 percent reported daily use and only 2.0 percent reported none. The authors argue that this saturation changes the measurement task fundamentally. Instruments asking whether students use AI have little discriminatory power left in such populations; the meaningful variance now lies in how students use these tools and what safeguards they apply. The SAI item pool was built for that second task, drawing on the Technology Acceptance Model, Protection Motivation Theory and cognitive reflection frameworks to shape its four theoretically motivated dimensions.
The central psychometric question was how many factors underlie the item responses, and the evidence did not converge on one answer. The Kaiser-Meyer-Olkin measure of sampling adequacy was 0.826 and Bartlett’s test of sphericity was significant, confirming the data were factorable. Three eigenvalues exceeded both the Kaiser criterion and the 95th percentile from parallel analysis based on 1000 random datasets. The fourth eigenvalue, at 1.18, passed the Kaiser criterion but fell below the parallel analysis threshold of 1.31, giving only marginal empirical support for a fourth factor. Velicer’s Minimum Average Partial test reached its minimum at 22 components and offered no usable guidance. Both three- and four-factor solutions were therefore extracted and reported side by side.
The four-factor solution was carried forward for provisional interpretation on three grounds: its alignment with the theoretically specified framework, a small reduction in large residual correlations (183 of 253 residuals exceeding |0.05|, against 188 for the three-factor solution), and an additional 1.7 percent of variance explained, 54.2 percent against 52.5 percent. But the authors are explicit that this was a theory-led decision rather than an empirical result. The four-factor solution carried seven items with cross-loadings above 0.30, against three in the three-factor solution, and its root mean square residual was marginally higher, 0.1734 against 0.1626. Confirmatory testing in an independent sample is required to adjudicate between the two structures. In the three-factor solution, Over-Reliance and Misuse/Academic Integrity merged into a single dimension while Cognitive Vulnerability and Resilience & Reflection remained distinct.
Reliability results split cleanly along the same lines. Over-Reliance achieved a Cronbach’s alpha of 0.821, Cognitive Vulnerability 0.807 and Resilience & Reflection 0.824, with McDonald’s omega total values closely matching. Misuse/Academic Integrity, however, returned an alpha of just 0.535, and an omega total of 0.682, both below the conventional 0.70 threshold. The authors suggest a substantive reason: academic misconduct items ask respondents to report socially undesirable intentions, leaving them vulnerable to defensive responding and to genuine disagreement over what counts as misuse. Future development of this dimension may need behaviourally anchored or scenario-based formats that reduce reliance on each respondent’s private definition of misconduct.
A second structural finding carries the study’s most theoretically interesting implication. The three risk dimensions correlated moderately with one another, with r ranging from 0.37 to 0.49, but Resilience & Reflection showed only near-zero to weak negative correlations with them, between −0.22 and −0.05. Reflective practice is therefore not simply the low end of susceptibility. Students may be heavy, dependent users of AI who nonetheless verify output, and light users who do not. This near-independence also undermined any case for a total SAI score: the explained common variance for a general factor was just 0.373, well below the 0.50 benchmark, and summing three risk dimensions with one protective dimension would erase precisely the distinction the data reveal. The authors recommend subscale-level reporting only.
Group comparisons, corrected for false discovery rate across sixteen omnibus tests, produced twelve surviving results. The most robust difference lay on the protective dimension: male participants scored lower on Resilience & Reflection than female participants, d = −0.32 with a 95 percent confidence interval of [−0.54, −0.13] and an adjusted p of 0.004, meaning they reported less frequent verification and critical appraisal of AI output. Differences by study level produced the largest raw effect estimates, with undergraduate–postgraduate contrasts reaching d = −1.50 for Over-Reliance, but the postgraduate subsample contained only 20 participants, making these estimates unstable and unsuitable for inference.
The more trustworthy basis for interpretation, the authors argue, is the multivariable regression in which gender, age, study level and AI use frequency were entered simultaneously. The models explained only 2.7 to 7.9 percent of variance in subscale scores, indicating that demographic position is a weak predictor of AI-related susceptibility in this sample. Undergraduate status predicted lower Over-Reliance (B = −0.28, p = .002) and lower Resilience & Reflection (B = −0.43, p < .001); male gender predicted lower Resilience & Reflection (B = −0.25, p = .010); age predicted higher Cognitive Vulnerability (B = 0.25, p < .001); and AI use frequency weakly predicted higher Misuse/Academic Integrity scores (B = 0.08, p = .014). That last association is cross-sectional and cannot establish direction: frequent use may erode restraint, or students already permissive about AI-assisted work may simply use the tools more. The authors also note that reflective verification practices proved largely independent of the risk dimensions, suggesting interventions should target how students interrogate AI output rather than how often they consult it, though this remains a hypothesis to be tested rather than an established recommendation.
The study quantified institutional clustering but could not model it. Intraclass correlations across the six institutions ranged from 0.56 to 0.77, indicating that institutional context, policy environment, teaching practice and infrastructure, accounts for a meaningful share of the variation in susceptibility scores. With only six clusters, multilevel modelling was not feasible, so the finding is reported descriptively, with a clear design implication for the next study. All 23 items also showed floor or ceiling effects exceeding 15 percent, concentrated as floor effects in risk items and ceiling effects in reflective items, which may reflect genuine population tendencies, socially desirable responding, or both, and which reduces sensitivity at the distribution’s extremes.
The limitations are extensive and acknowledged in detail. No pilot testing preceded the survey, and a single sample informed item evaluation, factor extraction, scoring decisions and subgroup comparison, creating a risk of capitalisation on chance. Participants were recruited by convenience sampling, one institution contributed over half the sample, and the findings describe only the students who took part rather than Ghanaian higher education as a whole. A sensitivity analysis using Spearman correlations found the factor structure held but individual loadings differed by a mean absolute value of 0.36, showing the estimates are sensitive to the correlation method. Convergent and discriminant validity require external criterion measures that were not available. What the study establishes is a measurement contribution and an agenda: a theoretically specified, empirically diagnosed starting point for assessing AI-related academic risk in an African higher education setting where such instruments have been absent, with the next cycle requiring revised items, polychoric estimation, confirmatory analysis in an independent sample, measurement invariance tests and criterion data.
Subject of Research: Development and exploratory validation of a psychometric index measuring student susceptibility to artificial intelligence risks in Ghanaian higher education
Article Title: Development and exploratory validation of the student susceptibility to artificial intelligence (SAI) index among higher education students in Ghana
Article References: Sanche, S., Osisiogu, E. U., Allou, F., & Amemo, R. E. (2026). Development and exploratory validation of the student susceptibility to artificial intelligence (SAI) index among higher education students in Ghana. Discover Artificial Intelligence, 6(1), Article 1604. https://doi.org/10.1007/s44163-026-02569-2
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02569-2
Keywords: artificial intelligence, higher education, Ghana, psychometrics, exploratory factor analysis, over-reliance, academic integrity, cognitive vulnerability, reflective practice, scale development, cross-sectional survey, Development
News Source: Denise Maddox. (October 23, 2026). New Ghana study tests a four-part measure of student susceptibility to AI. Scienmag.