An experimental study of the I-YOLOv8-MCGIRNet model found that the combined system achieved mean average precision at an intersection-over-union threshold of 0.5 of 0.966 on the PetFace pig subset and 0.955 on the FIRC dataset. The model, which combined improvements to YOLOv8 with a multi-constraint ghost inverted residual network, also produced higher measured recognition, detection and counting performance than the comparison models across the conditions evaluated.
This was a computational model-development and benchmarking study rather than a review or clinical investigation. Its scope included pig-face images from the PetFace pig subset and the FIRC dataset, which the authors divided into training, validation and test sets at a ratio of 7:2:1. Data augmentation included random flipping, random cropping and color-gamut transformation to represent variations such as backlighting, low light, occlusion and changes in posture. All comparison models used fivefold cross-validation, and the researchers used an independent-samples t test to assess differences between groups.
On the PetFace data, I-YOLOv8-MCGIRNet recorded precision of 0.956, recall of 0.948 and [email protected]:0.95 of 0.897. The reported p-values for comparisons with the other models were below 0.05. In separate performance-and-efficiency comparisons, the model used 15 million parameters and produced [email protected] of 0.966 on PetFace. Comparative results reported for that dataset included approximately 0.933 for YOLOv8s-MCGIRNet, 0.947 for I-YOLOv8-Swin Transformer and 0.885 for Faster R-CNN, whose model size was about 68 million parameters.
The FIRC results showed a similar pattern. I-YOLOv8-MCGIRNet achieved [email protected] of 0.955 with 15 million parameters. The reported [email protected] values were 0.924 for YOLOv8s-MCGIRNet, 0.937 for I-YOLOv8-Swin Transformer and 0.875 for Faster R-CNN. An ablation experiment attributed successive gains to the global attention module, BiFPN feature fusion, CIoU loss and MCGIRNet. Embedding MCGIRNet increased [email protected] to 0.966 while reducing the model to 15 million parameters, according to the study.
Under the researchers’ definition of recognition consistency, the model’s value increased from about 90.9% to 94.5% in normal lighting, from 87.9% to 94.8% in dark light below 200 lux and from 85.4% to 92.7% under backlighting with a light-intensity difference above 800 lux. The computational tests reported 16.32 GFLOPs for I-YOLOv8-MCGIRNet, compared with 19.68 for YOLOv8s-MCGIRNet, 22.75 for I-YOLOv8-IRNet, 47.21 for I-YOLOv8-Swin Transformer and 118.46 for Faster R-CNN. Peak GPU memory was 8.26 GB on PetFace and 7.94 GB on FIRC, while reported epoch times were 4.12 and 3.28 minutes, respectively.
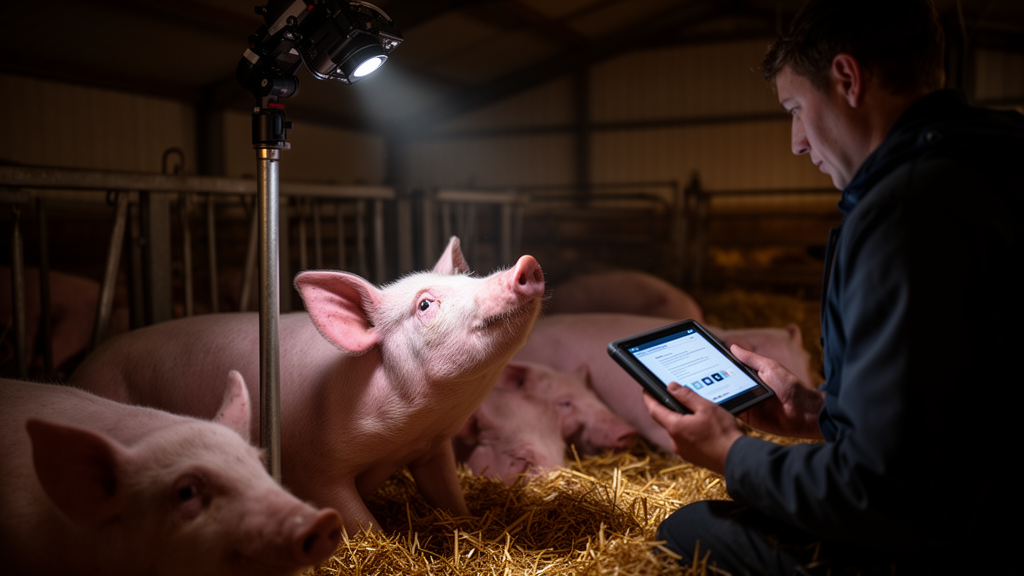
Evaluation in large-scale pig-farm settings covered nursery, fattening and breeding houses. Each scene type included 10 breeding stalls, with pig images collected over 30 consecutive days under varying lighting, postures and stocking densities. I-YOLOv8-MCGIRNet was reported to detect one pig face in 2.8 milliseconds. Its small-target detection rate in dense scenes was 94.1%, compared with 86.3% for I-YOLOv8-IRNet. When 30% of local facial features were partially missing, its recognition accuracy was 82.7%, versus 79.6% for I-YOLOv8-Swin Transformer and 61.8% for Faster R-CNN.
Counting performance was measured in sparse, dense and overlapping scenarios. For I-YOLOv8-MCGIRNet, counting accuracy rose from 88.6% to 98.5% in sparse scenes, from 79.9% to 94.7% in dense scenes and from approximately 71.8% to 92.2% in overlapping scenes. In the overlapping condition, Faster R-CNN rose from about 52.1% to 64.9%. These results apply to the sampled farm environments and test conditions used in the study rather than establishing performance across every type of pig facility.
Recognition was also assessed with pigs standing, lying down and turning their heads 45 degrees left or right. The study reported that I-YOLOv8-MCGIRNet achieved the best detection and recognition accuracies among the compared models for all three postures, with both measures remaining above 0.91 in the non-standard postures. In the head-turning condition, its detection and recognition accuracies were 0.938 and 0.919. Relative to I-YOLOv8-IRNet, the reported improvements were 7.0 and 9.4 percentage points, respectively.
The evidence supports the model’s measured performance within the selected datasets and farm scenarios, but its generalizability remains untested. The authors trained, validated and tested within PetFace and FIRC separately and did not perform direct cross-dataset transfer validation. The study also did not fully evaluate outdoor conditions in extreme weather or optimize the system specifically for facial differences among pig breeds and ages. The results therefore indicate benchmark and scenario-specific performance for pig-face recognition and counting, rather than demonstrated effectiveness in unstudied farms, species, breeds or environmental conditions.
Subject of Research: Experimental development and benchmarking of a pig-face recognition and counting model
Article Title: Intelligent recognition and counting of pig faces based on improved YOLOv8 and MCGIRNet
Article References: Kang, J., Wang, H., Chen, C., & Liu, Q. (2026). Intelligent recognition and counting of pig faces based on improved YOLOv8 and MCGIRNet. Discover Artificial Intelligence, 6(1), Article 1467. https://doi.org/10.1007/s44163-026-02349-y
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02349-y
Keywords: pig-face recognition, pig counting, YOLOv8, MCGIRNet, computer vision, object detection, precision livestock, smart farming, machine learning, Intelligent, recognition, counting
News Source: Blake Davidson. (October 20, 2026). Improved YOLOv8 model outperforms comparators in benchmarked pig-face recognition and counting. Scienmag.