A federated learning system paired with a Decision Transformer selected the lowest-cost feasible task assignments more accurately than conventional and federated baselines in a simulated industrial scheduling environment. The study, led by Mengmeng Su and Man Hu, combined distributed model training with long-range sequence modeling across five sources of operational data. On a fixed test set, the combined architecture reached 92.5% scheduling accuracy, outperforming a centralized long short-term memory baseline by 12.7 percentage points. Its average end-to-end scheduling cycle took 3.1 minutes, while single-step inference remained below 200 milliseconds. These results describe performance in simulation rather than deployment in a working factory, and the privacy evaluation used an intentionally limited threat model.
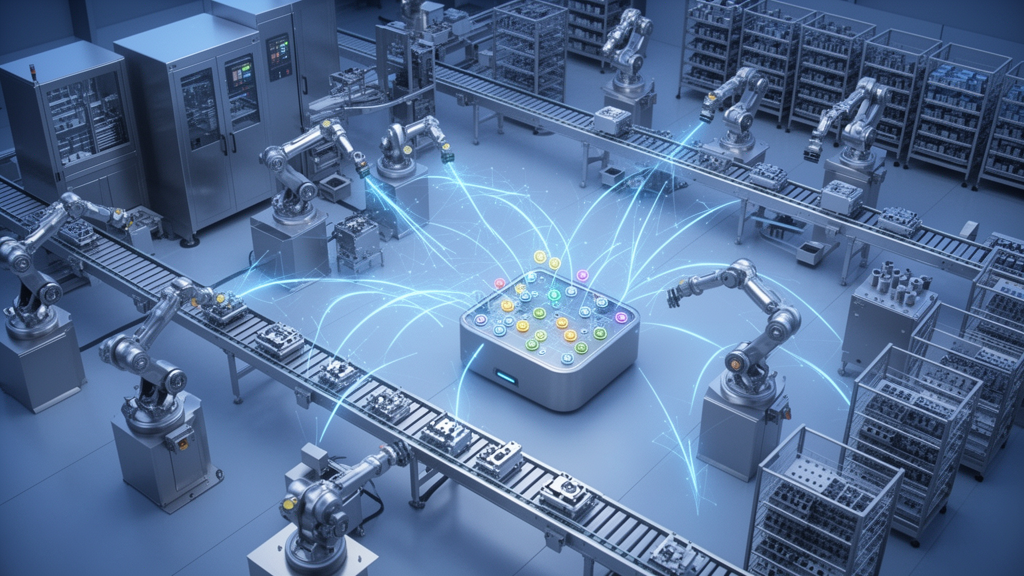
The central problem was how to combine rapidly changing, heterogeneous information without pooling every organization’s raw records in one place. Industrial dashboards may need machine telemetry, historical orders, environmental conditions, network status and user demand, each sampled at a different rate and governed by different data owners. Central collection can create communication bottlenecks and increase exposure of sensitive operational information. In the tested architecture, 20 distributed clients each retained their data locally, trained a common convolutional encoder and Decision Transformer, and sent only model-parameter updates to a coordinating server. The server combined those updates with FedAvg and redistributed the global model during 50 communication rounds.
The simulated environment contained 100,000 aligned temporal samples drawn from five heterogeneous sources: 35,000 device-sensor records sampled at 1 hertz, 28,000 historical scheduling records, 12,000 environmental records sampled every five minutes, 15,000 network-status records sampled every 10 seconds and 10,000 user-demand records. After cleaning and temporal alignment, the five sources were placed on a common one-second grid. Sensor outliers were removed using the three-sigma rule, missing time-series values were interpolated, structured numerical gaps were filled with training-set means, numerical variables were normalized, and categorical variables were one-hot encoded. The same preprocessing parameters fitted on the training partition were then applied to validation and test data.
A three-layer convolutional neural network converted each local feature tensor into a 128-dimensional state representation containing device status, task-queue information and environmental measurements. The Decision Transformer then received sequences of return-to-go, state, action and time-step tokens. Its 16-step context allowed self-attention to connect the current task condition with earlier decisions, while each 20-dimensional action assigned a task to one of 20 numbered devices. The return-to-go was defined as the inverse of future cumulative scheduling cost, so maximizing the model’s target return was equivalent to minimizing that cost. Training targets came from the simulator, which selected the feasible assignment with the lowest cumulative cost under the conditions at each scheduling instant.
Accuracy meant the proportion of evaluated decisions in which the model selected the simulator’s reference minimum-cost feasible action, rather than merely producing a generally plausible assignment. The researchers evaluated the resulting system against XGBoost, LightGBM, TabNet, an FT Transformer, federated recurrent and Decision Transformer variants, and offline reinforcement-learning methods including conservative Q-learning and implicit Q-learning. The 100,000 samples were divided chronologically into 70% training, 15% validation and 15% test partitions. Five-fold blocked cross-validation was performed within the training portion while preserving temporal order, the validation partition supported early stopping, and the fixed test partition was evaluated after hyperparameter selection. Results came from five independent runs differing in model initialization and client sampling and were reported as mean plus or minus standard deviation.
Beyond the headline accuracy result, the ablation comparisons suggested that both halves of the architecture contributed. Centralized Decision Transformer achieved 87.8% accuracy, compared with 92.5% for the federated version, while FedAvg-LSTM reached 85.6%. The authors therefore associated 4.7 percentage points with federated cross-client aggregation and 6.9 percentage points with Decision Transformer-based trajectory modeling relative to conventional recurrent modeling. Other federated Decision Transformer baselines were also lower: FedProx-DT reached 89.4%, SCAFFOLD-DT 90.1% and FedNova-DT 89.7%. Offline decision baselines reached 84.9% for conservative Q-learning and 86.5% for implicit Q-learning, under the same chronological splits, client partition, action definitions, reward function and scheduling constraints.
The architecture also reduced data movement between clients and the server. Cumulative parameter transmission was 63% lower than that of a FedAvg-GRU baseline under the same client-participation schedule and number of communication rounds. Privacy was assessed through membership inference, attribute inference and model inversion attacks by participants assumed to follow the federated protocol but attempt to infer protected information from shared updates. Across five independent runs, the mean empirical attack-success rate was below 0.05%. The study did not apply a formal differential-privacy budget, report attack-specific confidence intervals, or test malicious clients capable of poisoning updates, so the result does not establish protection against every form of malicious federated participant.
Operational performance depended on the measure being reported. The system handled more than 2,000 real-time data streams per second, with average CPU utilization of 51.6% and peak memory use of 8.9 GB. Only 2.1% of tasks exceeded their time limits, a 10.6% decrease compared with the traditional model. The end-to-end cycle averaged 3.1 minutes, 5.1 minutes shorter than the centralized model and 2.5 minutes shorter than single federated learning; the longest reported cycle was 9.4 minutes. The sub-200-millisecond figure applies only to generating one action from an aligned state, not to collecting inputs, parsing outputs, allocating resources and finalizing a complete plan.
The researchers also created five progressively larger Decision Transformer configurations, from a 48-dimensional lightweight model to a 128-dimensional version with additional depth in its final temporal stage. Analytical parameter estimates placed these models at approximately 8.2%, 11.2%, 22.8%, 32.8% and 77.8% of the dominant parameter budget of a standard six-block 128-dimensional reference. The purpose was to offer a capacity–efficiency trade-off for workloads ranging from simple single-task scheduling to burst-heavy parallel operations. SHAP explanations, generated after inference, identified device load rate, task priority and historical scheduling success rate as the largest contributors in the reported analysis. Those explanations were diagnostic outputs and did not influence model training or action selection.
Several limitations prevent the simulation results from establishing factory performance. The datasets were generated and partitioned within a constructed scheduling environment, and the five independent evaluation runs varied model initialization and client sampling. The system was tested with non-independent client data, including missing modalities represented by zero-valued channels and availability masks, but the authors note that performance could deteriorate under extreme heterogeneity. It also lacked online incremental learning because the reported training was offline. The evidence supports the combined architecture as a promising option for privacy-conscious, real-time scheduling experiments, while future work would need to test live operations, malicious poisoning, formal privacy accounting and online federated updates.
Subject of Research: A simulated federated Decision Transformer system for multi-source industrial scheduling.
Article Title: A federated learning and decision transformer-based multi-source data fusion architecture for real-time industrial scheduling dashboards
Article References: Su, M., & Hu, M. (2026). A federated learning and decision transformer-based multi-source data fusion architecture for real-time industrial scheduling dashboards. Discover Artificial Intelligence, 6(1), Article 1155. https://doi.org/10.1007/s44163-026-02164-5
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02164-5
Keywords: federated learning, Decision Transformer, industrial scheduling, multi-source data fusion, offline reinforcement learning, privacy-preserving AI, real-time inference, non-IID data, industrial simulation, model efficiency, federated, learning
News Source: Denise Maddox. (October 26, 2026). Federated decision transformer sharpens simulated industrial scheduling. Scienmag.