Personalized video recommendation platforms face severe computational and algorithmic hurdles when attempting to accurately anticipate viewer selections from massive catalogs of digital media. Modern online video services support billions of global consumers who generate complex streams of interaction logs, yet conventional recommendation architectures frequently depend upon identification-based features that fail to represent rich semantic context. In an evaluation conducted on an extensive real-world dataset from the streaming service Mango TV, a new deep learning framework integrating attentive multi-view feature learning with joint long-term and short-term interest modeling consistently outperformed twenty-three established baseline models across multiple ranking and classification metrics. By systematically combining heterogeneous semantic streams with structured collaborative signals and sequential behavioral tracking, the architecture demonstrates how coordinated multi-component networks can effectively capture the complex behavioral dynamics inherent to large-scale multimedia consumption.
The growth of global streaming media has accelerated the demand for sophisticated discovery tools capable of alleviating digital information overload. Market analyses indicate that global over-the-top video revenues surpassed three hundred and forty billion dollars in 2025, with projections estimating the total worldwide television and video sector reaching approximately seven hundred and twenty-eight billion dollars. In major regional markets such as China, online audiovisual users reached nearly 1.1 billion individuals by late 2025, with short-video consumers comprising 1.074 billion viewers and daily engagement averaging over two hundred minutes per user. To retain audience interest and optimize platform monetization, major industry providers rely heavily on automated ranking pipelines. However, traditional systems regularly struggle with the multimodal heterogeneity of video assets, the sparsity of user feedback, shifting consumer tastes over time, and algorithmic homogenization that limits the diversity and relevance of suggested content.
To overcome these systemic bottlenecks, the research team investigated a top-N ranking problem framed as a click-through rate estimation task, predicting the probability that a viewer engages with a candidate video given contextual signals, historical behaviors, and multifaceted item attributes. Standard industrial approaches often compress sparse categorical identifiers into dense embedding vectors for downstream processing through multilayer perceptrons, or deploy tree-based ensembles such as gradient boosting decision trees. While effective for simple tabular cross-features, pure identification-based designs ignore the descriptive textual and structural evidence embedded in titles, plot summaries, creative personnel, and social interaction graphs. Furthermore, existing sequential recommendation techniques frequently examine immediate interactions without preserving the temporal trajectory of user actions or fail to connect localized viewing sequences with durable, long-term personal preferences.
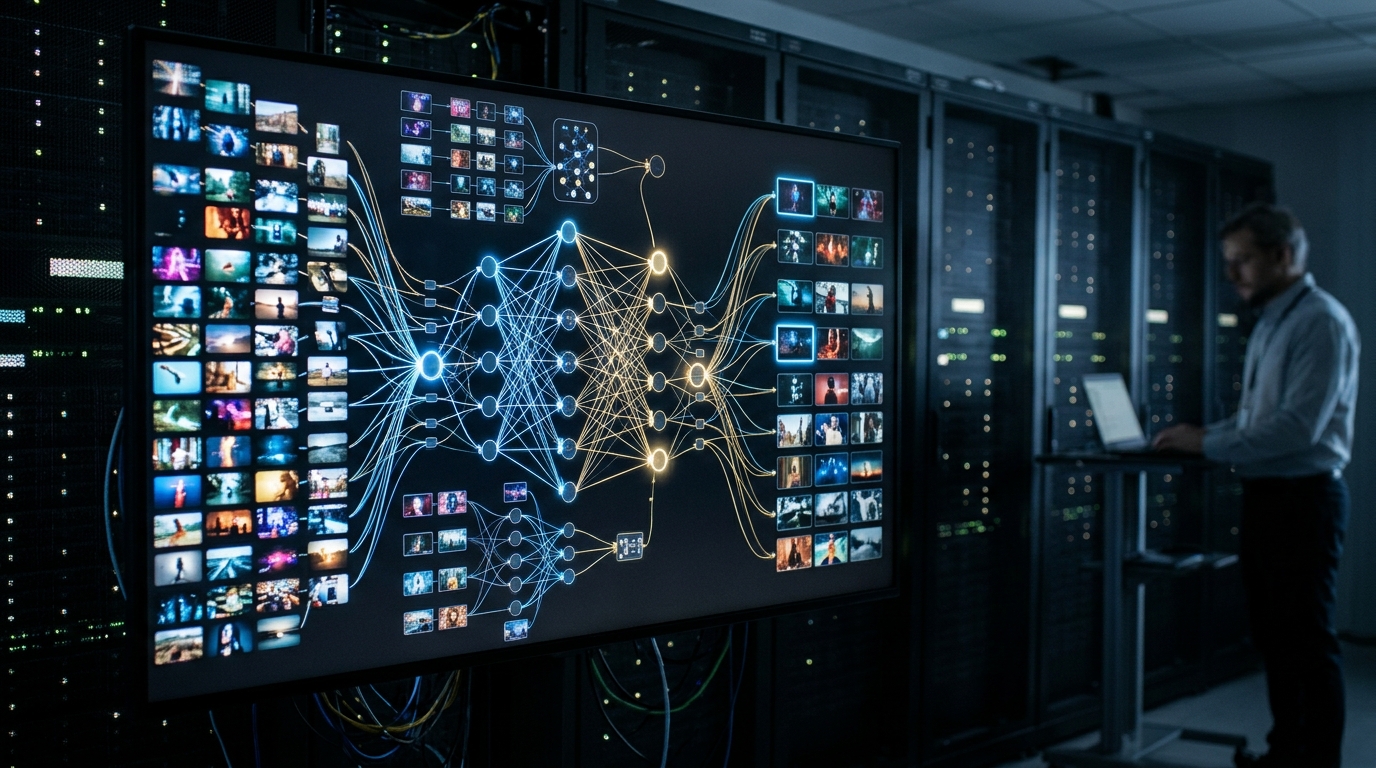
The newly formulated framework resolves these representational limits through four specialized modules that operate across orthogonal feature spaces: an Attentional Field-aware Factorization Machine, a hybrid LightGBM multilayer perceptron module, a DeepWalk network graph processor, and an attentive multi-view learning and long-term and short-term interest modeling pipeline designated as AMVL-LSIM. Rather than relying upon a single monolithic network, the architecture distributes feature extraction tasks across dedicated sub-networks designed specifically for sparse cross-interactions, dense numerical transformations, latent bipartite graph walks, and temporal sequence representations. The intermediate outputs generated by these four constituent blocks are subsequently concatenated into a unified vector representation and processed through a fully connected prediction layer optimized via cross-entropy loss with regularization constraints.
Within the AMVL-LSIM module, video representation relies on an attentive multi-view encoder that unifies four distinct descriptive perspectives: genre category, video title, narrative content description, and starring cast members. While conventional methods often concatenate multimodal inputs naively, this mechanism applies word-level embeddings trained via a continuous bag-of-words architecture, feeds textual tokens through bidirectional long short-term memory networks, and aggregates hidden states using multilayer perceptron attention layers. To blend these distinct informational streams into a cohesive vector, the system applies view-level attention weights that dynamically prioritize specific perspectives based on learned importance. This flexible weighting allows the encoder to emphasize cast familiarity, plot specifics, or broad genre categories dynamically, producing a discriminative item embedding that captures the semantic depth of each video catalog entry.
Concurrently, the user encoder captures behavioral evolution across two distinct temporal horizons by decoupling durable preference patterns from immediate viewing impulses. Long-term interests are modeled by combining a user’s global historical viewing behavior with collaborative signals propagated from similar neighbors. After converting historical viewing records into dense vectors via average pooling, the system identifies the top-N most similar users using cosine similarity and constructs an interaction graph. A multilayer graph neural network then applies neighborhood aggregation across these linked nodes, propagating higher-order structural information to refine the primary user’s representation and mitigate the pervasive sparsity of individual viewing logs. By absorbing structural patterns from behavioral neighbors, the framework preserves broad, enduring tastes that persist across extended periods of platform interaction.
Short-term interest modeling addresses localized shifts in viewing focus by analyzing the sequence of a user’s most recent interactions. This subsystem combines an attention-over-content mechanism with an attention-enhanced bidirectional long short-term memory network to evaluate the specific ordering and relevance of recently watched items relative to candidate videos. The bidirectional recurrent network processes sequential viewing transitions to extract subtle directional trends, while dedicated multilayer perceptron layers calculate importance weights for each time-series state. By concatenating the content-aware current interest embedding with the sequential temporal representation, the framework constructs a dynamic short-term vector that reflects immediate viewer inclinations. This design prevents transient browsing variations from obscuring foundational preferences while ensuring the recommendation feed adapts swiftly to recent topical engagement.
To complement the semantic and sequential representations derived from the AMVL-LSIM module, the remaining system branches process structural and tabular data through specialized computational pathways. The Attentional Field-aware Factorization Machine utilizes multi-head self-attention alongside field-aware factorization layers to evaluate high-order and second-order combinations among sparse categorical attributes, applying learned attention weights to assign distinct significance to diverse field pairings. Meanwhile, the LightGBM multilayer perceptron module ingests both raw numerical indicators and five categories of engineered dense features—including cross-statistics, top-N actor overlaps, and text similarity metrics—transforming decision tree leaf node indices into expressive non-linear representations. Additionally, the DeepWalk module extracts latent network topology by executing random walks over a user-video bipartite graph derived from platform push notifications, providing supplementary structural context to the final fully connected neural network.
Empirical validation was performed on an extensive desensitized dataset comprising six million training records and one million test samples gathered across seven consecutive days, reflecting over 218,000 distinct users and nearly 47,000 unique videos with a natural positive-to-negative sample ratio of 1:12. The experimental results established that the multi-component architecture achieved top-tier performance across all evaluated metrics, recording a Group Area Under the ROC Curve of 0.7731, an HR@5 of 0.6698, an MRR@5 of 0.3841, an NDCG@5 of 0.4897, an HR@10 of 0.7878, an MRR@10 of 0.4158, and an NDCG@10 of 0.5526, outperforming the strongest baseline across each respective measure.
Systematic ablation studies isolated the relative performance contributions of individual features, architectural modules, and semantic views, confirming that each designed component plays an essential operational role. Removing the complete AMVL-LSIM module produced the most dramatic performance decline, reducing the Group Area Under the ROC Curve from 0.7731 to 0.7513, while submodule ablations revealed that excluding short-term modeling lowered the metric to 0.7697 and excluding long-term modeling reduced it to 0.7714. Feature removals demonstrated that cross-statistical features exerted the largest influence among engineered tabular variables, whereas single-view evaluations showed that genre categories provided the strongest solitary predictive power, followed by cast members, narrative titles, and detailed descriptions. Combining all four semantic perspectives simultaneously delivered the highest overall accuracy, proving that multi-view integration captures complementary behavioral signals that single-view baselines overlook.
Hyperparameter investigations provided critical insight into optimization dynamics, identifying that peak predictive accuracy required balanced architectural depth and controlled capacity. Sensitivity analyses demonstrated that a learning rate of 0.001 paired with the rectified linear unit activation function yielded superior optimization stability compared to alternative nonlinear functions, which suffered from slower convergence or gradient vanishing. Furthermore, testing variations in network architecture revealed that the prediction multilayer perceptron performed optimally with exactly three hidden layers and 128 neurons per layer; expanding depth or neuron counts beyond these thresholds led to progressive performance degradation driven by parameter overfitting on the training distribution. These empirical boundaries underscore the importance of structural regularization when managing high-dimensional multimodal recommendation inputs.
Despite its demonstrated predictive gains, the authors observed that the model’s multi-branch architecture introduces considerable computational complexity during training and inference, which may create deployment constraints in real-time platforms where millisecond latency budgets are strictly enforced. The current investigation focused primarily on maximizing representation capacity and ranking accuracy rather than optimizing runtime resource consumption. By refining these multi-view collaborative foundations into computationally lean architectures, video streaming infrastructures can deploy nuanced, semantic-aware personalization at enterprise scale without compromising real-time response speeds.
Subject of Research: Personalized video recommendation using attentive multi-view learning and dual-horizon user interest modeling
Article Title: Personalized video recommendation with attentive multi-view learning and long-term and short-term interest modeling
Article References: Yuan, Y., Luo, L., Wang, K., & Dong, S. (2026). Personalized video recommendation with attentive multi-view learning and long-term and short-term interest modeling. Management System Engineering, 5(1), Article 19. https://doi.org/10.1007/s44176-026-00075-4
Image Credits: AI Generated
DOI: 10.1007/s44176-026-00075-4
Keywords: Personalized Video Recommendation, Multi-View Learning, Sequential Recommendation, Graph Neural Networks, Bidirectional LSTM, Factorization Machines, Deep Learning, Click-Through Rate Prediction, Attention Mechanism, User Interest Modeling, LightGBM, DeepWalk, Information Overload, Feature Interaction, Mango TV Dataset, Recommender Systems
News Source: Denise Maddox. (November 17, 2026). Attentive Multi-View Architecture Improves Click-Through Predictions in Video Recommendation Systems. Scienmag.