Machine-learning models that predict how mutations change binding strength are increasingly used to prioritize candidate designs in T-cell receptor engineering, but most benchmarks quietly assume one thing: that an experimentally solved structure of the complex is available. A new study published in Frontiers in Bioinformatics asks what happens when that assumption fails, and its answer is nuanced. Experimental structures remain the most reliable input, yet when only predicted structures exist, the choice of AlphaFold 3 scaffold and the choice of prediction model together determine whether the workflow succeeds or misleads.
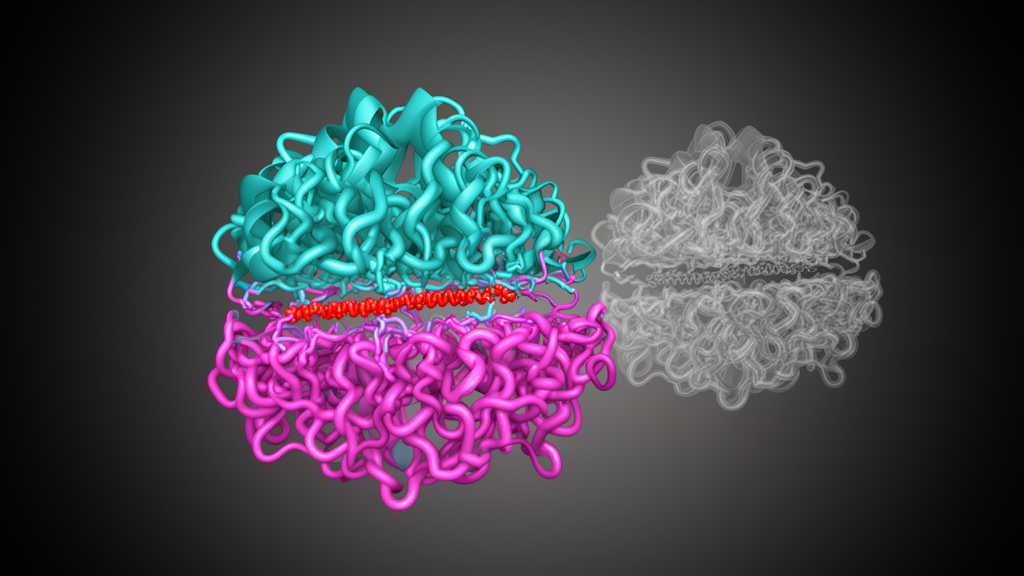
The research team, led by Zhongliang Guo, Kei Oyama and Rui Yamaguchi from Aichi Cancer Center Research Institute and Nagoya University, curated 438 mutation entries with experimentally measured changes in binding free energy, known as ΔΔG values, across 37 unique TCR–pMHC complexes from the ATLAS database. TCRs recognize antigenic peptides presented by major histocompatibility complex molecules through six complementarity-determining region, or CDR, loops. Negative ΔΔG values conventionally indicate improved binding relative to the wild type, while positive values indicate weakened binding, and structure-based deep-learning models such as RDE-PPI, Prompt-DDG, BA-DDG and H3-DDG use a template complex structure plus mutation information to predict these values.
Before testing the predictors, the researchers quantified how much TCR structure actually changes when it binds pMHC. Across 30 matched bound and unbound TCR pairs from the TCRFlexDock benchmark, framework regions showed low C-alpha RMSD of 0.86 plus or minus 0.24 angstroms, confirming that the immunoglobulin scaffold is largely conserved. The combined CDR regions, by contrast, showed substantially higher RMSD of 1.77 plus or minus 0.56 angstroms, with the CDR3 loops showing the largest displacements at 2.22 plus or minus 1.23 angstroms and 1.69 plus or minus 0.74 angstroms for the two chains. Atom-level analysis reinforced the pattern: side-chain RMSD rose from 1.48 angstroms in the framework to 2.73 angstroms across all CDRs, and reached 3.13 angstroms for TCR residues contacting pMHC within 5 angstroms. Binding, in other words, is associated mainly with local remodeling of the antigen-recognition loops rather than global rearrangement.
The team then evaluated how accurately AlphaFold Server predicts these complexes by comparing its top-ranked prediction for each of the 30 complexes with the corresponding experimental bound structure. AlphaFold 3 reproduced the TCR framework with a mean C-alpha RMSD of 0.78 angstroms, comparable to the experimentally observed bound–unbound framework difference, and predicted CDR conformations were closer to the experimental bound structures than the unbound ones were. Combined CDR RMSD averaged 0.86 angstroms for AlphaFold predictions versus 1.77 angstroms for bound–unbound pairs, and the advantage was most pronounced for the CDR3 loops. However, prediction quality was not uniform: whole-complex RMSD, which reflects the placement of pMHC relative to the TCR, ranged from 0.73 to 4.46 angstroms, with several outliers showing substantial deviations in docking geometry despite accurate local modeling.
With the structural groundwork laid, the researchers benchmarked the four structure-based predictors across five structural-input regimes: experimental PDB structures, single AlphaFold-predicted wild-type structures, ensembles of wild-type predictions, single mutant-specific predictions, and mutant ensembles scored by a reverse-mutation procedure they call inversion–negation. A sequence-only predictor, PPAC, served as a baseline receiving no structural input. Experimental wild-type PDB structures provided the best regime for all four models, with RDE-PPI reaching a Pearson correlation of 0.840 and Prompt-DDG 0.808 on the 438-variant cohort. Within this regime, RDE-PPI gave the best correlation and root-mean-square error, while Prompt-DDG gave the lowest mean absolute error.
Replacing experimental structures with AlphaFold-predicted wild-type scaffolds affected the models unevenly. Prompt-DDG was the most robust, its correlation falling only modestly to 0.796, with RDE-PPI close behind at 0.786. The authors attribute this tolerance to architecture: Prompt-DDG encodes mutation-centered microenvironments through hierarchical prompts, making it less sensitive to small global scaffold differences, while RDE-PPI models side-chain flexibility through estimated rotamer distributions and entropy, reducing dependence on any single predicted conformation. BA-DDG and H3-DDG, both inverse-folding models that rely on accurate backbone geometry, suffered larger losses, dropping to 0.658 and 0.551 respectively. Both partially recovered when mutant-specific AlphaFold scaffolds were used with reverse scoring and sign inversion, rising to 0.669 and 0.729, though the authors stress that this regime reflects the combined AlphaFold-plus-predictor workflow rather than the predictor alone.
Ensemble aggregation, a strategy some might have hoped would rescue predicted-structure inputs, delivered only modest and model-dependent gains. On mutant scaffolds, arithmetic-mean aggregation raised the correlation from 0.734 to 0.746 for RDE-PPI and from 0.756 to 0.760 for Prompt-DDG, while for BA-DDG on wild-type scaffolds it actually decreased the correlation from 0.658 to 0.637. Mean and median aggregation gave similar results, and weighting samples by AlphaFold ranking scores did not consistently outperform uniform averaging. In a saturation analysis of 100 randomly selected mutations, increasing mutant-specific ensembles from 20 to 100 structures produced no consistent improvement in any metric. The authors caution that AlphaFold samples are stochastic, sequence-conditioned structural hypotheses, not weighted draws from a thermodynamic equilibrium, so the lack of improvement should not be read as evidence that conformational dynamics are unimportant.
The study also probed whether easily computed features of the predicted structures could flag when AlphaFold-based scoring goes wrong, and the answer was largely no. Across 24 prespecified associations between prediction-error changes and features such as contact disagreement, CDR3 RMSD, pTM and ipTM, all Benjamini–Hochberg-adjusted p-values were at least 0.676, meaning none provided a reliable failure indicator. High global confidence, the authors conclude, is not sufficient to guarantee robust downstream prediction. Mutation-local contact disagreement showed a suggestive relationship for BA-DDG and H3-DDG, and peptide substitutions produced the largest absolute-error increases for those two models, but these remain descriptive cautions rather than validated screening thresholds.
The most practically striking results came from the candidate-prioritization analysis, which asked whether stabilizing CDR variants land near the top of a template-specific ranking. Across four ATLAS templates with at least 20 eligible CDR variants each, experimental structures gave the highest mean top-10 recovery for RDE-PPI and Prompt-DDG, at 8.5 and 8.3 of the ten most-stabilizing variants recovered. When no experimental structure was available, AlphaFold-mutant scaffolds provided the highest mean top-10 recovery for all four predictors, recovering 7.3, 7.5, 7.3 and 7.3 candidates respectively, compared with 6.5, 7.3, 5.0 and 3.5 for the best wild-type AlphaFold settings. In the 1AO7 template example, BA-DDG and H3-DDG recovered none of the top ten candidates from wild-type AlphaFold scaffolds but recovered nine from mutant-specific scaffolds, illustrating how dramatically scaffold choice can swing outcomes.
The authors are careful about scope. The 438 variants are distributed unevenly across 37 templates, with 29 templates containing fewer than ten variants, and the four-template prioritization analysis offers preliminary guidance rather than established practice. Whether AlphaFold-mutant scaffolds reproduce true mutant conformations cannot be determined without paired experimental mutant structures, which were unavailable. Their recommendation is therefore conditional: use an experimental TCR–pMHC structure whenever one exists, and when it does not, consider the complete AlphaFold-mutant workflow for recovering top-ranked CDR candidates, validating the chosen workflow on the target system before it guides experiments.
Subject of Research: Benchmarking machine-learning binding-affinity predictors for TCR engineering using experimental and AlphaFold 3 predicted structures
Article Title: Mutational binding assessment for TCR engineering on experimental and AlphaFold 3 scaffolds
Article References: Guo, Z., Oyama, K., & Yamaguchi, R. (2026). Mutational binding assessment for TCR engineering on experimental and AlphaFold 3 scaffolds. Frontiers in Bioinformatics, 6, Article 1879274. https://doi.org/10.3389/fbinf.2026.1879274
Image Credits: AI Generated
DOI: 10.3389/fbinf.2026.1879274
Keywords: AlphaFold 3, T-cell receptor, pMHC, CDR engineering, binding affinity prediction, DeltaDeltaG, protein structure prediction, machine learning, immunotherapy, structural bioinformatics, ATLAS database, SKEMPI v2
News Source: Drew Townsend. (October 29, 2026). AlphaFold 3 Structures Can Guide T-Cell Receptor Engineering, With Caveats. Scienmag.