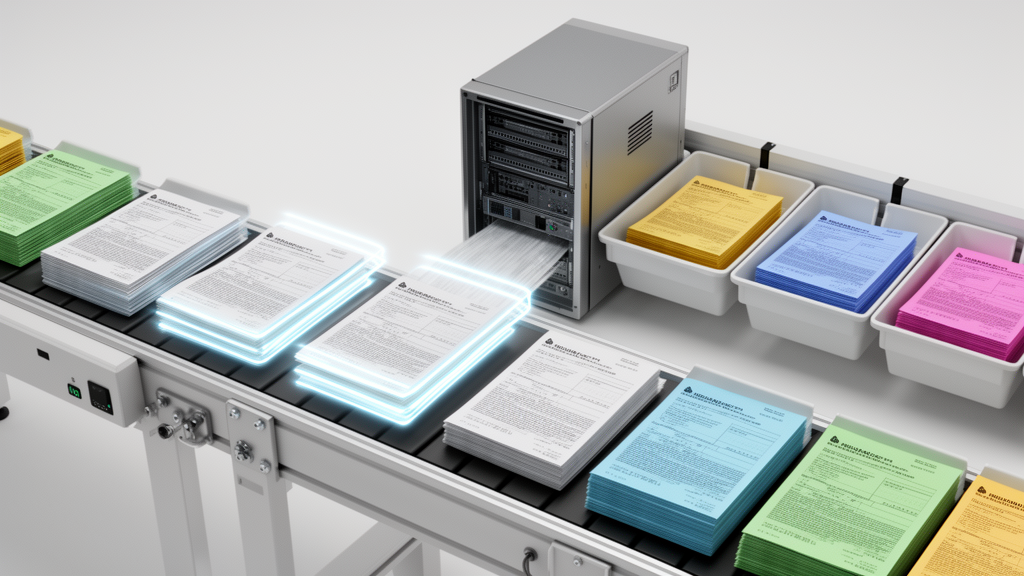
A research study reports that an artificial-intelligence pipeline can condense complex insurance policy documents and then sort them into seven predefined product categories. The system combines enhanced term-frequency inverse-document-frequency weighting, a bidirectional long short-term memory network optimized by a modified population-based search algorithm, and a LeNet-derived classifier with enhanced batch normalization. In experiments on a manually assembled collection of 134 policy documents, the combined framework achieved reported classification accuracy ranging from 0.935 with 60% of the data allocated for training to 0.985 with 90% for training, although the authors identify the small dataset as a major limitation.
The documents came from SBI Insurance, Star Health and Allied Insurance, Care Health Insurance, ICICI Prudential, Bajaj Allianz, The New India Assurance and LIC. They included policy documents, claim forms and supplementary materials, with coverage details, exclusions, claim procedures and regulatory guidelines. Personal identifiers such as names, policy numbers, addresses and signatures were removed. The text was structured or unstructured and generally contained 850 to 1,500 words, although some policies were longer. The seven target labels were Aarogya Sanjeevani, Accident Cover, Critical Illness Insurance, Disease-specific Insurance, Health Insurance, Hospital Cash Insurance and Top-Up Insurance.
Before summarization, each policy passed through tokenization, stemming, stopword removal and keyword identification. The researchers then combined three kinds of representation. Enhanced TF-IDF, or E-TF-IDF, adds dispersion and position-weight coefficients to the standard measure of term importance, giving greater weight to terms according to their distribution across classes and their location in a document. WordPiece tokenization supplied unigram, bigram and trigram features, while GloVe embeddings represented relationships among words, including synonymy and broader semantic associations. This feature set was intended to distinguish professional terms and contractual structures that ordinary frequency weighting might overlook.
The summarization stage used a bidirectional LSTM, which processes a sequence in forward and backward directions and can therefore represent context appearing before or after a token. Its weights were fine-tuned through the Modified Botox Optimization Algorithm, or M-BOA, a population-based optimizer inspired by the selection of facial muscles in the paper’s analogy for Botox injections. Candidate solutions encode Bi-LSTM weights and are evaluated with an objective that combines content coverage and redundancy reduction. Content coverage is based on the similarity of selected sentences to the original policy, while the redundancy term penalizes the simultaneous selection of similar sentences. The objective is minimized as a weighted sum of one minus coverage and redundancy.
M-BOA introduces an adaptive inertia weight to shift gradually from broad exploration of the search space toward more focused exploitation of promising solutions. During early iterations, the larger inertia value is intended to preserve population diversity and reduce the risk of premature convergence. Later, as the weight decreases, the search concentrates on regions associated with better objective values. In the paper’s convergence analysis, M-BOA reached a cost of 0.500 by the 100th iteration, lower than the corresponding values reported for the Lyrebird, Puffer Fish, Kookaburra, Red Panda and original Botox optimization algorithms. The authors also state that the adaptive strategy maintains computational complexity comparable to the original algorithm.
After summarization, the training text was expanded through synonym replacement, random insertion, word swapping and random deletion. The original dataset contained 134 samples, but augmentation increased it to 1,274 samples, with 182 samples in each of the seven classes. The paper reports that augmentation was restricted to the training data, leaving validation and test documents unaugmented, and that splits were maintained at the document level so that versions of a document could not appear in both training and test sets. It also reports five-fold cross-validation. These safeguards are important because augmentation can create near-duplicate versions of source material, potentially inflating performance if generated examples cross the train-test boundary.
For the classification task, the augmented summaries were processed by an aspect-term extractor that assigns a category to each token. These high-dimensional features were reshaped into a matrix and passed to Enhanced Batch Normalization-based LeNet, or EBN-LeNet. The architecture contains four convolutional layers, two average-pooling layers, dropout, a DS-WLP-BN layer, flattening and three fully connected layers. Its distinctive DS-WLP-BN component combines Lp pooling, a learned weight factor, double-sigmoid normalization and batch normalization. The authors say this combination is intended to stabilize training, reduce sensitivity to hyperparameter selection and address the gradient-vanishing problem associated with the relatively shallow original LeNet architecture.
In the reported comparisons, EBN-LeNet generally performed better than Bi-LSTM, SqueezeNet, LeNet, EfficientNet, MobileNet, CNN-FFNN, CNN-LSTM, Vision Transformer with SVM, GO-FC-CNN, BERT and DistilBERT. With 80% of the data used for training, its F-measure was 0.848, compared with 0.726 for Bi-LSTM, 0.642 for SqueezeNet, 0.795 for LeNet, 0.776 for EfficientNet, 0.616 for MobileNet, 0.678 for CNN-FFNN, 0.713 for CNN-LSTM, 0.778 for Vision Transformer with SVM and 0.784 for GO-FC-CNN. Across five folds, the proposed model’s accuracies were 0.956, 0.955, 0.961, 0.960 and 0.961, yielding a reported mean of 0.960 ± 0.002. T-test, Wilcoxon signed-rank and Friedman analyses all produced p-values below 0.05 for the reported comparisons.
An ablation study attributed the full framework’s reported performance to the combination of enhanced feature extraction, M-BOA optimization and improved normalization. The complete configuration reached an accuracy of 0.965, while the paper reports that variants using conventional LeNet, conventional TF-IDF or no optimization performed less well. In human evaluation, summaries were rated for coherence, consistency, fluency and relevance; ROUGE-1 and ROUGE-2 indicated substantial lexical overlap, ROUGE-L reflected sequence alignment, and BERTScore values of approximately 0.45 to 0.49 suggested semantic similarity beyond word matching, although relevance was lower than the other evaluated qualities. These observations are encouraging but remain tied to the small, curated test collection.
Computational measurements also showed that specialized networks were relatively efficient. LeNet required 130.34 seconds, while EBN-LeNet required 136.63 seconds, compared with 155.37 seconds for Bi-LSTM, 160.79 seconds for CNN-LSTM, 212.25 seconds for BERT, 230.90 seconds for MobileNet and 235.32 seconds for EfficientNet; GO-FC-CNN was slowest at 244.263 seconds. The authors propose that a deployed system could help customer-service staff locate clauses, support document triage, and contribute to automated policy recommendation or compliance workflows. They do not report a live insurer deployment, and they caution that larger and more diverse datasets are needed to determine whether the results scale beyond the 134 original documents.
Subject of Research: Experimental machine-learning pipeline for summarizing and classifying insurance policies
Article Title: Bi-LSTM & LeNet model for insurance policy summarization and classification
Article References: Kolambe, S., & Kaur, P. (2026). Bi-LSTM & LeNet model for insurance policy summarization and classification. Discover Artificial Intelligence, 6(1), Article 1057. https://doi.org/10.1007/s44163-026-02139-6
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02139-6
Keywords: insurance policy summarization, document classification, bidirectional LSTM, LeNet, enhanced TF-IDF, batch normalization, text augmentation, insurance artificial intelligence, Bi-LSTM, model, insurance, policy
News Source: Blake Davidson. (October 26, 2026). AI pipeline summarizes and classifies insurance policies. Scienmag.