Image clustering systems have long stumbled on a deceptively simple problem: pictures that look alike are not always the same thing. A beach and a desert both glow with golden tones, yet they belong to entirely different categories. A new study published in Data Science and Engineering on 2 November 2026 tackles this visual-semantic gap with a framework called Semantic-assisted Hierarchical Clustering with Context-Enhanced Prompting based on Reliable examples, or SHCC, which lets vision-language models and large language models build their own structured label space and then argue their way through the images that confuse them.
The research team, led by Hanning Yuan, Qi Guo, Ziqiang Yuan and Sijie Ruan, identifies three chronic weaknesses in existing semantic-assisted clustering. First, the label spaces these methods produce are flat, so labels sitting at wildly different abstraction levels, such as “fruit” and “apple”, can end up as peers in the same clustering solution. Second, most pipelines assume that a generated text description faithfully matches what the image actually shows; when the two diverge, the mismatch is silently absorbed into noisy pseudo-labels. Third, the final assignment step typically offers no reasoning trail, leaving users unable to see why a particular photograph landed in a particular cluster.
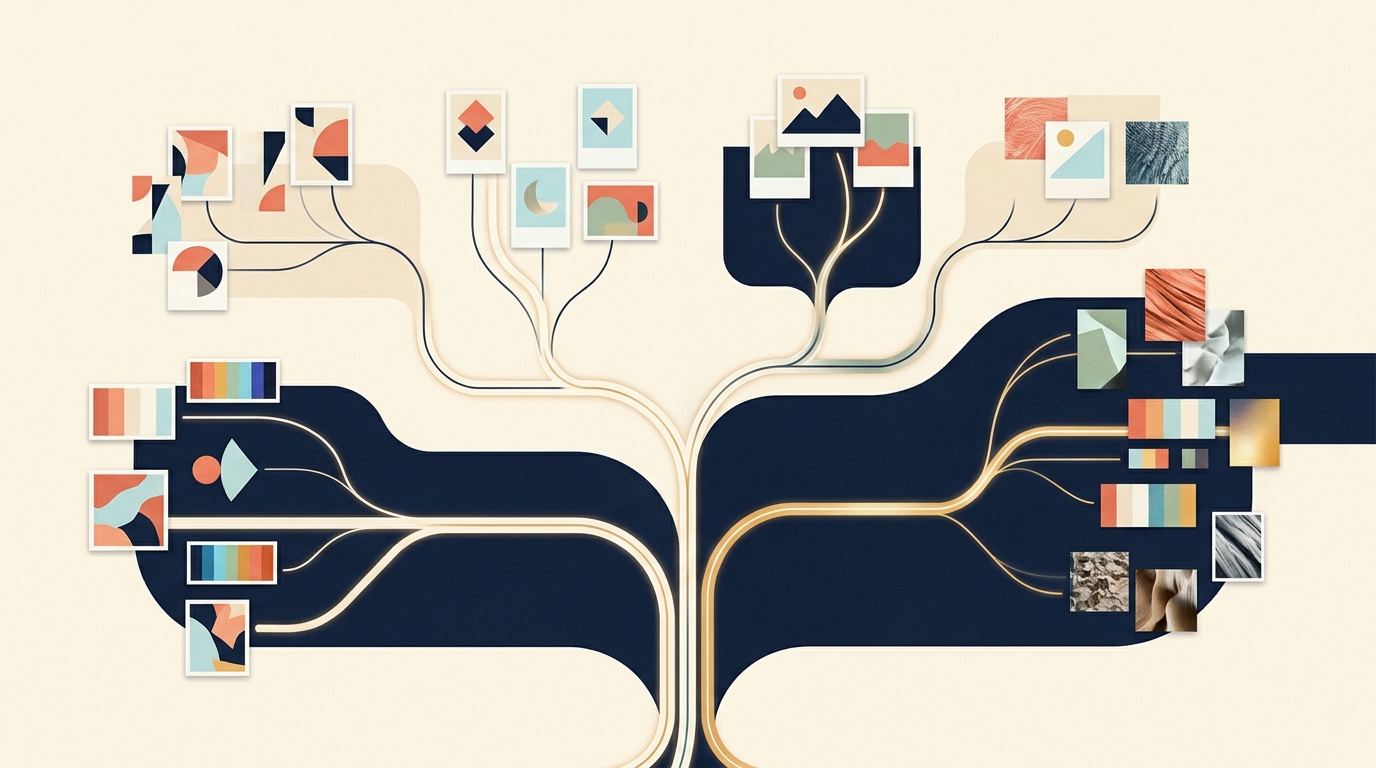
SHCC’s answer to the granularity problem is architectural. Instead of clustering image features directly, the framework first asks a vision-language model to describe each example five independent times, then uses a large language model to extract a single candidate label from every description. Examples whose extracted labels are inconsistent are filtered out of the label-space construction stage using a semantic clarity threshold of 0.8, though they are not discarded and still receive cluster assignments later. The remaining example-level labels are then clustered themselves: the system computes semantic similarity between labels by embedding LLM-generated dictionary-style definitions with the BGE-M3 embedding model and runs agglomerative hierarchical clustering over the weighted label space, producing a semantic label tree.
Cutting that tree at the level containing exactly the target number of clusters yields a set of labels at uniform granularity by design. In the paper’s worked example, two nodes containing “Siberian Tiger” and “Leopard” on one branch and “Lorry” and “Truck” on another are consolidated by an LLM into the clean, non-overlapping label pair “Felidae” and “Vehicle”. Because the hierarchy is built entirely in the label space, the authors argue, the resulting cluster labels avoid the hierarchical inclusion artifacts that plague flat label sets, and the LLM’s reasoning burden is reduced from one global labeling problem to many small, structured subproblems.
The second half of the framework addresses the images that resist classification. The system runs five independent inference rounds over the final label space with a vision-language model, and any example that receives the same label in every round is declared reliable. Examples that yield conflicting labels across rounds are flagged as ambiguous and routed to a semantic arbitration mechanism. For each ambiguous case, the system retrieves representative reliable examples from each candidate cluster, selected with a Maximal Marginal Relevance algorithm that balances similarity to the cluster centroid against redundancy among the chosen examples, and weaves their discriminative descriptions into a context-enhanced prompt.
The prompt is explicit about its format: the model must analyze the image, consult the reference examples, and output a verdict in the form “Based on [observed features], this image belongs to [category]”. Seven rounds of such context-enhanced inference are run per ambiguous example, and the final label is chosen by majority vote. The authors report that this mechanism both mitigates the randomness of single-pass inference and produces a transparent, traceable decision path, since the evidence that swayed the assignment is visible in the prompt itself. Case studies on STL-10 show the mechanism correcting errors in three scenarios, including cases where taxonomic anchors resolve feline-deer confusion and where functional-attribute references override misleading appearance under occlusion.
The experimental results are striking. Evaluated on four public benchmarks, STL10, CIFAR10, CIFAR100-20 and ImageNet10, using the standard clustering metrics of normalized mutual information, clustering accuracy and adjusted rand index, SHCC achieves state-of-the-art performance among fully automated unsupervised methods across all four datasets. On CIFAR10 it surpasses the second-best method by 3.3 NMI, 2.2 ACC and 4.0 ARI. On the harder CIFAR100-20, which contains twenty superclasses each aggregating five fine-grained subclasses, it outperforms the strongest knowledge-guided baseline, GradNorm, by 4.2 NMI and 1.9 ACC.
Perhaps most notably, on CIFAR100-20 SHCC reaches a clustering accuracy of 62.5, exceeding the user-intent-driven method ICTC’s 58.4 even though ICTC relies on carefully handcrafted prompts and iterative refinement. The authors attribute this to the construction of the semantic space itself: intent-driven methods depend on users being able to articulate precise clustering goals, which becomes difficult when category boundaries are blurred, whereas SHCC’s example-based hierarchy requires no fixed templates or external knowledge bases. Against LLM-based clustering methods adapted to the image domain, the gains are larger still, with improvements of 14.1 NMI over ClusterLLM on STL10 and 20.8 NMI on CIFAR10.
Ablation experiments on CIFAR100-20, averaged over five independent runs, quantify each component’s contribution. Removing the filtering of non-explicit semantic examples drops accuracy by 1.6 points and raises the standard deviation sixfold, indicating that noisy examples destabilize the context pool. Removing hierarchical clustering causes the largest damage, a 4.4-point accuracy drop and a 6.8-point ARI drop, with variance increasing more than tenfold. Removing context enhancement also costs 1.6 accuracy points. Hyperparameter analysis shows performance saturating at five initial inference rounds and seven arbitration rounds, which the authors adopt as defaults. The framework operates entirely through API calls to cloud-hosted models, requiring no local GPU resources, with total processing times ranging from roughly 686 seconds for ImageNet-10 to about 9,450 seconds for STL-10.
The study also probes which kinds of contextual help actually work. A baseline with no context performs well on coarse-grained datasets but struggles on CIFAR100-20, and, surprisingly, generic LLM-generated category descriptions sometimes underperform the no-context baseline, suggesting that verbose abstract cues can interfere with visual reasoning. SHCC’s example-grounded prompts instead deliver improvements of 2.7 NMI on CIFAR10 and 3.0 NMI on CIFAR100-20 over LLM-generated prompts, and the gains hold across DeepSeek-VL2, Qwen2.5-VL variants and Qwen-VL-Max, with Qwen2.5-VL-32B showing the largest improvement at 2.1 NMI and 2.3 ARI. The authors acknowledge limitations, including dependence on high-quality commercial models and the latency cost of multi-round inference, and point toward lightweight distillation and adaptive inference budgets as future directions.
Subject of Research: An unsupervised image clustering framework that constructs hierarchical semantic label spaces with large language models and resolves ambiguous assignments through context-enhanced prompting with reliable examples.
Article Title: Semantic-assisted Hierarchical Clustering with Context-Enhanced Prompting Based on Reliable Examples
Article References: Yuan, H., Guo, Q., Yuan, Z., & Ruan, S. (2026). Semantic-assisted Hierarchical Clustering with Context-Enhanced Prompting Based on Reliable Examples. Data Science and Engineering. https://doi.org/10.1007/s41019-026-00362-w
Image Credits: AI Generated
DOI: 10.1007/s41019-026-00362-w
Keywords: image clustering, semantic hierarchy, vision-language models, large language models, context-enhanced prompting, multi-round voting, CIFAR100-20, STL10, unsupervised learning, interpretable AI, SHCC, semantic arbitration
News Source: Denise Maddox. (November 4, 2026). AI Clustering Method Builds Semantic Label Trees to Sort Images It Cannot Name. Scienmag.