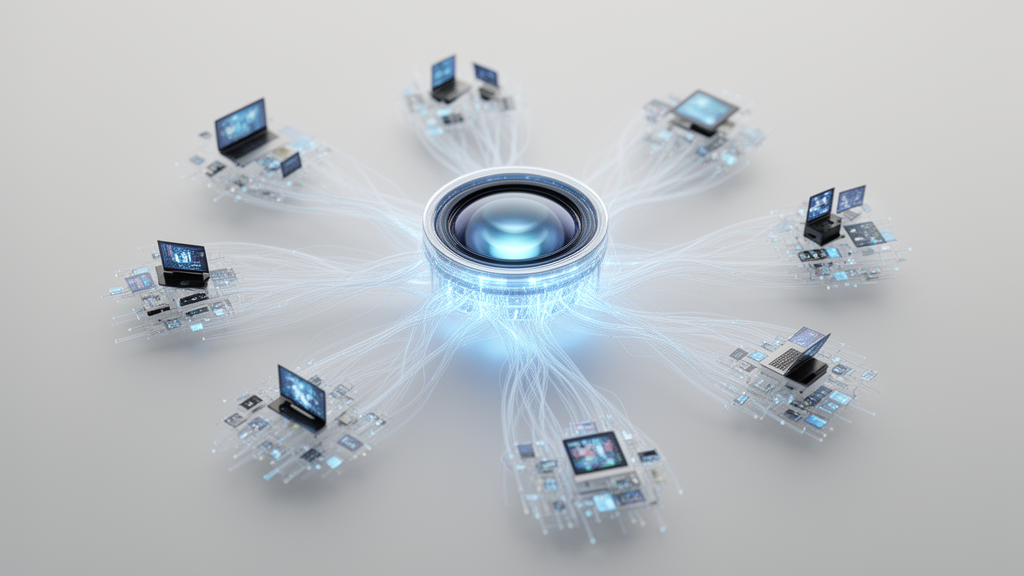
Researchers have introduced a novel framework called FAAM, or Federated Averaging with Attention Mechanism, designed to improve the efficiency and accuracy of privacy-preserving human activity recognition. Published in the journal Discover Computing, the study addresses a significant challenge in the field of Human Behavioral Context Recognition (HBCR): achieving high model performance while ensuring that user data remains private. Traditional centralized systems often require gathering large quantities of data in one location, which compromises user privacy. Federated Learning (FL) offers a decentralized alternative by training models directly on user devices, but its success relies heavily on effective client selection and aggregation strategies. FAAM aims to optimize these processes by leveraging attention mechanisms to prioritize the most relevant clients during each communication round.
The core innovation of FAAM lies in its use of an attention-based approach to identify and prioritize clients. In standard federated learning, all participating devices typically contribute equally to the global model, which can be inefficient if some devices provide noisy or less informative data. FAAM modifies this process by using an attention mechanism to evaluate local models based on accuracy and balanced accuracy metrics. By focusing on the most informative clients, the framework seeks to reduce communication overhead and accelerate convergence. This method allows the system to achieve equivalent or superior model accuracy with fewer clients and fewer communication rounds, making it a more efficient solution for real-time HBCR systems.
The study was conducted by a team of researchers including Atia Akram, Sadia Ismail, Syeda Rabail Zahra, Syed Qamrun Nisa, Naveed Islam, Sheikh Tahir Bakhsh, and Muhammad Amir Khan. Their work builds on the growing prominence of deep learning in human activity recognition, where traditional shallow learning techniques have been surpassed by more complex neural network architectures. The authors note that while federated learning has great promise for HAR, it still confronts challenges in natural situations, such as heterogeneity in user behavior and the communication costs associated with aggregating models from numerous devices. The main motivation for FAAM is to leverage the attention mechanism to prioritize users who contribute more valuable information, thereby reducing the server burden and improving the speed of model convergence.
To evaluate the proposed framework, the researchers utilized four publicly available datasets that feature significant variability in users, devices, and environments. These datasets include the IMU dataset, which contains data from seven individuals performing walking activities in two different buildings; the WISDM dataset, collected from 36 individuals via Android smartphone accelerometers; the UCI HAR dataset, recorded from 30 subjects using a waist-mounted Samsung Galaxy S II; and the ExtraSensory dataset, which contains data from 60 users in natural settings. The selection of these datasets was intended to provide a comprehensive testbed for assessing FAAM’s ability to handle different data volumes, complexity levels, and heterogeneity levels.
The experimental setup involved preprocessing the raw sensor data to eliminate noise, which is common in inertial sensor data. The data was partitioned into segments using a sliding window approach, and missing labels were imputed using the preceding instance to ensure consistency. The researchers employed a Deep Neural Network (DNN) with a 50-neuron hidden layer and ReLU activation for the model training. For the ExtraSensory dataset, specific feature engineering was applied, while raw data was used for the other datasets. The hyperparameters were set to a learning rate of 0.01 over 50 communication rounds, with batch sizes configured according to the specific dataset. The Adam optimizer was used for all network structures, and hierarchical clustering with two clusters was implemented for client organization.
The results demonstrated that FAAM achieves robust performance across the different datasets. On the WISDM dataset, FAAM achieved a peak accuracy of 97% with only 1 to 2 users, stabilizing within 5 to 8 rounds. As participation increased to 30 users, the accuracy gradually scaled to 81%, but the model demonstrated enhanced communication efficiency by converging faster in denser settings. On the IMU dataset, FAAM achieved 80% accuracy with 2 to 4 users, stabilizing in 9 rounds. When participation increased to 6 users, accuracy remained high at 79% with faster convergence in 6 rounds, though performance dipped slightly to 76% with 7 users. These findings indicate that while FAAM is scalable, increased user heterogeneity at higher participation levels can marginally impact peak performance.
On the UCI dataset, FAAM exhibited exceptional stability, consistently maintaining 80% accuracy across all user counts from 2 to 30. All configurations converged uniformly at round 5, suggesting that FAAM’s aggregation strategy effectively handles the data distribution in this context. This performance highlights the model’s robust convergence and indicates that user diversity has negligible impact on its effectiveness for this particular dataset. In contrast, the ExtraSensory dataset showed a flat performance trend, with FAAM consistently maintaining 76% accuracy across all user counts tested from 2 to 60. The round of stabilization was denoted as “-” for all rows, indicating that either FAAM converges very early or that performance is unaffected by communication rounds due to early saturation.
The comparison against state-of-the-art baselines further highlighted the practical resource-efficiency implications of FAAM. Table 2 and Table 4 in the study show that FAAM consistently approaches or trades a modest accuracy margin against the full-participation baseline while using a small fraction of the available client pool. On the UCI dataset, FAAM achieved competitive accuracy using as few as 2 of 30 available clients, which is only 6.7% of the pool. On the IMU dataset, it used 2 of 7 clients (28.6%), and on the ExtraSensory dataset, it used 2 of 60 clients (3.3%). This accuracy-for-participation trade-off is the central practical contribution of FAAM, offering substantially reduced client involvement and correspondingly reduced communication cost at a bounded, quantified accuracy cost relative to full participation.
The technical distinction of FAAM from prior attention-based federated learning methods is also significant. While previous methods like FedDA and Zhao et al. use attention exclusively for aggregation or require auxiliary information beyond the client’s own model parameters, FAAM applies a single self-attention formulation directly to the flattened parameter matrix. This design is architecture-agnostic and metadata-free, meaning it does not require additional client-side metadata or modifications when switching between different neural network backbones. The computational complexity of the attention mechanism in FAAM is O(C^2 D), which is linear in the number of model parameters and quadratic in the number of clients. Since typical cross-device FL rounds involve a small number of clients, this complexity is manageable and substantially cheaper than standard per-feature self-attention mechanisms.
Despite its promising results, the authors acknowledge several limitations of the current framework. FAAM selects clients based solely on model parameter informativeness and does not currently account for heterogeneous computing capabilities, communication delays, bandwidth constraints, or energy overheads that characterize real edge-network deployments. The reduction in communication and computation is a consequence of selective participation rather than an explicitly optimized resource-management objective. Furthermore, the current framework does not include an explicit mechanism to detect or mitigate Byzantine behavior or data-poisoning attacks. A malicious client could potentially forge parameters to yield an artificially high attention score, receiving disproportionate aggregation weight and potentially degrading the global model.
Privacy considerations are also discussed in the study. While FAAM avoids transmitting raw user data and instead shares only model parameters, providing a baseline level of data locality, this does not constitute a formal privacy guarantee. Prior work has shown that shared gradients or parameters can be exploited to reconstruct private training data through gradient inversion attacks. FAAM’s attention mechanism, which operates directly on clients’ flattened parameter matrices, introduces no additional protection against such attacks beyond what standard FedAvg-style parameter sharing already provides. Therefore, the term “privacy-preserving” in this context refers specifically to data locality, not resistance to inference or reconstruction attacks on shared updates.
The study concludes that attention-guided client selection and aggregation can improve the efficiency of federated HAR while maintaining competitive predictive performance. FAAM demonstrates that it is possible to achieve high accuracy with minimal client involvement, which is crucial for real-world deployments where resources are constrained. Future work will focus on jointly optimizing accuracy, communication and computational efficiency, energy consumption, robustness, and formal privacy protection. By integrating robustness mechanisms, differential privacy, and secure aggregation, the framework can be strengthened against malicious updates and privacy threats, enhancing its practical deployment in heterogeneous edge environments.
Subject of Research: Federated attention-driven client selection and aggregation for privacy-preserving human activity recognition
Article Title: Federated attention-driven client selection and aggregation for privacy-preserving human activity recognition
Article References: Akram, A., Ismail, S., Zahra, S. R., Nisa, S. Q., Islam, N., Bakhsh, S. T., & Khan, M. A. (2026). Federated attention-driven client selection and aggregation for privacy-preserving human activity recognition. Discover Computing, 29(1), Article 826. https://doi.org/10.1007/s10791-026-10781-y
Image Credits: AI Generated
DOI: 10.1007/s10791-026-10781-y
Keywords: Federated, attention-driven, client, selection, aggregation, privacy-preserving, human, activity, recognition, scientific research
News Source: Veronica Carney. (November 7, 2026). Attention Mechanism Boosts Federated Learning Efficiency for Activity Recognition. Scienmag.