Vision-Language AI Model Detects Bengali Fake News with Explainable Reasoning
Researchers report a multimodal framework combining Bengali OCR, hybrid visual encoders, and vision-language reasoning that achieved 97% accuracy on a ...
Researchers report a multimodal framework combining Bengali OCR, hybrid visual encoders, and vision-language reasoning that achieved 97% accuracy on a ...
A vision language model multiagent architecture let a TIAGo Pro robot complete five healthcare tasks in an unoccupied patient room, ...
A narrative review of studies published between January 2021 and September 2026 synthesizes multimodal deep learning approaches for breast cancer ...
Researchers report that tiny, temporally coordinated perturbations can gradually poison the latent memory of bird's-eye-view perception in autonomous vehicles, while ...
A new framework called TRRN re-indexes and filters web-retrieved images against few-shot class anchors, lifting accuracy across six benchmark settings ...
A new open access survey in Artificial Intelligence Review organises open-ended visual segmentation into three research directions and maps the ...
A new narrative review finds that medical vision–language AI models show strong benchmark results but suffer from inconsistent evaluation reporting, ...
A LLaMA-CLIP cross-attention system improved multimodal matching, intention recognition and personalization in benchmark tests while recording batch-size-one inference latency of ...
A new research collection spanning tactile arrays, sim-to-real tactile learning, LiDAR-camera calibration, structured visual reasoning and virtual social touch shows ...
Researchers have built a modular AI framework that improves automated chest X-ray report generation by retrieving similar past cases at ...
A new review maps how advances in computer vision, vision language models and reinforcement learning could enable collaborative robots to ...
Plant pathologists have long faced a stubborn diagnostic problem: a single leaf can carry several diseases at once, each with ...
A German study comparing vision and memory in conversational Pepper robots finds that seeing enhances perceived social presence, while remembering ...
A unified neural architecture now generates English image captions and translates them into five languages in a single end-to-end model, ...
University of Queensland researchers have created PlantMicro, a benchmarking dataset showing that vision language models perform at barely above random ...
Researchers have unveiled OATA, a test-time adaptation framework that lets traffic-sign image-text matching models recover from rain, fog, glare and ...
Researchers have developed KARAMEL, a knowledge-aware framework that fuses vision-language encoding with heterogeneous graph neural networks to link artworks to ...
A new 200,000-question benchmark from Carnegie Mellon University reveals that leading vision-language models perform at random chance when interpreting engineering ...
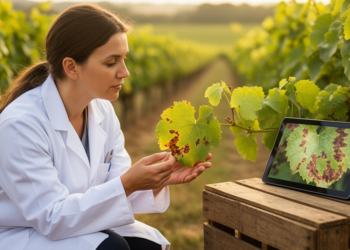
Researchers in Vietnam have built a hybrid vision-language AI that diagnoses grapevine diseases with 98.7 percent accuracy while explaining its ...
A fine-tuned three-billion-parameter vision-language model learned to halt all traffic at simulated intersections when pedestrians were in danger, cutting their ...