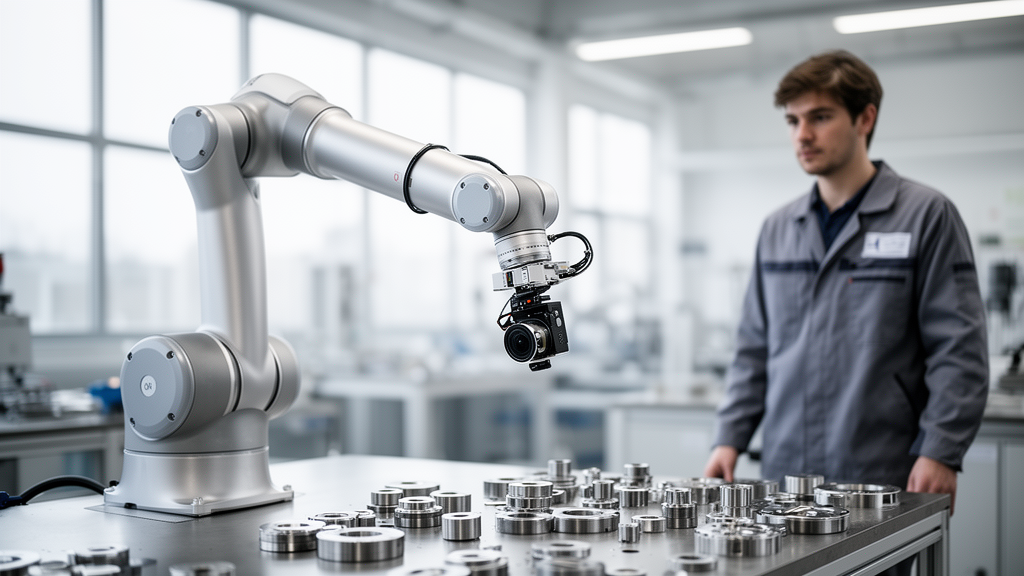
Collaborative robots, or cobots, are no longer the caged, pre-programmed manipulators that once dominated factory floors. According to a state-of-the-art review published in Artificial Intelligence Review by Mahmoud Salem, Markus Reischl, Veit Hagenmeyer, Katja Nau and Ahmed Elkaseer, researchers at Karlsruhe Institute of Technology and partner institutions in Egypt and Kuwait, these machines are evolving rapidly from isolated tools into genuine collaborative partners that operate productively alongside humans, other robots and machines. The accelerating pace of that transformation, the authors argue, is being driven above all by advances in computer vision, which now allow cobots to detect, recognise and assess both their environment and the actions unfolding within it, even in dynamic and cluttered settings.
The review, which carries the DOI 10.1007/s10462-026-11708-1 and was published on 17 October 2026, surveys the development of visual perception in cobots and examines a holistic perception pipeline in which raw vision signals, vision language models and augmented or virtual reality interfaces jointly power a unified sense-think-act loop. That architecture matters because the gap between laboratory demonstrations and industrial deployment remains wide. Most existing approaches, the authors note, assume uncluttered backgrounds with limited scene complexity, an assumption that collapses the moment a cobot is placed on a real production line filled with moving people, machines and materials. Achieving higher detection accuracy and real-time localisation in dynamic systems is therefore identified as a critical challenge for both research and industrial adoption.
The challenges facing cobots in high-mix, reconfigurable factories are formidable and specific. Fields of view are routinely occluded by other equipment or by the very workers the robot is meant to assist. Illumination fluctuates as parts move past light sources and shadows shift across workbenches. Backgrounds are ambiguous, filled with objects that look similar to the targets a robot must grasp. Many scenarios involve few-shot or zero-shot object recognition, where the robot encounters items it has never been trained on. High-speed motion blurs the visual signal, and fusing heterogeneous data streams from cameras, force sensors and other modalities in real time creates computational bottlenecks that can overwhelm onboard processing.
Beyond perception, cobots must also manipulate damaged or deformed items, a requirement that demands vision algorithms capable of inferring geometry from sparse cues and supporting adaptive grasping strategies. A dented component, a torn package or a misshapen workpiece presents a visual signature that differs from the clean, canonical shapes most training datasets contain. The review highlights that closing this gap between idealised and real-world visual inputs is essential if cobots are to handle the messiness of actual production environments rather than the controlled conditions of research laboratories.
To address these challenges, the review identifies three complementary research directions that together could unlock what the authors call plug-and-play cobots. The first concerns information aware sensor-fusion pipelines that transmit only credible voxels, the three-dimensional volumetric units that represent scene geometry, in order to reduce bandwidth while preserving sub-millimetre accuracy. Rather than streaming every data point from every sensor, such pipelines would filter and prioritise the most reliable volumetric information, cutting communication loads without sacrificing the precision required for delicate manipulation tasks.
The second research direction involves language conditioned planning and control networks that map plain-language goals to smooth, jerk-bounded trajectories. In practical terms, this means a worker could tell a cobot what to do in ordinary words, and the robot would translate that instruction into a physically executable motion plan that avoids sudden accelerations or abrupt stops. Jerk-bounded trajectories are crucial in shared workspaces because sudden changes in acceleration can be dangerous for nearby humans and can destabilise the objects a robot is carrying. Embedding language understanding directly into the planning layer represents a significant step toward intuitive human-robot collaboration.
The third direction involves pre-trained few-shot reward heads that score task progress without requiring bespoke metrics for each new application, thereby closing the reinforcement learning loop. Reinforcement learning typically depends on carefully engineered reward functions that tell an agent whether its actions are moving it toward a goal. Designing such functions for every new task is time-consuming and limits scalability. Pre-trained reward heads that can generalise across tasks would allow cobots to learn new skills from relatively few demonstrations, dramatically reducing the commissioning time that currently prevents rapid redeployment of robots across changing production lines.
Combined, these advances promise cobots that can be commissioned with relatively few demonstrations, a shift that would transform how factories adopt and reconfigure automation. The review situates itself within a broader context of robot learning, reinforcement learning, large language models and augmented or virtual reality interfaces, all of which are listed among its keywords and all of which contribute to the sense-think-act loop the authors describe. Vision language models, in particular, are highlighted as a bridge between raw visual signals and the semantic understanding needed to interpret scenes, follow instructions and anticipate actions in shared workspaces.
The work was carried out with financial support from the Karlsruhe Nano Micro Facility, a Helmholtz Research Infrastructure at Karlsruhe Institute of Technology, and under the Helmholtz Research Programme MSE at KIT, with open access funding enabled and organised by Projekt DEAL. The article is published under a Creative Commons Attribution 4.0 International License and is available as open access, allowing researchers and practitioners worldwide to examine the full survey. The authors report no conflict of interest, and the version shared early is citable and carries a permanent DOI, subject to further editorial refinement before the final Version of Record replaces it.
For a field in which the rate of change is accelerating rapidly, the review offers a structured map of where visual perception and predictive intelligence for cobots stand today and where they must go next. The sense-think-act loop it describes, powered jointly by raw vision, language models and immersive interfaces, provides a unifying framework for the diverse algorithms and architectures surveyed. The three research directions it identifies, spanning efficient sensor fusion, language conditioned control and generalisable reward modelling, are presented not as isolated fixes but as complementary advances that together could bring plug-and-play cobots from the pages of a review into the cluttered, dynamic, human-filled factories of the near future.
Subject of Research: A review of visual perception and predictive intelligence for collaborative robots identifies sensor fusion, language-conditioned control and few-shot reinforcement learning as keys to plug-and-play cobots.
Article Title: Seeing ahead through a state-of-the-art review of visual perception and predictive intelligence for collaborative robots
Article References: Salem, M., Reischl, M., Hagenmeyer, V., Nau, K., & Elkaseer, A. (2026). Seeing ahead through a state-of-the-art review of visual perception and predictive intelligence for collaborative robots. Artificial Intelligence Review. https://doi.org/10.1007/s10462-026-11708-1
Image Credits: AI Generated
DOI: 10.1007/s10462-026-11708-1
Keywords: collaborative robots, computer vision, vision language models, reinforcement learning, sensor fusion, robot learning, human-robot collaboration, Seeing, ahead, state-of-the-art, review, visual
News Source: Denise Maddox. (October 17, 2026). Cobots learn to see ahead: how vision and prediction could unlock plug-and-play factory robots. Scienmag.