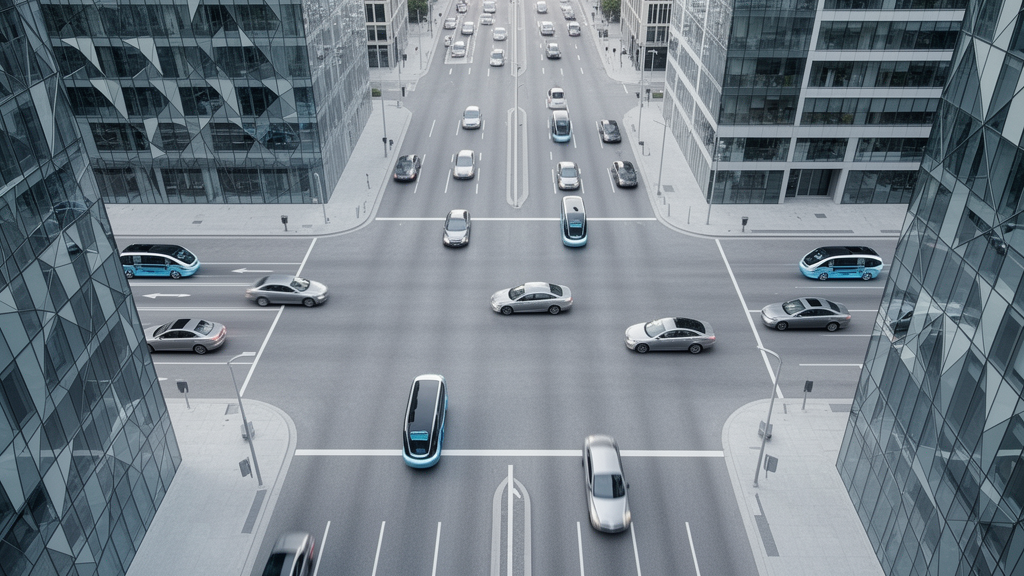
A decentralized multi-agent reinforcement learning architecture can successfully manage signal-free intersection traffic across variable fleet sizes and road layouts without relying on centralized reservation infrastructure, according to an extensive simulation study conducted in the SUMO traffic environment. Investigating the challenge of coordinating automated vehicles at complex urban conflict points, researchers reformulated Distributed Model-based Policy Optimization into a dynamic, padding-free framework where vehicles negotiate crossings through local observations and interaction graphs that update at each timestep. Rather than imposing a rigid agent capacity using zero-valued placeholder slots and tensor masks, the updated framework permits an open population where vehicles enter, traverse, and leave the road network dynamically. Evaluated across held-out Poisson traffic streams on single junctions and a twenty-five-junction grid, a single trained policy demonstrated zero-shot transfer across varying lane counts, demand volumes, and vehicle concurrency levels, delivering substantial throughput gains and dramatic delay reductions when compared to conventional fixed-time and detector-actuated traffic signals, albeit accompanied by a measurable residual collision rate under strict evaluation accounting.
Coordinating connected and autonomous vehicles without traditional traffic signals has long presented an attractive alternative to static infrastructure, promising notable improvements in travel time, fuel efficiency, and intersection capacity. However, conventional autonomous intersection management schemes predominantly rely on centralized admission schedulers and reservation tables that introduce single computational bottlenecks and require extensive wayside communication hardware. Conversely, previous attempts to apply multi-agent reinforcement learning directly to vehicle control have routinely inherited fixed-agent assumptions from their algorithmic formulations. In such setups, neural network input tensors and credit assignment dimensions are bound to a predetermined vehicle count established during training. When applied to real-world traffic where vehicle densities fluctuate continuously, fixed-capacity systems must either cap population sizes or rely on computational padding. This padding forces the neural networks to process placeholder agents, wasting processing resources on masking calculations and establishing an architectural capacity wall beyond which unrepresented vehicles cannot be accommodated without complete retraining.
To overcome these architectural constraints, the investigators eliminated fixed tensor allocations across every operational tier of the learning framework, creating an end-to-end pipeline driven by a single shared actor network. Operating within a decentralized partially observable Markov decision process, each automated vehicle functions as an individual agent executing continuous longitudinal acceleration commands bounded between minus eight and positive two point six meters per second squared at discrete intervals of zero point two seconds. Every agent construct relies on a compact, egocentric observation vector spanning two hundred and sixty-one dimensions. This vector captures the vehicle’s own kinematics, lifetime behavioral profile metrics, topological lane data, and the relative states of up to fifteen nearest neighbors located within a one-hundred-and-fifty-meter perception radius. To prevent queuing saturation from masking crossing cross-street threats, the observation pipeline integrates an explicit conflict block that directly computes curved geometrical conflict points, projected arrival times, and occupancy window gaps for up to four approaching cross-traffic vehicles using map data and vehicle-to-vehicle messages.
Underpinning the framework’s scalable learning dynamics is a dynamic interaction graph reconstructed after every simulation step over the exact live set of active vehicles. Graph edges are formed based on physical lane adjacency, follower relationships, and cross-road approaches within one hundred meters of an intersection, establishing a two-hop neighborhood structure for every active vehicle. Unlike conventional graph reinforcement learning methods that use graph neural networks as perceptual encoders to aggregate spatial states into policy inputs, this architecture strictly isolates the graph from the actor’s forward pass. Instead, the dynamic graph serves exclusively as a decentralized conduit during training to route learning credit and distribute cooperative reward signals. Advantage estimates derived from per-agent generalized advantage estimation are averaged over the two-hop neighborhood before updating the shared policy gradient, ensuring that proximal policy updates reflect localized cooperative outcomes while value functions regress returns using local critics without a centralized global coordinator.
The training regimen established for the primary controller utilized a four-lane, four-arm signal-free intersection subject to stochastic, cold-start Poisson arrivals scaled through an inflow curriculum that expanded from thirty to sixty percent of baseline demand over eight hundred iterations. A critical methodological refinement involved replacing standard robust Huber loss functions with an unclipped mean squared error loss for value baseline estimation. Because catastrophic collisions carry severe negative rewards of minus four hundred against nominal baseline progress rewards, robust loss formulations clipped backpropagated gradients on critical failure states, preventing the critic from effectively propagating risk signals into early braking horizons. By employing mean squared value loss paired with an advantage estimation discount parameter of zero point five and a discount factor of zero point nine nine, the system reliably developed anticipatory yielding and deceleration behaviors across ten thousand training episodes without resorting to artificial entropy bonuses or hand-engineered crossing heuristics.
System performance was systematically verified using a pre-specified, four-tier evaluation protocol designed to detect and prevent checkpoint selection optimism on held-out traffic seeds. In a dedicated rare-event testing tier comprising one hundred independently drawn, pre-specified Poisson traffic realizations at sixty percent operating demand, the bare learned policy—operating completely free of safety filters, collision-avoidance shielding, or rule overrides—achieved an average of zero point forty-three crash events per one-hundred-and-forty-second episode, remaining entirely collision-free on seventy out of the one hundred runs. It sustained an average throughput of seventy-nine completed trips per episode with a mean trip delay of two point four seconds. Compared directly on paired seeds against conventional fixed-time and detector-actuated signals, the bare policy delivered eight to twenty percent higher vehicle throughput while slashing trip delays by a factor of five to seven. When paired against a rule-based reservation controller operating on the same continuous control constraints, the learned policy cut total collision events by sixty percent while maintaining superior traffic flow.
A critical contribution of the research lies in disentangling genuine control competence from the artifacts of simulation accounting conventions and hybrid safety mechanisms. In a controlled two-by-two protocol factorial conducted on twenty held-out realizations, the researchers evaluated the exact same neural weights under both strict research accounting and prevailing simulator default configurations. Under strict accounting—which logs internal intersection contacts and immediately removes collided vehicles to isolate initial coordination failures—the bare policy recorded zero point seventy-five crash events per episode. However, switching to default simulator accounting, which disables interior junction collision sensors and teleports stuck vehicles, reduced recorded events to zero point thirty-five. Furthermore, when the policy was coupled with a lightweight rule-based following and reservation filter under default accounting conventions, the recorded crash rate dropped to absolute zero across all twenty realizations. This stark divergence demonstrates that previously published zero-collision results in autonomous intersection literature frequently certify the guarantees of auxiliary rule layers and lenient accounting rather than pure learned multi-agent competence.
Evaluating the cross-scale adaptability of the single frozen checkpoint, the researchers observed zero-shot transfer when deploying the four-lane trained model directly onto unseen one-lane, two-lane, and three-lane intersections without fine-tuning. Across twenty held-out realizations per scenario, the policy matched or exceeded the completion volumes of simulator-native drivers while reducing delays fourfold to sevenfold, maintaining crash rates between zero and zero point twenty-five events per episode. Similarly, in high-demand stress sweeps ranging from ninety to two hundred percent of nominal capacity, the learned policy maintained continuous vehicle liveness and avoided the severe gridlock collapse observed in default simulator models. At two hundred percent demand, representing an arrival volume of seven thousand seven hundred and fourteen vehicles per hour, the policy completed three hundred and thirty-two trips per episode, outperforming actuated signals by thirty-two percent while keeping delays at two point seven seconds, though collision frequencies climbed proportionally with traffic density.
The system also successfully scaled to a complex twenty-five-junction grid network composed of sixty two-lane and sixty one-lane directed roadway segments. Operating zero-shot on the signal-free grid at calibrated parity demand, the single-junction policy achieved four hundred and eight completed trips per four-hundred-second episode at twelve seconds of delay, matching the throughput of optimized actuated signals while achieving an eighty-three percent reduction in travel delay. When trained directly at network scale using a gentle demand ramp starting from the single-junction student checkpoint, the resulting network policy elevated completions to four hundred and seventy-three trips per episode while dropping the collision rate to zero point zero forty events per completed trip. Computational profiling confirmed strict linear execution scaling, with the total per-vehicle control step requiring approximately two point eight milliseconds on a single central processing core, verifying that the computational cost per vehicle remains constant as the population grows.
Despite these demonstrable gains in throughput and cross-network adaptability, the authors explicitly emphasize several operational boundaries and safety limitations that preclude immediate open-road deployment. Moreover, zero-shot evaluations in mixed-traffic scenarios containing uncalibrated human-driver models showed elevated rear-end collisions where the automated vehicle struck human-driven predecessors. The researchers conclude that while padding-free networked reinforcement learning resolves fundamental architectural scalability challenges for signal-free transit, reaching commercial safety thresholds requires integrating robust following constraints, explicit multi-agent intent communication, and diverse training exposures that encompass human driving variability.
Subject of Research: Scalable padding-free networked multi-agent reinforcement learning for signal-free intersection traffic control
Article Title: Scalable padding-free networked multi-agent reinforcement learning for signal-free traffic: One policy from a single junction to a 25-junction network
Article References: Adel, H., Awad, M. I., Emad, D., & Shehata, O. M. (2026). Scalable padding-free networked multi-agent reinforcement learning for signal-free traffic: One policy from a single junction to a 25-junction network. Results in Engineering, 32, Article 114021. https://doi.org/10.1016/j.rineng.2026.114021
Image Credits: AI Generated
DOI: 10.1016/j.rineng.2026.114021
Keywords: multi-agent reinforcement learning, autonomous vehicles, signal-free intersections, traffic coordination, distributed control, networked MARL, graph neural networks, SUMO simulation, decentralized execution, policy optimization, traffic throughput, vehicle-to-vehicle communication, collision rate, zero-shot transfer, Poisson arrivals, continuous control, advantage estimation, urban traffic networks
News Source: Denise Maddox. (November 12, 2026). Networked Multi-Agent Reinforcement Learning Directs Signal-Free Intersections Across Twenty-Five Junctions. Scienmag.