A distributed machine learning framework developed for satellite networks reduced the training time required to reach a benchmark accuracy target by 52 percent while boosting overall classification accuracy by two percentage points compared to conventional centralized federated learning. In an experimental evaluation involving sixteen client nodes and three cloud servers operating under restricted bandwidth conditions, the architecture completed in 87 minutes the model optimization that required three full hours under the classical Federated Averaging benchmark. The underlying system, created by researchers Qiang Mei, Rui Huang, Duo Li, Jingyi Li, Nan Shi, Mei Du, Yingkang Zhong, and Chunqi Tian, addresses severe communication bottlenecks, frequent orbital link disruptions, and skewed data distributions by restructuring traditional federated workflows into a multi-tiered hierarchy governed by decoupled transmission intervals and periodic synchronization.
Federated learning has gained prominence across distributed systems because it permits multiple participating devices to collaboratively optimize a shared global predictive model without exchanging their underlying training datasets. Under standard centralized machine learning paradigms, participating clients must transmit local observations to a central server, which incurs high network transmission overhead and risks data exposure whenever the stored local datasets exceed the size of the operational model. Federated learning mitigates these exposure hazards by requiring client nodes to conduct localized training and transmit only parameterized updates, including numerical weights or gradients, to aggregating servers. However, deploying standard federated workflows across orbital satellite systems introduces acute operational friction because satellite links exhibit constrained bandwidth, elevated latency, and periodic dropouts caused by satellite transits and transitions between low Earth orbit and high Earth orbit constellations.
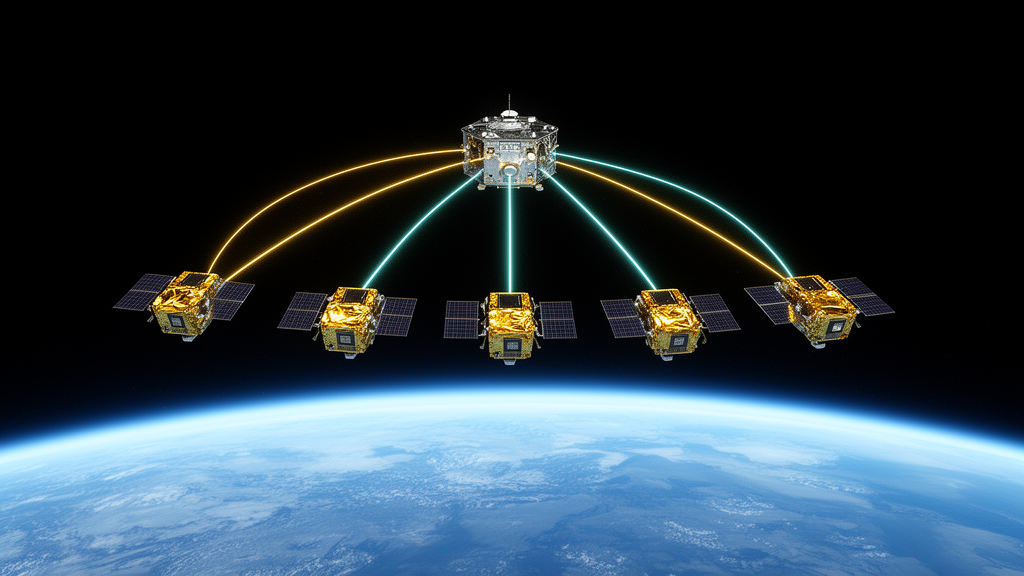
Orbital movement introduces fundamental physical constraints that prevent traditional mobile edge computing configurations from operating reliably across space networks. In conventional terrestrial architectures, stationary edge servers are permanently situated within physical proximity of client clusters to truncate communication distances, suppress transmission latency, and ease network congestion. By contrast, low Earth orbit satellites travel rapidly across varying orbital planes, continually shifting the physical distance and relative trajectory between spaceborne transceivers and ground-based instrumentation. This rapid motion makes fixed-location edge positioning unworkable and causes the radio signal path to traverse dynamic, unpredictable chains of ground reception stations. To accommodate these fluctuating ground connections, the investigated hierarchical framework organizes processing nodes into a cloud-edge-client structure where the intermediate edge cloud servers and the primary central cloud server are co-located directly at terrestrial ground landing stations to minimize ground-segment transmission delay.
The system establishes a strict separation between two primary operational tiers, decoupling localized edge-to-client operations from the wider edge-to-cloud coordination pipeline. At the lower tier, an edge-client semi-asynchronous control mechanism allows individual client nodes to conduct local model training without waiting for peers to finish computational cycles or maintain continuous network connectivity. In standard synchronous federated learning, every participating node must finish its computation and upload parameters within an identical aggregation round, meaning that slow client devices create a straggler effect that suspends progress across the entire network. If an orbital client disconnects unexpectedly, synchronous aggregation stalls indefinitely. The proposed semi-asynchronous strategy eliminates this vulnerability by enabling client nodes to run training and data transmission as two independent, parallel routines, thereby isolating local optimization from orbital communication availability.
Under this decoupled client regime, participating machines utilize their full computational resources to conduct continuous local model training even when physical satellite connectivity is interrupted. When an orbital communications window opens, the client checks the operational state of available ground-station servers and uploads its updated local parameters immediately, bypassing the requirement that other clients complete their respective training rounds. If an uploading node disconnects unexpectedly mid-transmission, the designated aggregating server removes that specific node from the active partial round so that remaining participants can proceed without interruption. Furthermore, client devices that generate updates within the same operational time slice are combined inside that single round, guaranteeing that no node remains queued for longer than one partial aggregation interval, thereby maximizing the practical utility of brief satellite communication windows.
To prevent arbitrary or congested routing across volatile orbital links, the framework incorporates an automated server selection mechanism that relies on a hybrid mathematical scoring model combining the Analytic Hierarchy Process with the Entropy Weight Method. Prior to dispatching parameter updates, each client measures four operational criteria across reachable cloud servers: round-trip communication latency, central processing unit workload, physical total upstream bandwidth, and real-time aggregation availability. Lower round-trip latency and lower processor loads indicate available capacity for rapid request handling, while higher upstream bandwidth ensures accelerated redistribution of aggregated parameters back to client nodes. The Analytic Hierarchy Process incorporates domain expertise by deriving subjective criterion weights through pairwise judgment matrices solved via root mean square calculations, while the Entropy Weight Method calculates objective weights based on statistical variability.
To guarantee numerical stability when processing performance metrics across diverse servers, the Entropy Weight Method incorporates an explicit stabilization constant into its normalization equation. In conventional min-max normalization, servers exhibiting nearly identical maximum and minimum metric values can drive denominators toward zero, triggering computational failures. The researchers resolved this vulnerability by adding a constant offset of 0.1 to the normalization denominator, preventing division by zero and preserving robust weighting even in the presence of extreme data outliers or irregular distributions. The resulting normalized values yield performance entropy measures, which are mathematically synthesized with the subjective weights from the Analytic Hierarchy Process to produce a comprehensive score. Client nodes prioritize idle aggregating servers and direct their local parameter payloads toward the highest-scoring candidate, effectively balancing system loads and preventing bottlenecks.
To aggregate local parameters collected through semi-asynchronous transmissions without distorting the global objective, the architecture replaces the standard Federated Averaging algorithm with a specialized memory-based averaging algorithm. Standard federated aggregation presumes that updates represent uniform, synchronous training rounds across participants. To accommodate asynchronous arrivals and intermittent participation, the cloud servers maintain a dynamic tracking table that pairs client network Internet Protocol addresses with their respective training sample sizes. When an individual client completes an upload, the edge server updates the sample volume assigned to that specific address and calculates the current partial model by combining the active upload with historical parameters weighted by the cumulative memorized sample counts of inactive client nodes, ensuring consistent representation even under non-independent and identically distributed conditions.
Computational complexity analysis shows that this memory-based averaging mechanism incurs only a modest processing overhead relative to the standard Federated Averaging benchmark. Standard federated aggregation over N participating clients with d-dimensional model weights scales with a computational complexity of O(Nd), reflecting the direct summation of updates received from all active contributors. The memory-based averaging formulation introduces an auxiliary storage requirement to retain past model states and cumulative sample counts across M memorized updates, expanding its formal complexity profile to O(Nd + Md). Although this increases local memory usage, the resulting structural retention enables cloud aggregators to assimilate irregular or low-quality updates systematically, preventing stale or delayed parameters from destabilizing convergence when operating over heterogeneous client datasets.
At the upper architectural tier, coordination between intermediate edge clouds and the central cloud server operates through a scheduled synchronous control strategy designed to preserve model freshness. Traditional hierarchical federated implementations employ trigger-based synchronization, allowing only those edge servers that have actively collected local client models to participate in subsequent global aggregation. Consequently, edge nodes that are bypassed by clients during certain rounds retain outdated parameter states, degrading global accuracy if they are subsequently selected for aggregation tasks. The scheduled synchronous strategy resolves this issue by replacing event triggers with a fixed temporal cadence established by system administrators. Operating over stable, high-reliability ground infrastructure, all edge servers transmit their partial models and average participant sample volumes to the central cloud at regular scheduled intervals.
During this scheduled global aggregation, the central cloud computes server contribution coefficients that scale proportionally with both the total count of contributing clients and their cumulative sample volumes, utilizing a plus-one mathematical baseline to guarantee non-zero operational weights. The central cloud server evaluates the resulting unified global model and distributes updated parameters back to edge cloud caches, ensuring that all ground stations maintain synchronized model states. In an illustrative security application described by the authors, this hierarchical pipeline enables fleets of unmanned aerial vehicles conducting border surveillance to maintain local raw visual and sensor data on internal storage devices, transmitting only model gradients via satellite relays to optimize regional security models without exposing underlying telemetry or flight records.
The experimental validation was executed using an empirical platform comprising three cloud servers and sixteen client virtual machines communicating over simulated satellite channels throttled to five megabits per second. The training workload employed a convolutional neural network trained on the Fashion-MNIST image classification benchmark partitioned across all sixteen client nodes using a Dirichlet distribution to synthesize severe non-independent and identically distributed data conditions. The evaluated neural network featured two five-by-five convolutional layers configured with 20 and 50 channels respectively, each followed by two-by-two max pooling operations, two fully connected layers containing 800 and 500 units, and a final ten-unit softmax classification layer, producing a complete parameter footprint of approximately 4.7 megabytes that required seven seconds for one-way channel transmission.
During empirical trials tracking global model accuracy against elapsed operating time, the hierarchical architecture exhibited early accuracy fluctuations over the initial five minutes as disparate local models began preliminary aggregation at the central server. Once this brief stabilization interval concluded, the hierarchical system established a sustained performance advantage over the conventional Federated Averaging benchmark. After three elapsed hours, the hierarchical framework attained a final global classification accuracy of 90 percent, whereas the traditional baseline achieved 88 percent. Furthermore, the proposed architecture reached the 88 percent threshold in 87 minutes, documenting a 52 percent reduction in the cumulative wall-clock time required to satisfy target convergence criteria while operating within band-limited, geographically dispersed network environments.
Subject of Research: Hierarchical federated learning in dynamic satellite communication networks
Article Title: Intelligent hierarchical federated learning system based on semi-asynchronous and scheduled synchronous control strategies in satellite network
Article References: Mei, Q., Huang, R., Li, D., Li, J., Shi, N., Du, M., Zhong, Y., & Tian, C. (2025). Intelligent hierarchical federated learning system based on semi-asynchronous and scheduled synchronous control strategies in satellite network. Autonomous Intelligent Systems, 5(1), Article 9. https://doi.org/10.1007/s43684-025-00095-z
Image Credits: AI Generated
DOI: 10.1007/s43684-025-00095-z
Keywords: federated learning, satellite networks, hierarchical architecture, semi-asynchronous control, scheduled synchronization, cloud-edge-client computing, analytic hierarchy process, entropy weight method, memory-based averaging, non-IID data, convolutional neural networks, edge computing, ground stations, straggler effect, data privacy, low Earth orbit
News Source: Veronica Carney. (November 12, 2026). Hierarchical Federated Learning Cuts Satellite Model Training Time by Over Half. Scienmag.