Internet of Things networks generate torrents of sensor data around the clock, but the standard way to find patterns in that data — shipping every raw reading to a central server for clustering — carries a double penalty. It exposes potentially sensitive information and it floods the network with traffic. A study published in the International Journal of Machine Learning and Cybernetics on 24 October 2026 proposes a way around both problems with a framework the authors call FedAE-KMeans.
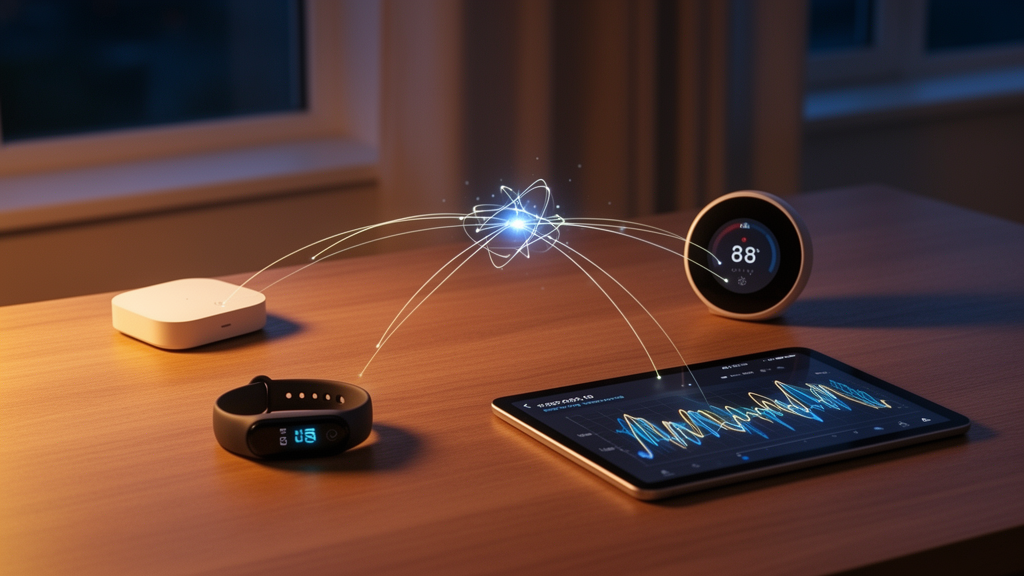
The core idea is to split the work between the devices and the server. Each IoT device trains a small autoencoder on its own local time series, learning to compress high-dimensional raw signals into compact latent vectors. Only those compressed representations, not the underlying sensor data, are transmitted to a central server, which then runs standard KMeans clustering in the shared latent space.
This architecture means the server never sees a single raw sample. Sensitive measurements stay on the device where they were produced, while the server still gains access to features rich enough to group devices and time windows into meaningful clusters. The design also attacks the communication bottleneck, because latent embeddings are far smaller than the raw data streams that centralized pipelines would normally move across the network.
The researchers evaluated the framework under non-IID data distributions, the heterogeneous conditions that mirror real deployments where each device sees a different slice of the world. On the MNIST benchmark, FedAE-KMeans reached a silhouette score of 0.677 and a clustering purity of 89.3 percent, improving purity by more than 16 percent compared with standard KMeans applied without the learned representations. The more demanding CIFAR-10 dataset stressed the method further.
There the framework attained a clustering purity of 78.6 percent and reduced the Davies–Bouldin Index to 1.08, a metric where lower values indicate better cluster compactness and separation. The authors interpret these numbers as evidence that the autoencoder-derived latent space remains effective even when the data held by individual devices are far from uniformly distributed. Communication efficiency proved to be one of the most striking results.
By transmitting only latent embeddings instead of raw samples, the framework reduced communication overhead to less than 8 percent of the data volume typically required by centralized methods. That reduction follows directly from the size difference between compressed latent vectors and the raw samples centralized approaches must transmit. The balance the framework strikes is threefold.
Clustering accuracy is preserved or improved through learned representations, privacy is protected because raw data never leave the device, and network load is reduced because only compressed vectors travel. The authors present this triad as the central contribution of the work for distributed IoT environments. It is worth noting the scope of the evidence.
The reported experiments were conducted on MNIST and CIFAR-10 under non-IID conditions rather than on live deployments of physical sensor networks, so the results demonstrate clustering effectiveness and robustness on benchmark data rather than field performance. The abstract describes the evaluation as extensive, but readers should treat the benchmarks as a proxy for the heterogeneous data conditions found in IoT networks. Within that scope, the study offers a concrete recipe for distributed pattern discovery: devices learn useful representations locally and hand up only distilled features, so clustering across large fleets of sensors no longer requires surrendering the raw data.
Subject of Research: Federated privacy-preserving time series clustering for distributed IoT devices
Article Title: Cross-device privacy preservation time series clustering in IoT networks space with federated learning algorithm
Article References: Rajpar, S. A., Chen, H., & Ashiru, A. (2026). Cross-device privacy preservation time series clustering in IoT networks space with federated learning algorithm. International Journal of Machine Learning and Cybernetics, 17(11), Article 506. https://doi.org/10.1007/s13042-026-03338-4
Image Credits: AI Generated
DOI: 10.1007/s13042-026-03338-4
Keywords: federated learning, IoT, time series clustering, autoencoder, KMeans, privacy preservation, non-IID data, latent representations, communication efficiency, MNIST, CIFAR-10, Cross-device
News Source: Veronica Carney. (October 24, 2026). Federated Learning Lets IoT Devices Cluster Time Series Without Sharing Raw Data. Scienmag.