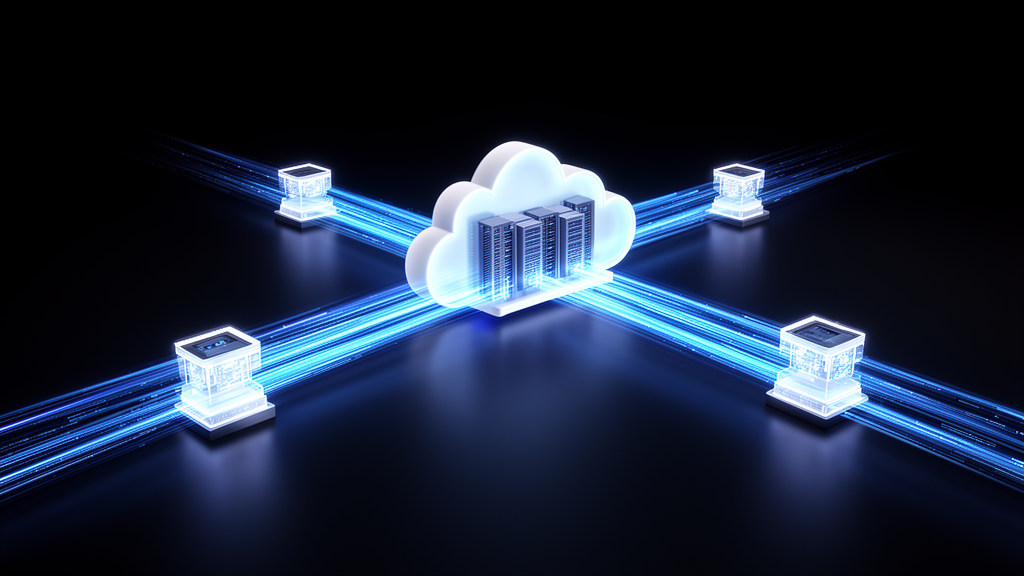
A collaborative computing framework that splits reasoning tasks between local edge hardware and remote cloud servers can lower end-to-end latency by 57.8 percent and reduce cloud API token usage by 78.0 percent. Described in the Journal of Cloud Computing by Yan Huang and colleagues, the system, named CE-Agent, addresses the fundamental resource and capability trade-offs that complicate the deployment of autonomous large language model agents on resource-constrained devices.
Running large language model agents directly on edge hardware is typically impeded by physical memory constraints. While offloading all processing to cloud infrastructure bypasses device memory limits, pure cloud setups introduce high transmission latency, consume substantial network bandwidth, and risk exposing sensitive local user data to external networks. Conversely, deploying static small language models locally at the edge keeps data nearby but leaves agents unable to reliably execute complex multi-step reasoning procedures.
To overcome these competing constraints, the researchers developed CE-Agent as an architecture-agnostic framework that coordinates lightweight local processing with cloud-based intelligence. The edge component operates alongside a dynamic in-process offloading router that continually inspects the progress of local multi-step reasoning. Instead of transferring every complex query immediately, the router tracks two real-time indicators: the entropy of generated tokens and errors encountered during the execution of local tools.
When token entropy or tool failure metrics exceed a designated uncertainty threshold, CE-Agent pauses local processing rather than continuing through an erroneous reasoning chain. The system then compresses the accumulated historical text context to conserve network resources. Once compressed, the remaining inference steps and associated context are transmitted across the network to a larger cloud-hosted language model to complete the multi-step trajectory.
Beyond handling immediate inference offloading, the framework incorporates a cloud-assisted trajectory distillation loop designed for ongoing edge model improvement. As the cloud model successfully resolves offloaded tasks, the cloud server processes these completed trajectories using Direct Preference Optimization. The resulting performance gains are packaged as Low-Rank Adaptation parameter weights and periodically transmitted back to synchronize with the edge model, supporting progressive capability evolution without demanding intensive local training.
In benchmark evaluations, CE-Agent achieved a 91.5 percent task success rate on the ALFWorld environment and an 84.2 percent success rate on the WebShop benchmark. Experimental tests confirmed that the system functions effectively under network bandwidth constraints as low as 10 megabits per second without tying implementation to a specific base model architecture. The authors noted several operational limitations that warrant continued investigation, including residual privacy considerations, risks of model collapse during iterative distillation, and unpredictable network variability.
Subject of Research: Cloud-edge collaborative framework for large language model agents
Article Title: CE-Agent: a cloud-edge collaborative agent framework with dynamic offloading and synergistic distillation
Article References: Huang, Y., Zhang, M., Lei, H., Ji, C., Wang, J., & Zhu, H. (2026). CE-Agent: a cloud-edge collaborative agent framework with dynamic offloading and synergistic distillation. Journal of Cloud Computing. https://doi.org/10.1186/s13677-026-00984-5
Image Credits: AI Generated
DOI: 10.1186/s13677-026-00984-5
Keywords: CE-Agent, cloud-edge collaboration, large language models, small language models, dynamic offloading, synergistic distillation, direct preference optimization, low-rank adaptation, token generation entropy, tool execution errors, multi-step reasoning, ALFWorld benchmark, WebShop benchmark, end-to-end latency, cloud API token consumption, edge computing, uncertainty threshold, context compression
News Source: Denise Maddox. (November 19, 2026). Cloud-Edge Agent Framework Cuts Latency by 57.8 Percent in Multi-Step Tasks. Scienmag.