Researchers have shown that an artificial intelligence controller, trained entirely inside a data-driven simulation of a vacuum system, can take over the delicate job of regulating pressure in a prototype built to mirror the most demanding section of a fusion materials testing accelerator. The work, published in EPJ Research Infrastructures, forms part of the DONES-FLUX project and targets the MuVacAS prototype, an experimental platform that reproduces the final metres of the beamline of the International Fusion Materials Irradiation Facility – Demo Oriented NEutron Source, or IFMIF-DONES, currently under construction.
The underlying problem is one of the harsher instrumentation challenges in fusion research. IFMIF-DONES will accelerate a high-power beam of deuterons into a flowing stream of liquid lithium, where stripping reactions generate an intense neutron flux designed to mimic the radiation environment inside a fusion power plant. Candidate structural materials for future reactors will be qualified by exposure to this flux. In the target region, the pressure must be held within a narrow window between 10^-4 and 10^-5 mbar: too high, and the beam scatters off gas molecules and interacts undesirably with the lithium surface; too low, and the free lithium surface can boil or vaporise excessively, threatening both beam transport and target integrity.
Keeping that balance is complicated by two constraints. Physical pressure sensors cannot survive long inside the target vacuum chamber because the extreme irradiation would destroy them, so the chamber pressure must instead be inferred from gauges placed upstream along the beamline. In addition, gas flow under high-vacuum conditions behaves in a strongly nonlinear way, which conventional controllers struggle to handle when the system drifts outside the narrow range for which they were tuned. The team therefore built a workflow that pairs two learned surrogate models with a deep reinforcement learning agent, allowing the pressure inside the irradiation zone to be estimated and controlled without any sensor at the point of interest.
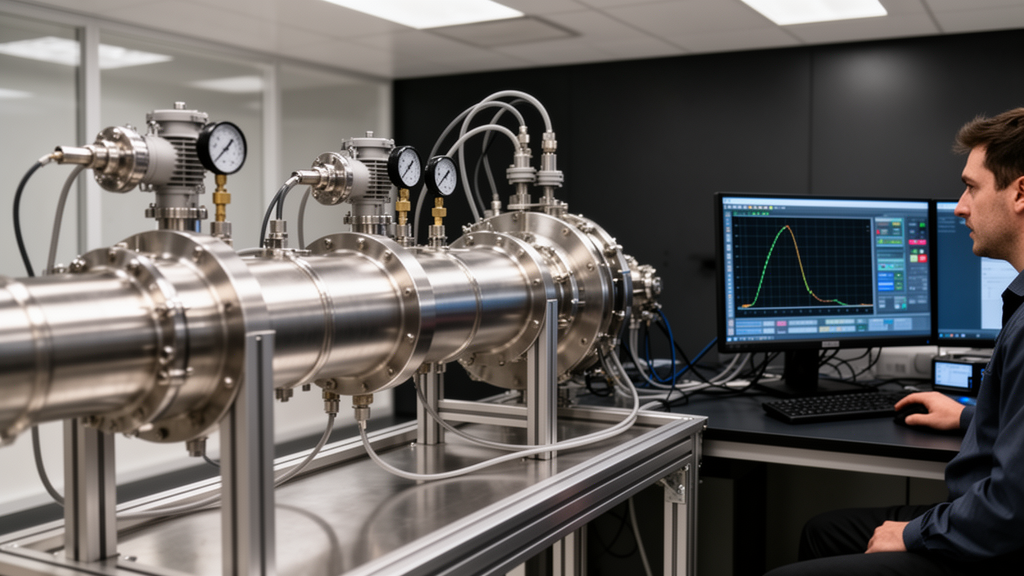
The MuVacAS prototype itself spans 28 metres and a total internal volume of 1.38 cubic metres, divided between a mock-up of the High Energy Beam Transport vacuum line and the target vacuum chamber, a cylinder 600 millimetres across and 1135 millimetres long. Five turbomolecular pumping groups maintain the differential vacuum profile along the line, while argon is injected into the target chamber through a dedicated module with a mass flow controller operating between 0.001 and 1 standard cubic centimetres per minute. Twelve cold-cathode gauges log pressure along the beamline, and the injection module offers two alternative lines: a short 0.5-metre path feeding the chamber directly, and an 18-metre path that routes gas from a distant controller, replicating the remote placement forced by radiation levels in the final facility.
Both surrogate models are Fourier Neural Operators, an architecture that learns mappings between function spaces by applying learned weights to selected Fourier modes, giving it an efficient grasp of long-range correlations in physical fields. The first model acts as a virtual sensor: fed with the history of the argon injection command and the pressures measured by upstream gauges, it predicts the pressure inside the target chamber in real time, evaluated every second. Trained on roughly nine hours of recorded operation from early argon injection campaigns, with a temporal input window of 100 one-second steps, it achieved a mean absolute percentage error of 4.59 percent on held-out test data. The authors note that this metric is sensitive to outliers and biased toward errors at low true values, with some individual points exceeding 40 percent absolute percentage error.
The second neural operator serves as a digital twin of the system’s dynamics. It takes the current pressure profile along the beamline and the argon injection rate and predicts the pressure field one second later. Applied repeatedly, with its own predictions fed back as inputs, it simulates the system over long horizons without touching the physical machine. Across a 1200-step autoregressive rollout on held-out data, the model reached a mean absolute percentage error of 14 percent over the full pressure field and, crucially, never diverged, making it stable enough to serve as a training ground for a reinforcement learning agent.
Inside this simulated environment, the team trained an agent using Proximal Policy Optimization, a widely used on-policy reinforcement learning algorithm for continuous control. The agent observes the current chamber pressure, the target pressure and the present injection rate, and outputs a commanded argon flow bounded between 0.01 and 0.9 sccm. Its reward is an exponential function of the deviation between achieved and target pressure, decaying smoothly as the error grows. During simulated evaluation across randomly initialised episodes, the agent kept the pressure within 0.02 logarithmic units of the target in a high proportion of trials, and its policy network generates actions in well under a millisecond on an ordinary industrial PC without a graphics card, comfortably matching the roughly one-hertz control cycle of the physical injection system.
The deployment experiments carried a built-in handicap: all training data had been recorded with the short injection line, while every real-time test used the long 18-metre configuration, which introduces a transport delay and altered dynamics the agent had never seen. Despite this distribution shift, the agent regulated the chamber pressure across all six direct-sensor experiments, tracking both fixed and randomly varying setpoints. With short 50-second step intervals the transport delay sometimes prevented it from fully reaching the target in the allotted time, though it consistently moved toward it; with intervals of 200 or 600 seconds it converged in every case. Two characteristic behaviours emerged in both simulation and reality: pressure rises faster than it falls, reflecting the asymmetry between quick gas injection and slower pumping, and each setpoint change triggers a brief overshoot in injection followed by correction.
The most consequential test closed the control loop entirely without a physical measurement at the chamber. Here the agent relied on the virtual sensor’s estimate, derived only from upstream gauges, as its observation of the chamber pressure. In step and multi-step reference experiments it still drove the system to the target, with the expected transient lag and overshoot, and the estimated observations showed slightly higher high-frequency variance because combining multiple upstream gauges propagates small fluctuations into the state estimate. The policy proved resilient to this added noise. For the authors, this fully data-driven loop is the result that matters most for the final facility, where in-chamber pressure measurement will generally be impossible.
A head-to-head comparison against classical proportional-integral-derivative controllers under the long-line configuration sharpened the picture. Both the original PID, tuned for the short line, and a re-tuned version for the long line oscillated and produced severe actuator chattering, with injection commands fluctuating rapidly and hitting operational limits, a pattern that would accelerate wear on valves and injection hardware in a real machine. The reinforcement learning agents reached the target region quickly and settled smoothly, with markedly cleaner control effort. Yet the comparison was not one-sided: the re-tuned PID achieved the best absolute steady-state accuracy, while both agents stabilised slightly above the target. The researchers attribute this offset to a seasonal shift between the summer training campaign and the November comparison test, which changes outgassing and pumping behaviour, compounded by undocumented changes to the prototype, and they point to hybrid reinforcement-learning-plus-integral schemes or online adaptation as future remedies. They also caution that validation so far has been limited by prototype availability, restricted to the long injection line, and that broader campaigns, disturbance-rejection tests and sensor-failure studies remain before such controllers could be integrated into the final IFMIF-DONES control architecture.
Subject of Research: AI-based autonomous control of differential vacuum pressure in the MuVacAS prototype for the IFMIF-DONES fusion materials facility.
Article Title: AI-Based Control of Differential Vacuum in the MuVacAS Prototype for IFMIF–DONES Particle Accelerator
Article References: Rodríguez-Llorente, G., Gallardo Romero, G., Morant Navascués, R., Sabogal, A., Torregrosa-Martín, C., Podadera, I., Weber, M., L. Bonilla, L., & Gómez-Espinosa Martín, R. (2026). AI-Based Control of Differential Vacuum in the MuVacAS Prototype for IFMIF–DONES Particle Accelerator. EPJ Research Infrastructures, 10(1), Article 33. https://doi.org/10.1007/s41781-026-00186-3
Image Credits: AI Generated
DOI: 10.1007/s41781-026-00186-3
Keywords: IFMIF-DONES, nuclear fusion, vacuum technology, reinforcement learning, Fourier Neural Operator, virtual sensor, digital twin, MuVacAS, particle accelerator, materials testing, deep learning, control systems
News Source: Katie Riggs. (October 28, 2026). AI Learns to Steer Vacuum Pressure in Fusion Materials Accelerator Prototype. Scienmag.