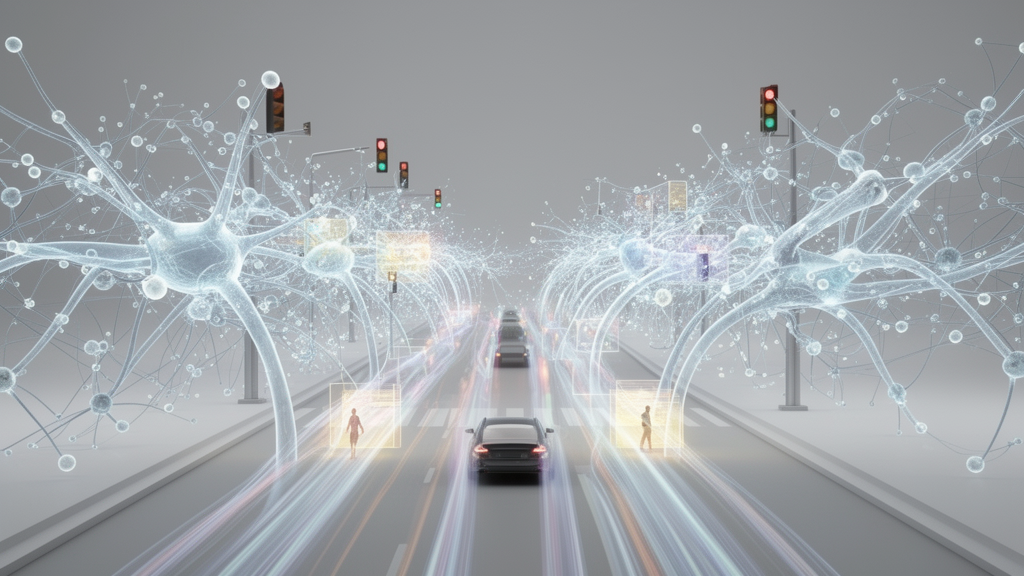
Researchers at Imperial College London have developed a vision-language framework designed to predict imminent vehicle collisions while generating natural-language explanations for its assessments. Combining task-specific fine-tuning, a two-step chain-of-thought prompting strategy, and feature-based knowledge distillation, the customised system achieved an average prediction accuracy of 84.7 percent in experimental evaluations. Published in Communications in Transportation Research, the study demonstrates that the model can provide textual rationales alongside collision forecasts while maintaining computational efficiency.
Vehicle collision warning systems can support timely warnings and interventions, but conventional deep learning models frequently provide limited explanation for their predictions. While vision-language models offer a potential solution by jointly analysing driving videos and generating natural-language rationales, general-purpose models typically lack specialised collision-related knowledge and require substantial computational resources to deploy.
To address these challenges, the researchers fine-tuned a general-purpose vision-language model using real-world video clips of both pre-collision events and normal driving conditions. The system utilized a two-step chain-of-thought prompt that guided the model to first analyse the driving scene and identify potential risk sources, and subsequently predict whether a collision was likely to occur imminently. This structured prompting approach enabled the resulting model to provide both an operational prediction and an accompanying natural-language explanation.
Knowledge was subsequently transferred from the customised teacher model to a smaller student model using feature-based knowledge distillation. During this distillation process, the teacher model was kept frozen while only the student model’s large language model backbone was optimized by aligning intermediate hidden representations between the two models. In experimental testing, the customised model achieved an average accuracy of 84.7 percent, precision of 83.6 percent, and recall of 86.8 percent, outperforming conventional deep learning baselines. The distilled student model retained more than 95 percent of the teacher model’s prediction performance while reducing inference latency by over 50 percent.
The study provides a new approach to balancing prediction performance, explainability, and computational efficiency in vision-based collision warning systems. According to the research team, future work could incorporate additional vehicle kinematic information and further investigate the internal reasoning mechanisms of vision-language models.
The peer-reviewed publication, titled “Distilling Vision-Language Models for Explainable Vehicle Collision Prediction,” was published on September 30, 2026. The research appeared in Communications in Transportation Research, which was launched in 2021 with academic support provided by Tsinghua University and the China Intelligent Transportation Systems Association.
The journal’s Editors-in-Chief are Professor Xiaobo Qu, a member of the Academia Europaea from Tsinghua University, and Professor Xiaopeng (Shaw) Li from the University of Wisconsin–Madison. Under their editorial leadership, the publication mainly features high-quality, original research and review articles of significant importance to emerging transportation systems. The journal aims to serve as an international platform for showcasing and exchanging innovative achievements in transportation and related fields, while fostering academic exchange and development between China and the global community.
Since its launch, Communications in Transportation Research has been indexed across multiple major databases, including SCIE, SSCI, Ei Compendex, Scopus, CSTPCD, CSCD, OAJ, DOAJ, and TRID. The journal was selected as a Q1 Top Journal in the Engineering and Technology category of the Chinese Academy of Sciences Journal Ranking List.
In 2022, Communications in Transportation Research was selected as a High-Starting-Point new journal project of the “China Science and Technology Journal Excellence Action Plan.” In 2024, it was selected as the Support the Development Project of “High-Level International Scientific and Technological Journals,” and that same year it was also chosen as an English Journal Tier Project of the “China Science and Technology Journal Excellence Action Plan PhaseⅡ.” In 2024, the journal received its first impact factor, with a 2023 impact factor of 12.5, ranking first among all 58 journals in the Q1 tier of the transportation category. In 2026, its 2025 impact factor was announced as 12.7, maintaining the top ranking among 66 journals in the same category. From Volume 6 in 2026, the journal is published by Tsinghua University Press on the SciOpen platform.
Subject of Research: Vision-language models for explainable vehicle collision prediction
Article Title: Can vision-language models predict imminent vehicle collisions accurately, explicably and efficiently?
Article References: Can vision-language models predict imminent vehicle collisions accurately, explicably and efficiently?. Original publication (Bibliographic details unavailable.)
Image Credits: AI Generated
DOI: Not provided
Keywords: vision-language models, vehicle collision prediction, knowledge distillation, traffic safety, chain-of-thought prompting, deep learning, intelligent transportation systems, vision-language, models, predict, imminent, vehicle
News Source: Denise Maddox. (November 7, 2026). Vision-Language Models Predict Imminent Vehicle Collisions With Explainable Rationales. Scienmag.