A federated learning system that jointly processes speech, images and text improved English translation and recognition across simulated classroom lectures, remote courses and on-site conversations while keeping the underlying learning data on individual clients. The study tested the Federated Enhanced Multi-modal Translation and Recognition model, or FE-MTR, against a conventional Transformer, FedAvg with a Transformer, pFedMe and FedProx. On the test set, FE-MTR reached a Bilingual Evaluation Understudy score of 35.1, compared with 28.3 for the conventional Transformer and 30.6 for FedAvg with a Transformer. Its word error rate was 0.163 and its character error rate was 0.108. These results came from simulated federated training rather than a deployment in an operating school or on consumer mobile devices.
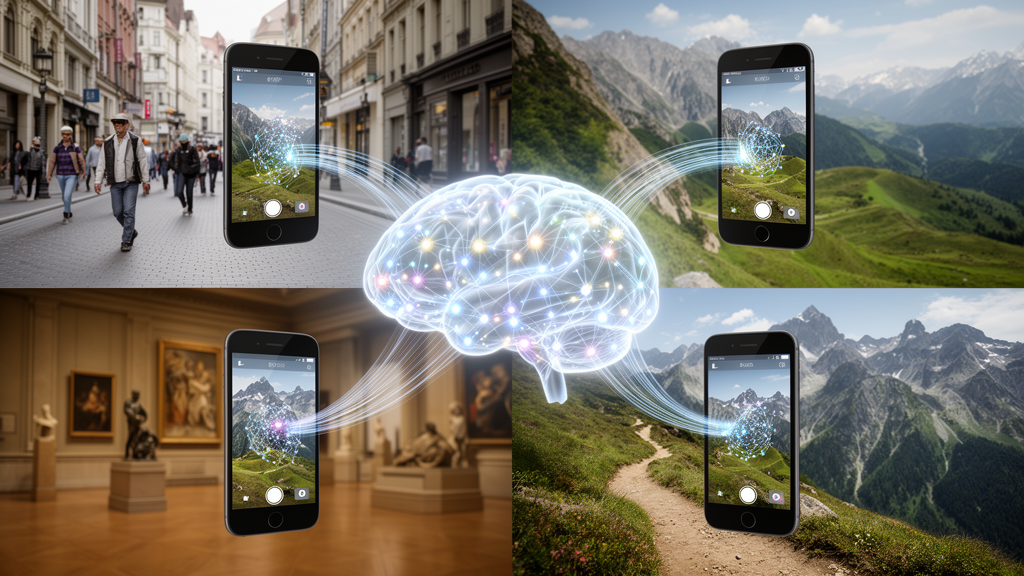
FE-MTR was designed to address a problem in mobile multimedia teaching: useful speech and teaching data are distributed among classrooms, distance-learning platforms and other institutions, while centralized collection can create privacy and data-silo concerns. Each client contains audio, visual and text encoders that process information locally. A central server initializes and distributes the global model, receives model updates rather than raw recordings or text, aggregates those updates, and sends the revised model back to participating clients. The application layer can provide speech recognition, subtitles, cross-scenario translation, oral error correction and multimodal teaching feedback. Raw user data therefore remain on client devices under the federated architecture, although the study separately adds Gaussian noise to uploaded parameters to provide differential privacy.
The model treats translation and recognition as a multimodal task. Audio is converted into feature vectors through four one-dimensional convolutional layers and temporal self-attention, visual information is processed by a ResNet-18 backbone, and text is encoded by a six-layer Transformer. Each modality is projected into a common 512-dimensional space, normalized with L2 normalization and combined through attention-weighted early fusion. The attention weights are learned locally, allowing a client facing noisy speech to place greater emphasis on text and a client processing visually rich teaching material to give more weight to visual information. The audio encoder uses kernel sizes of 80, 40, 20 and 10, with strides of 4, 2, 2 and 1, while both the temporal and text attention systems use eight heads and a hidden dimension of 512.
A cross-modal contrastive loss is intended to bring representations of the same meaning closer together while separating unrelated examples. Its temperature coefficient is 0.07, and similarity is calculated with cosine similarity. FE-MTR also uses bidirectional multi-head co-attention: speech acts as the query against text keys and values, while text serves as the query against speech. The two directional outputs are concatenated and passed through a feedforward network, allowing the model to connect spoken segments with corresponding textual semantics. The study identifies this cross-modal attention module and the federated framework as the largest contributors to performance, while alignment and regularization provide smaller additional gains in ablation tests.
Federated averaging forms the basis of collaborative training. Each client performs several local optimization steps, after which the server weights updated parameters according to local dataset size. To counter the effects of non-independent and identically distributed client data, FE-MTR adds a FedProx-style penalty that limits how far a local update can move from the global model; the reported balance parameter is 0.01. The server also randomly selects clients in each round rather than always using the same set. Before upload, client parameters receive zero-mean Gaussian noise with a reported scale of 0.01. At that setting, the study reports an approximate differential-privacy budget of ε = 1.5 with δ = 10⁻⁵. Privacy was assessed mainly through theoretical analysis of gradient-leakage and inference attacks; the researchers did not conduct empirical attack simulations.
The experiments simulated 50 virtual school or class clients using material from TED Talks, the International Workshop on Spoken Language Translation and the European Language Resources Association. TED Talks supplied speech and subtitles, IWSLT supplied multilingual parallel and dialogue material, and ELRA contributed multi-speaker English recordings and teaching-oriented conversations. Client data were deliberately heterogeneous: clients received different topics, speech quality, text lengths and speaking styles, while IWSLT was split by speaker and ELRA by scenario type. Classroom teaching and on-site conversation were represented by TED and IWSLT data, while remote courses used lower-quality far-field recordings. Training included white background noise, whereas testing added café and street noise, unseen accents such as Indian and Australian English, and faster and slower speech.
All models were trained for 100 federated rounds with a batch size of 64 and five local training steps per participating client. The learning rate and regularization coefficient were selected by grid search on validation data, and the models were kept at broadly comparable scale, with approximately 210 million parameters each. Every experiment was repeated five times with different random seeds, and the reported averages were compared using paired t-tests for BLEU, word error rate and character error rate. FE-MTR’s reported improvements over the comparison models had p-values below 0.05. The full model produced a training-set BLEU score of 43.5, with a word error rate of 0.138 and character error rate of 0.097. Its validation scores were 36.8, 0.162 and 0.109, respectively, while its test scores were 35.1, 0.163 and 0.108.
The 8.4-point difference between FE-MTR’s training and test BLEU scores indicates that the model did not perform identically under the imposed domain shift. The researchers attributed the decline to unseen accents and noise, non-independent client data and the small negative effect of privacy noise. Nevertheless, the test score remained above those of the comparison systems. Transfer accuracy was also relatively stable across the three teaching environments. On the test set, FE-MTR achieved accuracies of 0.940 for classroom teaching, 0.897 for remote courses and 0.846 for on-site conversations, producing a reported cross-scenario difference, ΔAcc, of 0.094. The corresponding validation figures were 0.948, 0.912 and 0.877, with a difference of 0.071, while the training-set difference was 0.059.
Conversation remained the most difficult test environment. Its lower accuracy was associated with environmental sounds, overlapping speakers, far-field signal attenuation, pauses, repetitions and self-corrections, as well as fragmented and colloquial language. Conversational material also made up only about 15% of the training data, compared with higher-quality, more standardized TED material used for classroom teaching. The results therefore show robustness across the tested conditions but also expose a weakness in the least represented and acoustically challenging scenario. The study did not establish that the model would perform equally well in real classrooms, because the three teaching environments were simulated from existing corpora rather than monitored through a live educational deployment.
Ablation experiments showed that removing federated learning had the largest effect, lowering test BLEU from 35.1 to 31.2 and increasing ΔAcc from 0.094 to 0.142. Replacing the multi-head attention module with simple feature concatenation reduced BLEU by 2.3 points and raised word and character error rates to 0.175 and 0.116. Removing the alignment loss cost 1.6 BLEU points, while removing personalization regularization cost 0.9 point and worsened ΔAcc to 0.113. Disabling differential-privacy noise changed BLEU by only 0.1 point. In the privacy-utility analysis, noise scales of 0.001, 0.01 and 0.1 produced BLEU scores of 34.9, 35.1 and 32.4, with approximate privacy budgets of 4.2, 1.5 and 0.3, respectively.
Deployment remains the clearest obstacle to turning the experimental result into an immediate mobile-learning tool. Each participating client must download and upload an 840-megabyte model update, requiring about 1.68 gigabytes of bidirectional traffic per round. On the modeled 50-megabit-per-second downlink and 20-megabit-per-second uplink, transfers take roughly eight minutes, while local multimodal training takes about 45 minutes, producing an estimated round duration of 53 minutes and about 88 hours across 100 rounds. Local computation, rather than the few seconds required for server aggregation, accounts for approximately 85% of the reported delay. The experiments used an NVIDIA A100 server and did not measure inference latency, energy use or thermal behavior on smartphones or tablets. Compression, quantization, pruning and knowledge distillation were proposed as future ways to reduce this burden, but their effects were not tested. The findings support FE-MTR as a technically promising but still server-dependent model for privacy-preserving, cross-scenario English teaching, rather than as a fully validated mobile system.
Subject of Research: Federated multimodal learning for cross-scenario English translation and speech recognition
Article Title: Design of an English cross-scene model for enhanced mobile multimedia based on federated learning
Article References: Huang, X., & Chen, S. (2026). Design of an English cross-scene model for enhanced mobile multimedia based on federated learning. Discover Artificial Intelligence, 6(1), Article 1152. https://doi.org/10.1007/s44163-026-02081-7
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02081-7
Keywords: federated learning, multimodal learning, English translation, speech recognition, differential privacy, mobile learning, cross-scenario transfer, multimodal attention, Design, English, cross-scene, model
News Source: Veronica Carney. (October 26, 2026). Design of an English cross-scene model for enhanced mobile multimedia based on federated learning. Scienmag.