A conceptual framework for making AI-based autonomous-driving perception systems safer proposes combining three runtime monitors that inspect different signs of unreliable behavior. Designed around the Safety of the Intended Functionality standard, ISO 21448, the ensemble could help engineers identify near-failure situations, uncover unfamiliar road scenarios and assemble additional evidence about residual risk. The proposal is not a completed safety system: the researchers did not implement the coordinated ensemble or quantitatively evaluate it, and their findings show how monitor outputs might fit into a structured safety argument rather than proving that autonomous vehicles are safe.
The central problem is that a machine-learned perception model cannot be shown correct for every possible input. Its operational environment is open, nondeterministic and only partly foreseeable, while a pixel-precise specification of every relevant object, road user and weather condition is unavailable. Small input alterations can also produce adversarial examples, although the paper notes that deliberate attacks should not be confused with the much rarer spontaneous failures observed in ordinary field operation. The authors therefore frame the engineering objective as demonstrating that residual risk is acceptably low, not that the system is absolutely error-free or safer than every human driver.
ISO 21448 supplies the safety scaffolding for that objective. It asks manufacturers to identify functional insufficiencies, describe the conditions that trigger them, assess associated hazards and residual risk, and then use verification, validation and operational feedback to build a safety case. Its central scenario objective is to turn unknown or hazardous situations into known, adequately controlled ones over successive development cycles. The standard leaves considerable freedom in how those activities are carried out, creating room for engineering methods such as runtime monitoring. It complements, rather than replaces, conventional functional-safety work aimed at faults in hardware and manually engineered software.
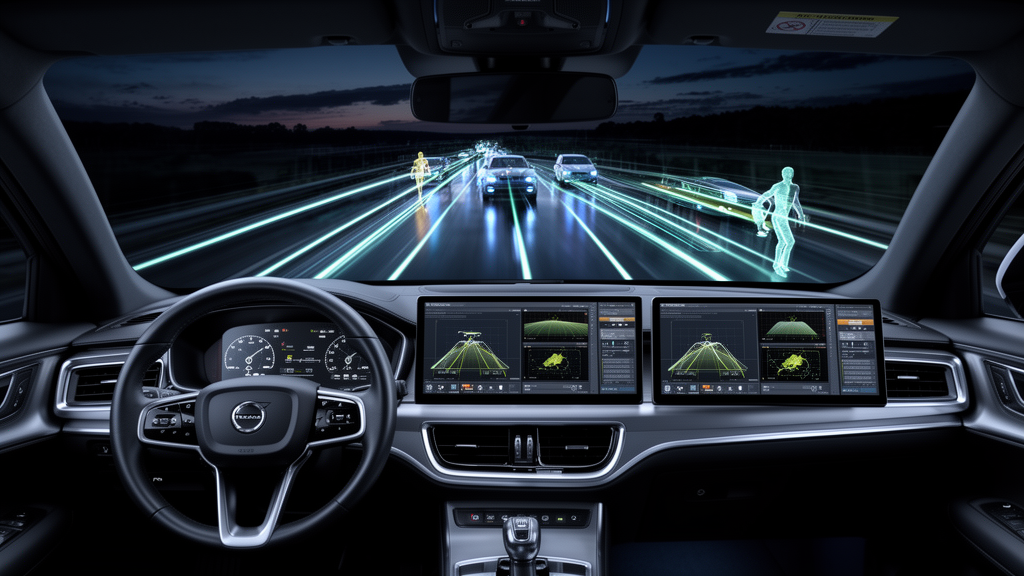
The proposed ensemble comprises a function monitor, a situation monitor and a validity monitor. The function monitor compares outputs from redundant perception systems, such as camera- and LiDAR-based object detectors, and raises an alarm when they fail to identify objects consistently within a dynamically calculated safety zone near the vehicle. That zone depends on vehicle speed and steering angle, so the comparison is directed toward areas important to immediate control. The situation monitor compares current input-output behavior with representations learned during development or training, potentially using compact references or embeddings rather than the complete raw dataset. The validity monitor examines the neural network’s internal activation patterns for signs that inputs differ substantially from those encountered during training or validation.
Each monitor therefore looks for a different expression of uncertainty. The function monitor targets disagreement between redundant channels, the situation monitor targets novel combinations of inputs and outputs, and the validity monitor targets unfamiliar behavior inside the model. The authors describe two validity-monitor variants: one evaluates the network’s overall activation pattern, while another attaches confidence scores to detected objects and treats low scores as possible warning signs. Together, the outputs could be synthesized into an estimate of how likely the perception result is to be correct. Depending on the wider system design, that signal might inform a path planner, activate a fail-safe mode or select valuable situations for later engineering analysis.
During risk identification, monitor warnings could serve as candidates for deeper hazard analysis rather than as automatic diagnoses. A novel situation or an inconsistency between redundant detectors may reveal a triggering condition that the perception system was not designed to handle, even if no accident occurs during that particular encounter. Events that trigger several monitors could be prioritized for review. The framework also proposes recording correlations among monitor warnings, road-test events and simulations or controlled hazardous scenarios. If those relationships are validated, the warnings could serve as proxy indicators for hazards that are too rare to measure directly, contributing statistical evidence to residual-risk arguments.
The same evidence could support verification and validation. Novelty rates from the situation monitor might become coverage metrics for the diversity of road testing, while validity-monitor frequencies could indicate weaknesses in the maturity or representativeness of available training data. During evaluation of known scenarios, all three monitors can highlight cases requiring closer analysis, but they do not independently prove that perception is correct or incorrect. In simulator experiments with ground truth, researchers could correlate monitor activation with actual functional insufficiencies. If such correlation were established, monitor outputs might become a denser proxy for rare failures and potentially reduce the number of fleet kilometres needed to reach a chosen statistical confidence.
That potential reduction in testing effort remains conditional rather than demonstrated. The reliability of each monitor, the correctness of any fallback strategy and the way warnings are integrated into vehicle behavior all affect the result, while the monitors themselves require specification, implementation, verification, validation and integration. They add components and assurance obligations to a safety-critical architecture. The paper therefore treats monitor-informed efficiency gains as a direction for future evaluation, not an established outcome, and emphasizes that coordinated operation of the ensemble has yet to be assessed systematically even though individual monitor types have been studied in earlier experimental work.
After deployment, the ensemble could also support the operational-phase activities required by ISO 21448. Monitor output might reveal environmental changes, misuse outside the intended operating domain, previously unknown hazards or functional insufficiencies. It could also filter the enormous volume of field data: situations flagged by several monitors might be sent for manual inspection or engineering review, while routine events need not all be transmitted. The authors also suggest that future guidance could address the structured sharing of selected near-failure observations among organizations, a potentially useful way to convert rare situations into shared knowledge, although ownership, privacy, liability, anonymization and competitive sensitivity would need to be resolved before any concrete mechanism could be proposed.
The research’s main contribution is therefore a map between three complementary monitoring functions and selected parts of the SOTIF lifecycle. The proposal connects runtime assurance with risk identification, scenario discovery, test planning, residual-risk evidence and field feedback, while acknowledging that compliance comes from the complete safety case rather than from any single monitor. No datasets were generated or analyzed because the study was conceptual and methodological. The next decisive step is to instantiate the ensemble in a concrete perception architecture and measure how its combined output relates to genuine safety-relevant failures, near-failures and operational scenarios. Until that evidence exists, the framework is best understood as a disciplined proposal for making autonomous-driving safety arguments more observable, not as proof that the proposed monitors can independently prevent dangerous behavior.
Subject of Research: Runtime monitoring for SOTIF-oriented safety assurance of AI-based autonomous-driving perception systems
Article Title: Addressing SOTIF with a runtime monitor ensemble for AI-based perception systems
Article References: Schaller, F., Ehlers, R., Aslam, I., Deshpande, A., Gräfe, R., Guedri, W., Habib, N., Maslov, N., Rausch, A., Qutub, S. S., & Zhang, M. (2026). Addressing SOTIF with a runtime monitor ensemble for AI-based perception systems. Discover Artificial Intelligence, 6(1), Article 1172. https://doi.org/10.1007/s44163-026-02186-z
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02186-z
Keywords: autonomous driving, AI perception, runtime monitoring, SOTIF, ISO 21448, residual risk, neural networks, safety assurance, sensor redundancy, Addressing, runtime, monitor
News Source: Denise Maddox. (October 26, 2026). Runtime monitor ensemble proposed for autonomous-driving perception safety. Scienmag.