Study Finds AI Chatbots Fail Reading Benchmarks for Melanoma Education
A cross-sectional study evaluating four major artificial intelligence chatbots found that while diagnostic accuracy was high, none produced melanoma guidance ...
A cross-sectional study evaluating four major artificial intelligence chatbots found that while diagnostic accuracy was high, none produced melanoma guidance ...
A prospective benchmark of four large language models generating pediatric neurology educational content revealed significant performance variation, safety concerns, and ...
A cross-sectional study evaluating six artificial intelligence chatbots found that none met recommended sixth-grade reading benchmarks for epididymitis information, while ...
A controlled evaluation of three large language models found that artificial intelligence systems were more than twice as likely to ...
A comparative study in BMC Pediatrics found that artificial intelligence chatbots fail sixth-grade readability benchmarks and exhibit limited source transparency ...
A study evaluating four artificial intelligence models found that classification fidelity for endodontic exam questions varied significantly across educational taxonomies.
A study evaluating AI-assisted HPLC method development for ranolazine analysis found that artificial intelligence achieved 72.9 percent prediction accuracy but ...
A new study finds that local Chinese AI models significantly outperform global platforms in early childhood education tasks requiring cultural ...
While the models produced well-organized documents that identified key clinical and social dimensions, the study found that high analytical scores ...
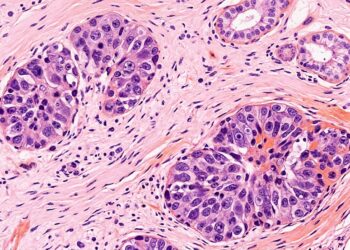
A paired concordance study found that three commercial multimodal AI models showed systematic, model-specific errors in breast cancer pathology reporting ...
Vision–language models read region names from multiple sequence alignment images accurately but fail badly at defining residue boundaries, where a ...
Researchers show that GPT-5 and Gemini can extract and classify policy framing quotes from German news articles with F1-scores near ...
Researchers developed AMHART, a clinician-informed tool that found chatbot responses covered more guideline-informed criteria for anxiety than depression and for ...
A single-center study found multimodal AI models could draft image-dependent neurosurgery exam questions and grade resident responses with about 90% ...
A new study in Archives of Gynecology and Obstetrics finds that ChatGPT, Grok, and Gemini produced expert-rated accurate, high-quality, and ...
Large language models performed well on written early gastric cancer questions but showed limited and inconsistent ability to recognise the ...
A survey of 56 mechanical engineering students found that reported generative AI users saw the technology as most helpful for ...
An expert-rated analysis of 900 responses from ChatGPT, Gemini and Claude found that 88.9% were correct or mostly correct, while ...
A standardized evaluation of 56 chatbot responses to 14 real search queries about high-intensity interval training found that Perplexity received ...
In an expert evaluation of 60 patient-facing dental radiology answers, a reasoning-enabled ChatGPT configuration received the strongest ratings for accuracy, ...