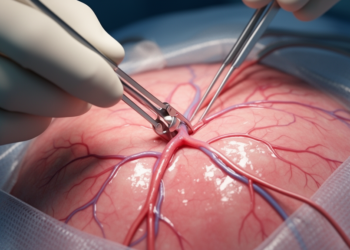
Single Clip Technique for Moyamoya Bypass Surgery
A new study in Acta Neurochirurgica details a surgical technique using a single curved microclip to facilitate superficial temporal artery ...
A new study in Acta Neurochirurgica details a surgical technique using a single curved microclip to facilitate superficial temporal artery ...
Researchers have developed three interconnected CLIP-based protocols to characterize proximal RNA-dependent protein assemblies in living cells.
A new supervised cross-modal hashing method called SEGRH converts label co-occurrence into continuous semantic association scores and reports state-of-the-art retrieval ...
A new few-shot learning framework called scCAPReSE detects large-scale genomic rearrangements in single-cell Hi-C data using pre-trained image model representations, ...
A new study shows that a frozen CLIP vision-language model with lightweight adapters can improve human activity recognition in low-light ...
A new framework called TRRN re-indexes and filters web-retrieved images against few-shot class anchors, lifting accuracy across six benchmark settings ...
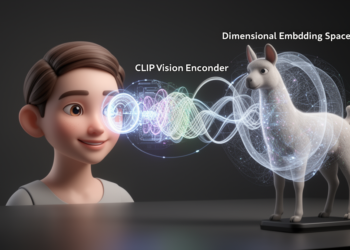
A LLaMA-CLIP cross-attention system improved multimodal matching, intention recognition and personalization in benchmark tests while recording batch-size-one inference latency of ...
A DETR-CLIP study of 5,000 children’s drawings reported stronger detection and semantic performance than several baselines, with lower results on ...
Researchers have unveiled MiRAGE, a parameter-efficient AI framework that adapts its computational depth to each satellite image and uses CLIP ...
A new multi-modal AI method pairs structured text descriptions generated by a large language model with image analysis to identify ...
A new taxonomy-aware segmentation framework links every diseased pixel to both its host crop and its disease, delivering state-of-the-art results ...
A new multimodal AI framework fuses RGB images, segmentation masks, depth maps, and text prompts to estimate robotic gripper pressure ...
Researchers fused the SAM and CLIP vision foundation models into an AI pipeline that segments grapevine powdery mildew pixel by ...
Researchers in India show that training only a 2.4-million-parameter projection module on top of frozen CLIP encoders lifts fashion image-to-text ...
Researchers have unveiled a diffusion-based framework that fuses text, reference images and sketches with sample-adaptive weighting and iterative user feedback, ...
Researchers have introduced HGA-Net, a hypergraph-based adapter that connects related examples within each mini-batch and achieves near-perfect fine-grained recognition with ...