Commonly applied distance-based spatial interpolation techniques can introduce dramatic distortions into the detection and characterization of extreme heat waves, even while demonstrating strong predictive accuracy on standard statistical benchmarks. In a comprehensive investigation published in the Bulletin of Atmospheric Science and Technology, researchers Fabiano Fernandes Bargos, Maurício Lamano Ferreira, and Danúbia Caporusso Bargos examined how spatial estimation methods reshape temperature time series and derived climate indicators across the state of São Paulo, Brazil. Evaluating hourly meteorological records from 2021 through 2025 within a rigorous leave-one-out cross-validation framework, the authors revealed that models achieving low root-mean-square errors can simultaneously alter temperature variability and suppress consecutive threshold exceedances. While spatial smoothing preserved overall central tendencies, it consistently truncated distributional tails, causing derived heat-wave indicators to diverge substantially between alternative interpolation choices. The findings demonstrate that relying exclusively on traditional error metrics masks critical distortions in climate extremes, presenting substantial implications for data-sparse regions where environmental policy and municipal adaptation planning depend on gridded temperature surfaces.
Near-surface air temperature governs atmospheric circulation, terrestrial surface energy balance, agricultural productivity, and ecological stability, serving as an indispensable input for municipal climate services, infrastructure management, and public health risk assessments. However, direct atmospheric monitoring relies on discrete weather stations that remain unevenly distributed across physical landscapes due to historical infrastructure development, logistical hurdles, and complex regional topography. The state of São Paulo encompasses approximately 248,000 square kilometers in southeastern Brazil, extending between latitudes 19 degrees south and 25 degrees south and longitudes 44 degrees west and 53 degrees west. The territory features remarkable physiographic diversity, transitioning from sea-level coastal plains across steep escarpments such as the Serra do Mar to extensive interior plateaus and mountain ranges exceeding 2,700 meters in the Serra da Mantiqueira. Under tropical and subtropical regimes governed by the South American Monsoon System, sharp elevation gradients and proximity to the Atlantic Ocean generate intense localized thermal contrasts, making the state an ideal testing ground for evaluating how spatial interpolation choices propagate into administrative-scale climate metrics.
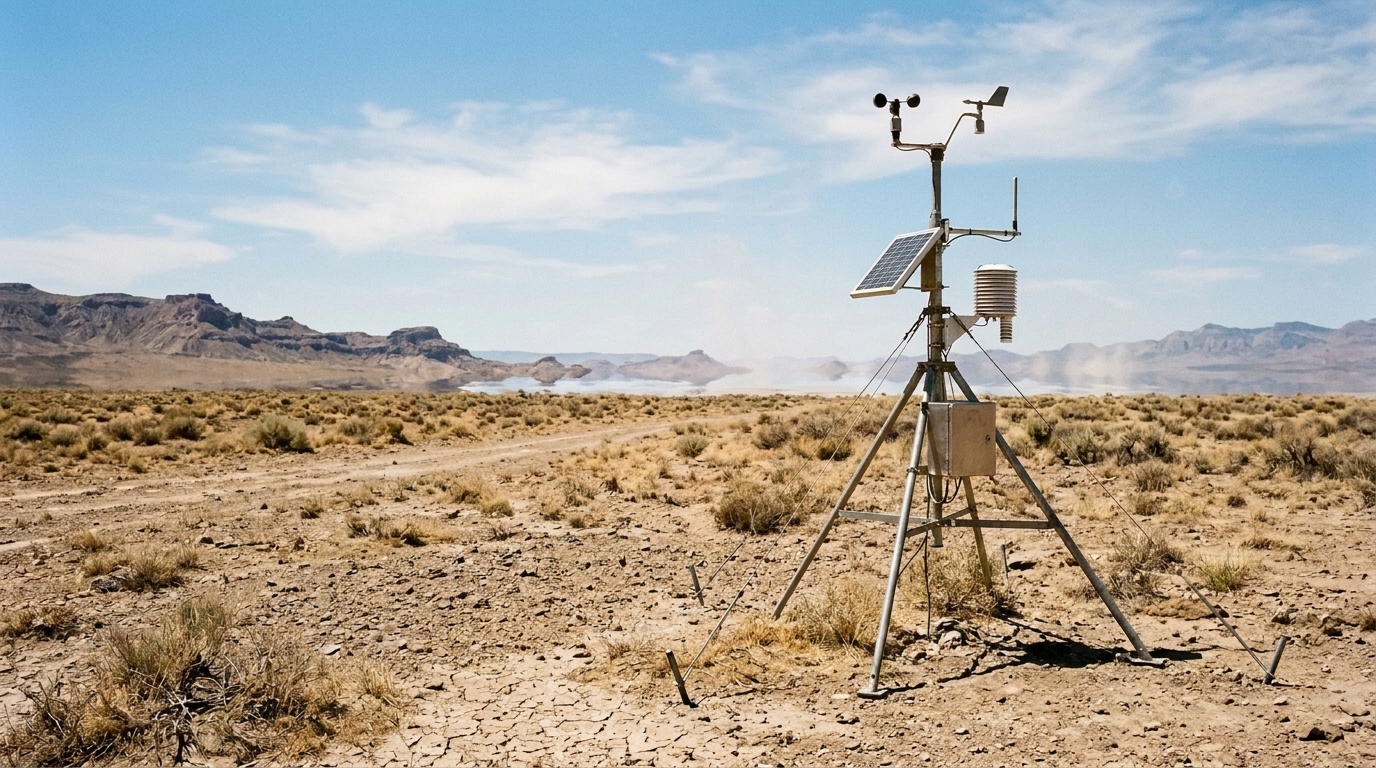
To capture these complex climatic conditions, the authors processed hourly meteorological observations collected by the Brazilian National Institute of Meteorology across its automated weather station network between January 2021 and December 2025. Recognizing that boundary constraints often generate spatial distortions during estimation, the research team established an extensive 250-kilometer buffer zone surrounding São Paulo state, assembling a comprehensive dataset of 160 monitoring stations, of which 42 reside directly within state borders. Station-level records revealed pronounced operational instability and heterogeneous data availability over the five-year study period. While certain monitoring installations maintained consistent observations, multiple stations experienced prolonged equipment interruptions where annual missing records surpassed 50 percent, and a few locations suffered near-total operational collapse in specific years. Because the network of operational stations shifted dynamically from one hour to the next, spatial interpolation algorithms had to operate under continuously fluctuating neighborhood configurations, reflecting the realistic data-sparse challenges confronting climate risk assessments in developing and topographically complex territories.
The investigation evaluated spatial prediction using a leave-one-out cross-validation methodology, systematically withholding each station in turn to estimate its hourly temperature from neighboring observations before assessing discrepancy metrics against measured ground conditions. The researchers established a Nearest Neighbor approach as an operational baseline and tested multiple configurations of Inverse Distance Weighting, systematically varying the search radius across 150, 200, and 250 kilometers alongside distance-decay exponents of alpha equals two and alpha equals three. Preliminary evaluations demonstrated that search distances under 150 kilometers frequently failed to capture any active reporting stations during operational interruptions, requiring wider radii to guarantee continuous temporal coverage. Across all cross-validation trials, Inverse Distance Weighting consistently outperformed Nearest Neighbor, which registered the highest overall error of 2.652 degrees Celsius and the lowest explanatory coefficient of determination at 0.778. The best-performing configuration combined a 250-kilometer radius with an exponent of two, yielding an average root-mean-square error of 1.973 degrees Celsius, an explanatory power of 0.877, and minimal systematic bias below 0.17 degrees Celsius.
To uncover structured geographic patterns in model performance that global statistics might obscure, the authors integrated unsupervised machine learning into their validation pipeline, applying Principal Component Analysis and Density-Based Spatial Clustering of Applications with Noise. Standardizing performance metrics alongside geographic coordinates and station altitudes, the first three principal components retained 82.0 percent of total variance, with individual components explaining 38.3 percent, 29.3 percent, and 14.4 percent respectively. Subsequent spatial clustering delineated two distinct regimes of satisfactory predictive performance alongside a dispersed noise cluster displaying significantly elevated errors, erratic explanatory power, and pronounced negative biases under Kruskal-Wallis testing. Stations within the noise cluster were scattered across diverse geographic settings spanning extreme low and high elevations rather than clustering along continuous terrain gradients. This spatial distribution underscored that distance-weighted averaging struggles in localized pockets where complex topography, coastal interactions, and valley drainage mechanisms sever the correlation between horizontal Euclidean distance and microclimatic similarity.
Following station-level validation, the research team projected hourly temperature fields onto the geographic centroids of all 645 municipalities in São Paulo state to replicate the spatial scale where municipal governance and climate vulnerability assessments occur. Comparing daily maximum temperatures between Inverse Distance Weighting and Nearest Neighbor, the team calculated summary difference statistics and combined them with centroid coordinates, elevation, and distance to the closest station for a second unsupervised clustering pipeline. Using Density-Based Spatial Clustering with an epsilon parameter of 0.651 and a minimum sample threshold of 18 points, the municipal classification mirrored the station-scale findings. Municipalities designated as noise clustered predominantly in zones characterized by extreme elevations or extended geographic distances from operational monitoring facilities, where methodological disagreement between the two interpolation techniques peaked. Conversely, municipalities across homogeneous northern plateaus formed cohesive clusters demonstrating high consistency, confirming that interpolation uncertainty is not randomly distributed across space but structured by station network geometry and physiographic heterogeneity.
Aggregation across intermediate geographic regions defined by the Brazilian Institute of Geography and Statistics highlighted how spatial smoothing reshapes underlying temperature distributions. Across all intermediate regions, Inverse Distance Weighting reproduced regional mean and maximum temperatures with high fidelity, keeping discrepancies in regional means generally below one degree Celsius. However, an examination of distributional tails revealed severe suppression of localized variability, most acutely manifested in minimum temperatures. In São José dos Campos, situated within topographically rugged terrain between mountain escarpments, the absolute minimum of daily maximums rose from 9.80 degrees Celsius at weather stations to 16.00 degrees Celsius in interpolated municipality series, while minimum mean temperatures surged from 3.57 degrees Celsius to 8.00 degrees Celsius. Furthermore, observed absolute minimum temperatures of minus 2.50 degrees Celsius were attenuated to minus 1.78 degrees Celsius, while Campinas exhibited notable negative offsets where mean minimum temperatures dropped from 15.46 degrees Celsius observed to 13.23 degrees Celsius interpolated.
The consequences of this distributional smoothing became magnified when evaluating downstream climate indicators, specifically threshold-dependent heat-wave events defined as consecutive days where daily maximum temperatures exceeded 35 degrees Celsius. To isolate the methodological effect of the interpolation algorithms, the authors enforced a uniform 35-degree threshold across all municipalities and datasets rather than deriving separate local percentiles. Because heat-wave classification hinges on both an absolute temperature threshold and uninterrupted temporal persistence, minor daily temperature deviations triggered a nonlinear amplification mechanism. A subtle interpolation error of fractions of a degree on a single afternoon could suppress an estimated peak below the critical 35-degree boundary, instantly fracturing an extended multi-day sequence. Consequently, even though Inverse Distance Weighting showed small average errors in maximum temperature, its continuous spatial averaging systematically lowered extreme values during intense heat episodes, thereby erasing the temporal persistence required to satisfy climatological heat-wave definitions.
Quantitative comparisons revealed dramatic divergences in detected heat-wave occurrence and cumulative duration between the two spatial approaches across the 2021 to 2025 period. While discrepancies were evident for short three-day and four-day events, differences expanded dramatically for severe heat waves lasting five or more consecutive days, where the Nearest Neighbor baseline identified two to three times more events than Inverse Distance Weighting. Across cumulative metrics, municipalities such as Pereira Barreto and Ilha Solteira exhibited staggering differences reaching up to 199 cumulative heat-wave days over the five-year record, with even the smallest municipal discrepancy in the sample exceeding 120 days. Spatial mapping indicated that these indicator discrepancies clustered heavily within the western sectors of the state, including Araçatuba, Presidente Prudente, and São José do Rio Preto. In these warmer interior climates, ambient temperatures frequently hover near the 35-degree threshold, creating an environment where modest algorithmic smoothing produces massive, disproportionate drops in detected event duration.
The authors emphasized that these findings must be interpreted within specific methodological boundaries, as direct continuous temperature measurements at municipal centroids do not exist, meaning the discrepancies represent methodological sensitivities rather than direct proof of underlying climatological realities. Furthermore, using municipal geometric centroids abstracts away internal topographic complexity, particularly across extensive or mountainous jurisdictions in eastern São Paulo where localized elevation gradients dictate microclimates. The study focused deliberately on distance-based algorithms to benchmark common operational practices under data sparsity, noting that more sophisticated geostatistical approaches, such as elevation-informed kriging, spline models, or quantile kriging, could better preserve distributional tails and provide explicit predictive uncertainty bounds. Ultimately, the investigation demonstrates that spatial interpolation is not an innocuous preprocessing chore but an active methodological determinant of climate exposure metrics. Relying on average error metrics alone risks misguiding municipal adaptation investments, infrastructure resilience planning, and heat-health warning systems across data-sparse regions worldwide.
Subject of Research: Impact of spatial temperature interpolation methods on extreme heat-wave detection in data-sparse regions
Article Title: Spatial interpolation alters heat-wave detection despite small temperature errors in data-sparse regions
Article References: Bargos, F. F., Ferreira, M. L., & Bargos, D. C. (2026). Spatial interpolation alters heat-wave detection despite small temperature errors in data-sparse regions. Bulletin of Atmospheric Science and Technology, 7(1), Article 34. https://doi.org/10.1007/s42865-026-00155-z
Image Credits: AI Generated
DOI: 10.1007/s42865-026-00155-z
Keywords: spatial interpolation, heat wave detection, inverse distance weighting, nearest neighbor, temperature variability, climate indicators, São Paulo, meteorological stations, leave-one-out cross-validation, climate extremes, DBSCAN clustering, principal component analysis, root mean square error, threshold exceedance, data-sparse regions, atmospheric science, climate risk assessment, municipal climate exposure
News Source: Denise Maddox. (November 22, 2026). Spatial Temperature Interpolation Distorts Heat Wave Detection Across Data Sparse Regions. Scienmag.