Computer vision researchers Hao Pan and Senlin Jiang have introduced a unified vision foundation model architecture that couples a reversible visual byte-pair encoding tokenizer with scale-aware sparse expert routing, demonstrating notable performance gains across image recognition, object detection, instance segmentation, semantic parsing, and promptable mask transfer. Published in Discover Artificial Intelligence, the study details the design of MoE-HBPE-VFM, an encoder framework engineered to process visual evidence across multiple levels of spatial and semantic detail without requiring customized backbones for each downstream task. In controlled multi-task benchmarks, the full model achieved an overall unified score of 90.8, outperforming the most effective dense baseline by 2.2 points. Rather than relying on separate specialized models or destructive token pruning, the system systematically organizes image data into a hierarchical visual vocabulary that preserves complete parent-child spatial linkages. The findings indicate that unifying visual granularity through an adaptive, reversible vocabulary and dynamic conditional computation offers a mathematically sound pathway toward versatile multi-task perception systems.
The design of general-purpose vision models has long faced a structural conflict between broad context modeling and fine spatial resolution. Standard architectures typically rely on rigid patch grids, task-specific decoders, or irreversible token pruning to restrict computation. However, coarse representations adequate for image-level classification often lack the precision required to delineate thin object boundaries, while evaluating dense token grids across all transformer layers creates severe computational redundancy in uniform regions such as skies or smooth surfaces. Furthermore, conventional token-merging methods permanently discard merged elements, leaving downstream prediction heads unable to recover lost spatial evidence. Existing systems also isolate token hierarchy from conditional expert routing, treating structural sparsification and parameter expansion as disjoint mechanisms. The authors sought to resolve these limitations by constructing a unified encoder in which hierarchical token grouping explicitly stores child supports, supplying a scale-aware token stream that guides conditional sparse experts across varied spatial and semantic demands.
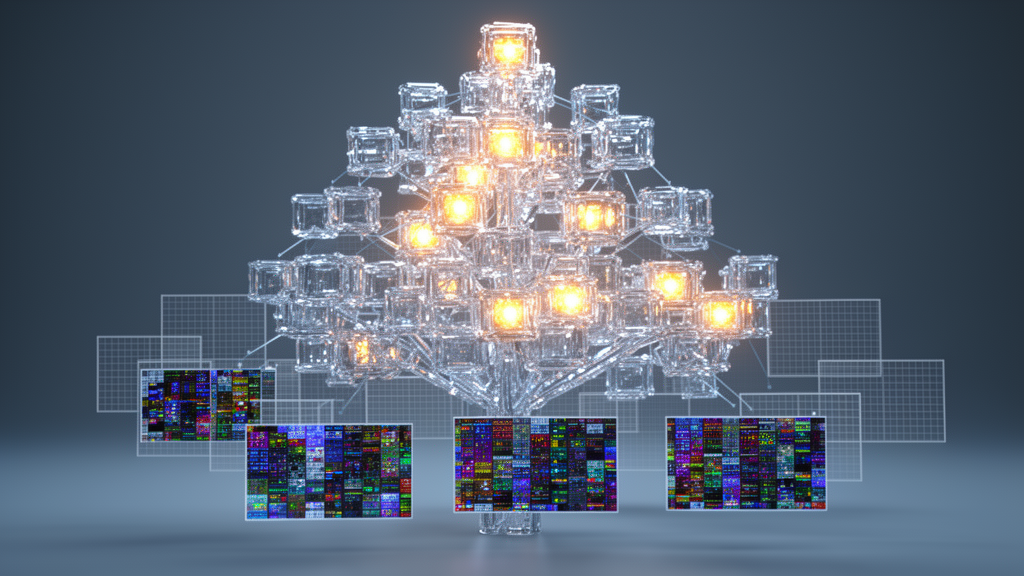
To build this visual vocabulary, the researchers adapted byte-pair encoding from text processing to formulate a hierarchical visual tokenizer. An input image is converted into an ordered sequence of patch tokens, each retaining an explicit spatial support record. The tokenizer iteratively groups adjacent tokens into higher-level visual units representing parts, objects, and scenes across up to four hierarchy levels. Merging candidate selection is governed by a mathematically defined gain function that combines three elements: empirical co-occurrence frequency, normalized feature affinity, and a spatial compactness penalty. Regulated by an affinity temperature that anneals during training, the gain formula ensures that candidate pairs must demonstrate both strong visual similarity and physical proximity. This geometric constraint prevents distant regions from merging solely due to shared semantic attributes, thereby protecting delicate boundaries and small objects. By operating in an input-conditional manner, the tokenizer maintains reliable grouping behavior even when input corruptions degrade statistical priors, relying on real-time affinity and spatial proximity to prevent catastrophic early merging.
A fundamental property distinguishing this tokenizer from standard pooling techniques is the strict reversibility of its hierarchical merge tree. Whenever adjacent visual tokens are merged into a parent entity, the system explicitly logs the parent-child relationships and preserves spatial support identifiers rather than deleting fine-grained coordinates. This architecture underpins Proposition 1 in the study, which states that because the merge tree preserves all child supports and expert modules operate on tokens retaining support identifiers, every dense prediction can be traced back to its originating patch supports. In dense prediction tasks such as instance segmentation and promptable mask transfer, task decoders utilize these parent-child support records to expand coarse representations back into fine spatial details. This structural design enables the visual encoder to use compact tokens for computationally efficient context modeling while guaranteeing that dense prediction heads can accurately reconstruct subtle edge contours and small object boundaries, establishing a balanced foundation for multi-granularity visual interpretation.
Following hierarchical tokenization, active visual tokens are routed to specialized visual experts within a mixture-of-experts contextual encoder. Instead of relying solely on raw token appearance, the router determines expert assignments using a composite representation that explicitly incorporates hierarchical position, spatial footprint, and contextual neighborhood. The router input concatenates the token’s contextual feature with learnable embeddings for its hierarchy level, its spatial support area in pixels, and a neighborhood context vector computed via arithmetic mean pooling over adjacent tokens at the same hierarchy level. The model maintains eight stored visual experts, each dedicated to distinct visual evidence: surface texture, boundaries, object interiors, scene backgrounds, and rare categories. By default, the router directs each token to its top two experts, activating specialized parameter subspaces while keeping per-token computational costs low. Empirical evaluations confirmed that this scale-aware mechanism generates a pronounced division of labor across experts, preventing redundant computations in uniform regions and dedicating focused capacity to visually complex boundaries.
To prevent sparse routing from degenerating into trivial states where only a few experts handle the entire workload, the authors integrated three structural routing constraints. A dual load-balancing strategy combines an auxiliary entropy-maximizing regularization term with a differentiable load-balancing loss operating on soft assignment probabilities, guiding the router toward balanced utilization without enforcing artificial equality. To prevent computational bottlenecks during processing, each expert is subject to a soft capacity threshold governed by a capacity factor of 1.2, which masks overloaded assignments during forward passes and redirects surplus tokens to secondary expert candidates. Furthermore, a routing stability constraint penalizes abrupt assignment fluctuations across consecutive training updates by minimizing the Kullback-Leibler divergence between routing distributions of matched spatial tokens. Hyperparameter tuning on validation data established balancing coefficients of 0.01 for entropy and load terms alongside 0.001 for routing stability, ensuring consistent expert specialization and stable gradient propagation throughout training.
Training the architecture end-to-end requires harmonizing multiple prediction losses with structural constraints. The primary supervised objective combines classification loss, bounding box regression loss, instance mask loss, semantic segmentation loss, and promptable mask transfer loss. To coordinate these diverse targets without destructive interference, the overall training loss adds structural regularization terms for hierarchy compactness, expert load balancing, and cross-scale prediction consistency. The cross-scale agreement regularizer specifically penalizes discrepancies between fine-scale predictions and spatially aligned coarse-scale predictions across overlapping spatial supports, employing a squared Euclidean norm penalty. Rather than forcing identical representations across all scales, this consistency loss operates only where hierarchy levels share identical spatial footprints, preserving legitimate differences between localized edges and global context while enforcing hierarchical coherence. This joint optimization framework prevents uncontrolled token merging, suppresses expert collapse, and allows a single visual representation to serve diverse downstream heads without task-specific encoder re-training.
The evaluation protocol examined the architecture across eight public vision datasets spanning general recognition, dense localization, long-tail segmentation, and robustness. Testing included ImageNet-1K for classification, MS COCO 2017 for detection and instance segmentation, ADE20K for dense parsing, LVIS for rare-category masks, Open Images V7 for open-vocabulary localization, SA-1B for promptable mask transfer, ImageNet-C for corruption robustness, and ObjectNet for viewpoint and background shifts. Experiments ran on 32 NVIDIA A100 GPUs using distributed data-parallel training with the AdamW optimizer. To ensure rigorous comparisons despite baselines having differing pretraining corpora and architectures, the authors implemented a standardized evaluation protocol. All competing models were evaluated at a uniform resolution of 1024 by 1024 pixels, equipped with standardized task heads of identical capacity when lacking native outputs, and fine-tuned for 80 epochs using identical learning rates, weight decay, and optimization schedules, ensuring observed differences reflected architectural design rather than mismatched optimization or head configurations.
Experimental comparisons demonstrated that MoE-HBPE-VFM achieved the highest performance across all dense and promptable benchmarks. While improvements in ImageNet-1K top-one classification were modest compared to heavily pretrained models like Florence-2-base, the architecture established clear advantages in COCO mask average precision, LVIS rare average precision, ADE20K mean Intersection over Union, and SA-1B zero-shot prompt transfer. Component ablations confirmed that sparse experts improve representational capacity, hierarchical BPE substantially boosts dense parsing metrics, load balancing prevents rare-class degradation, and cross-scale consistency maintains multi-level alignment. A dedicated hyperparameter analysis across stored experts (ranging from four to twelve) and active experts (ranging from one to four) established that eight stored experts and two active experts per token formed the optimal configuration, achieving a mean unified score of 90.85 with a standard deviation of 0.14 across five random seeds, significantly outperforming alternative expert settings in pairwise statistical testing.
Efficiency and robustness analyses underscored the practical trade-offs governing the architecture. Measured on an NVIDIA A100 GPU under a standardized single-image protocol, MoE-HBPE-VFM achieved a single-image latency of 31.2 milliseconds with 16.3 billion active FLOPs, executing faster than heavier foundation models like DINOv2-B and Florence-2-base, yet slower than compact backbones like ConvNeXt V2-B and Hiera-B, confirming a favorable accuracy-computation trade-off rather than a universal wall-clock speed advantage. In robustness stress tests, the model exhibited resilience against severe distribution shifts, achieving a 5.1-point advantage on ImageNet-C and a 3.2-point gain on ObjectNet, while improving small-object and thin-structure accuracy over Semantic-SAM. Nonetheless, failure analyses identified vulnerabilities under dense background clutter, minute objects, transparent boundaries, and ambiguous prompts where premature token merging occurred. Acknowledging limitations in visual-only conditioning and controlled academic pretraining, the authors highlighted uncertainty-aware merge thresholds and multi-modal prompt integration as vital avenues for extending reversible token hierarchies toward large-scale foundation systems.
Subject of Research: Hierarchical visual tokenization and sparse expert foundation models for unified computer vision
Article Title: Mixture-of-experts vision foundation model with hierarchical BPE tokenization for unified multi-granularity perception
Article References: Pan, H., & Jiang, S. (2026). Mixture-of-experts vision foundation model with hierarchical BPE tokenization for unified multi-granularity perception. Discover Artificial Intelligence, 6(1), Article 1889. https://doi.org/10.1007/s44163-026-02603-3
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02603-3
Keywords: computer vision, vision foundation models, hierarchical tokenization, byte-pair encoding, mixture of experts, sparse routing, multi-granularity perception, instance segmentation, semantic parsing, promptable mask transfer, object detection, load balancing, cross-scale consistency, spatial support, ImageNet, MS COCO, ADE20K
News Source: Denise Maddox. (November 19, 2026). Reversible Visual Token Hierarchy and Sparse Experts Enhance Multi-Granularity Image Perception. Scienmag.