A computational study of six real-world sentiment-analysis datasets found that two newly developed nearest-neighbor classifiers improved on standard KNN when training data were limited, sparse and high-dimensional. Relative to standard KNN, the Orthogonal Projection-based Iterative KNN (OPIKNN) and Fuzzy OPIKNN (FOPIKNN) classifiers improved average classification accuracy by 5.8% and 7.3%, respectively, while their average macro F1-scores increased by 8.5% and 9.8%.
The research, published in Discover Artificial Intelligence on October 12, 2026, evaluated OPIKNN and FOPIKNN against six KNN-based variants and four other machine-learning baselines. The six sentiment datasets covered hotel reviews, gift-card reviews, Yelp restaurant reviews, Apple tweets, mental-health reviews and women’s clothing reviews. Five came from Kaggle and one from an Amazon product-review repository collected in 2023.
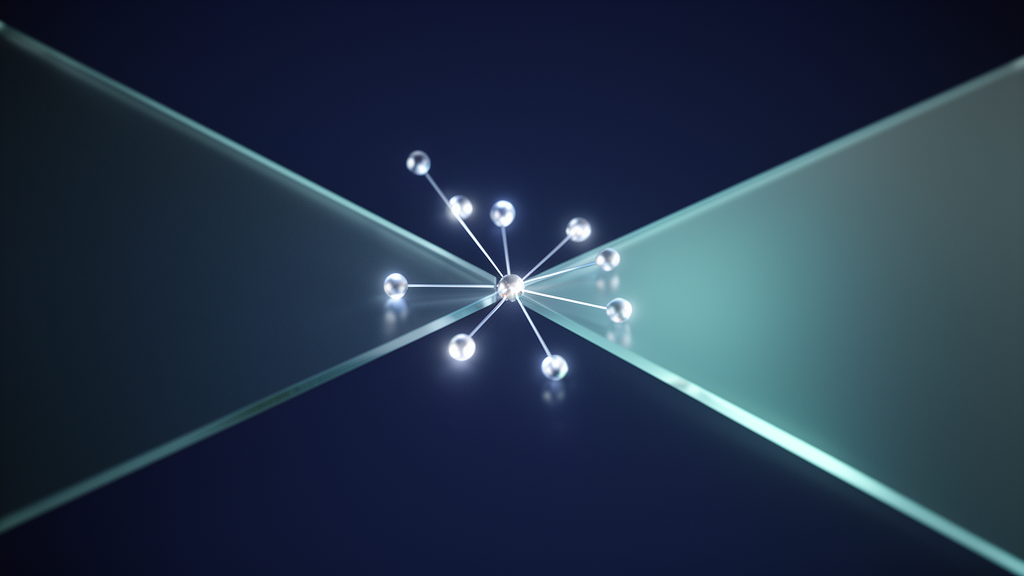
OPIKNN changes the basic decision made by KNN. Conventional KNN assigns an unseen sample according to the majority label among its nearest training examples. OPIKNN instead constructs a class-specific pseudo-nearest neighbor for each sentiment category and assigns the unseen sample to the class whose representative is closest. It begins with class centroids, iteratively identifies extreme-nearest neighbors within each class, and updates the representative by orthogonally projecting the unseen sample onto the segment between the current representative and the newly selected extreme neighbor.
The projection procedure is supported by geometric results concerning convex hulls, extreme points and orthogonal projection. At each iteration, the distance between the unseen sample and the evolving pseudo-nearest neighbor is non-increasing and bounded below by zero, which the authors use to establish theoretical convergence. After k iterations, the class with the closest final representative receives the prediction. The parameter k controls the number of extreme neighbors considered, the number of projection steps and the precision of distance refinement.
FOPIKNN adds a fuzzy refinement stage intended to address uncertainty and reduce the effects of noise and outliers. It calculates class membership values from distances to class centroids and within-class dispersion, then uses a reliability weight to move each pseudo-nearest neighbor toward its class centroid. The displacement is governed by both the membership value and the class’s dispersion; the model therefore does not apply the same shift to every class or dataset.
For the experiments, raw reviews and tweets were converted to lowercase, stripped of non-alphanumeric characters, split into whitespace-delimited unigrams without stop-word filtering, and represented using term frequency–inverse document frequency features. Each dataset was divided into training and testing sets at an 80/20 ratio. Hyperparameters were selected through grid search with repeated five-fold cross-validation using three repetitions on the training data, and the full procedure was repeated ten times. Results were reported as mean plus or minus standard deviation, using accuracy and macro-averaged F1-score.
FOPIKNN recorded the highest classification accuracy on five of the six datasets: 93.50% for hotel reviews, 89.30% for gift-card reviews, 83.67% for Apple tweets, 85.50% for mental-health reviews and 87.50% for women’s clothing reviews. OPIKNN achieved the highest accuracy on Yelp restaurant reviews, at 85.50%. FOPIKNN’s accuracy gains over standard KNN ranged from 2.50 to 13.67 percentage points across the six datasets. In macro F1-score, FOPIKNN led on four datasets, while OPIKNN led on Yelp restaurant reviews.
Non-parametric statistical analysis found substantial differences among the classifiers across the six datasets. For accuracy, the Friedman statistic was 41.81 with a p-value of 1.75 × 10⁻⁵; for macro F1-score, it was 38.79 with a p-value of 5.74 × 10⁻⁵. In the Nemenyi post-hoc analysis, FOPIKNN was significantly better than most KNN variants and Random Forest, but not significantly different from Linear SVM, Nearest Shrunken Centroids or Gaussian Naïve Bayes. OPIKNN showed a statistically significant improvement only over Random Forest.
A separate sensitivity analysis tested k values of 1, 3, 5, 8, 12 and 15. OPIKNN and FOPIKNN generally maintained stable accuracy and macro F1-scores across this range, while several KNN baselines varied more. An ablation study also found that the complete FOPIKNN model had the highest accuracy on four of the six datasets when either centroid-based initialization or extreme-neighbor removal was removed. The evidence is limited to the selected text-classification datasets, preprocessing pipeline and baseline models; statistical comparisons were also affected by the small number of datasets. The authors did not compare the methods with transfer learning or contextualized representations such as BERT, which they identified as subjects for future work.
Subject of Research: Evaluation of projection-based and fuzzy nearest-neighbor classifiers for sentiment analysis on small datasets
Article Title: An orthogonal projection-based iterative KNN classifier for sentiment analysis on small datasets
Article References: El Mrabti, S., Hjouji, A., El-Mekkaoui, J., Hachmoud, A., & Lazzar, M. (2026). An orthogonal projection-based iterative KNN classifier for sentiment analysis on small datasets. Discover Artificial Intelligence, 6(1), Article 1443. https://doi.org/10.1007/s44163-026-02457-9
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02457-9
Keywords: sentiment analysis, nearest-neighbor classification, small datasets, high-dimensional text, fuzzy classification, orthogonal projection, machine learning, macro F1-score, orthogonal, projection-based, iterative, classifier
News Source: Denise Maddox. (October 20, 2026). Projection-based KNN variants improve sentiment classification on small datasets. Scienmag.