• HOME
  • NEWS
  • EXPLORE
    • CAREER
      • Companies
      • Jobs
    • EVENTS
    • iGEM
      • News
      • Team
    • PHOTOS
    • VIDEO
    • WIKI
  • BLOG
  • COMMUNITY
    • FACEBOOK
    • INSTAGRAM
    • TWITTER
Sunday, November 8, 2026
BIOENGINEER.ORG
No Result
View All Result
  • Login
  • HOME
  • NEWS
  • EXPLORE
    • CAREER
      • Companies
      • Jobs
        • Lecturer
        • PhD Studentship
        • Postdoc
        • Research Assistant
    • EVENTS
    • iGEM
      • News
      • Team
    • PHOTOS
    • VIDEO
    • WIKI
  • BLOG
  • COMMUNITY
    • FACEBOOK
    • INSTAGRAM
    • TWITTER
  • HOME
  • NEWS
  • EXPLORE
    • CAREER
      • Companies
      • Jobs
        • Lecturer
        • PhD Studentship
        • Postdoc
        • Research Assistant
    • EVENTS
    • iGEM
      • News
      • Team
    • PHOTOS
    • VIDEO
    • WIKI
  • BLOG
  • COMMUNITY
    • FACEBOOK
    • INSTAGRAM
    • TWITTER
No Result
View All Result
Bioengineer.org
No Result
View All Result
Home NEWS Science News Technology

New Algorithm Keeps Offline RL Agents Safe

by
November 8, 2026
in Technology
Reading Time: 2 mins read
0
New Algorithm Keeps Offline RL Agents Safe

New Algorithm Keeps Offline RL Agents Safe

Share on FacebookShare on TwitterShare on LinkedinShare on RedditShare on Telegram

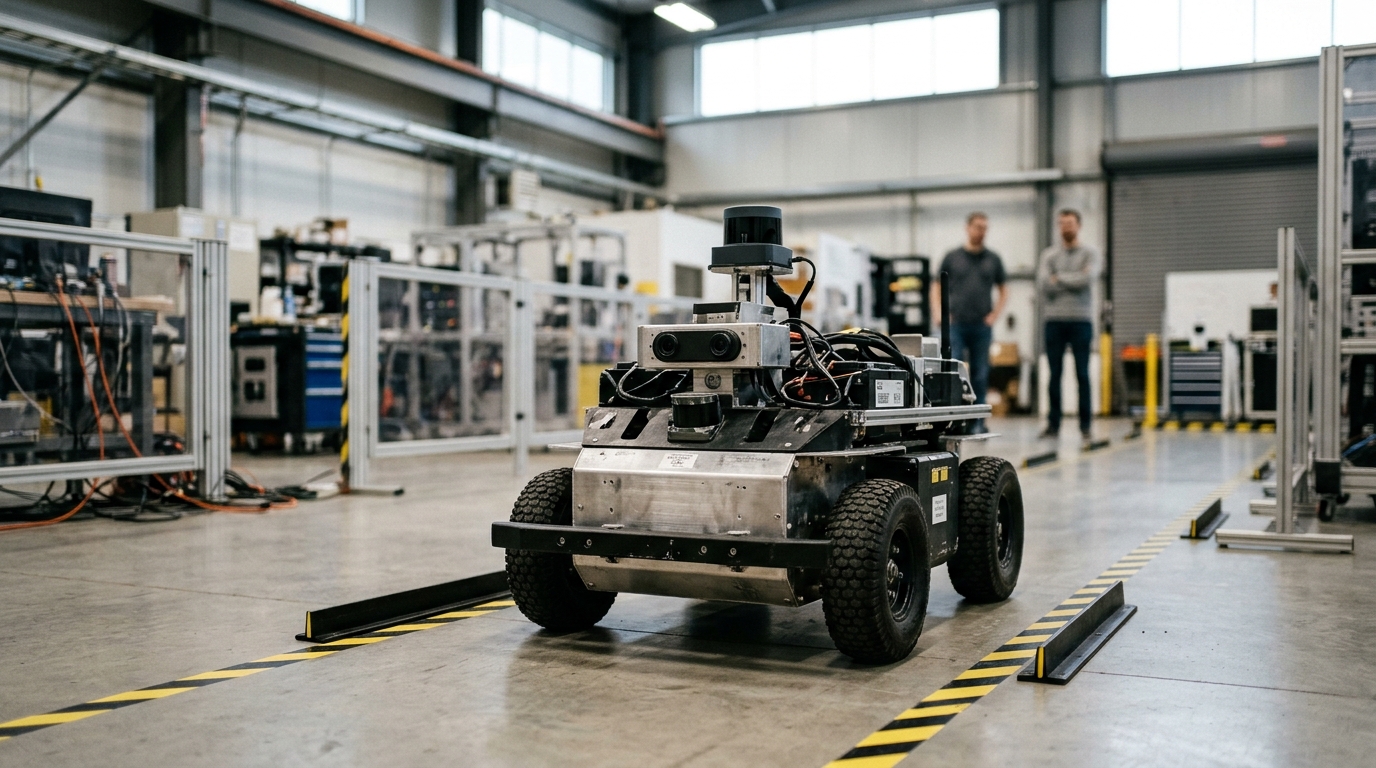
Researchers led by Wenzhang Liu have developed a new method called ASIR, which stands for Addressing out-of-distribution States for offline reinforcement learning with interference robustness. The study, published in the journal Applied Intelligence in November 2026, addresses a critical limitation in offline reinforcement learning known as the out-of-distribution problem. This issue significantly restricts the deployment of such agents in real-world scenarios because they can struggle when encountering states that were not present in their training data. The authors argue that a key aspect of this challenge is the tendency of an agent to fall into a trajectory of successive unfamiliar states once it enters an unknown region, leading to severe performance degradation.

The core innovation of the ASIR method is the introduction of a transition-constrained policy. This policy is enforced through a regularization term derived from an inverse dynamics model, or IDM. The IDM is pre-trained on the offline dataset to capture the underlying dynamics of valid state transitions. By encouraging the policy to prefer actions that lead to familiar and predictable next states, the method aims to keep the agent within the data manifold and away from out-of-distribution regions. Theoretically, the authors state that this approach not only corrects for out-of-distribution states but also applies to out-of-distribution actions, providing a broader framework for stability in offline learning environments.

In addition to handling unfamiliar states, the ASIR method demonstrates robust performance against disturbances. To evaluate this robustness under real-world conditions, the researchers injected Gaussian noise into the actions to push the agent toward out-of-distribution states. As the duration of the perturbation increased, the ASIR method exhibited significantly smaller performance degradation and lower variance compared to existing benchmark methods.

The experimental evaluation of the ASIR method was conducted on the D4RL and NeoRL benchmark tasks. The results show that the proposed method achieves state-of-the-art performance on these standard benchmarks.

Subject of Research: Development of the ASIR method for addressing out-of-distribution states in offline reinforcement learning.

Article Title: Addressing out-of-distribution states for offline reinforcement learning with interference robustness

Article References: Liu, W., Quan, X., Ren, L., Yang, L., & Sun, C. (2026). Addressing out-of-distribution states for offline reinforcement learning with interference robustness. Applied Intelligence, 56(16), Article 550. https://doi.org/10.1007/s10489-026-07558-7

Image Credits: AI Generated

DOI: 10.1007/s10489-026-07558-7

Keywords: offline reinforcement learning, out-of-distribution states, inverse dynamics model, ASIR, D4RL, NeoRL, policy regularization, robustness, Applied Intelligence, Addressing, out-of-distribution, states

News Source: Denise Maddox. (November 8, 2026). New Algorithm Keeps Offline RL Agents Safe. Scienmag.
Tags: addressingApplied IntelligenceASIRD4RLinverse dynamics modelNeoRLoffline reinforcement learningout-of-distributionout-of-distribution statespolicy regularizationrobustnessStates
Share12Tweet7Share2ShareShareShare1

Related Posts

High-Purity Water Enables Low-Grade Alcohol Synthesis of Gold Nanoparticles

High-Purity Water Enables Low-Grade Alcohol Synthesis of Gold Nanoparticles

November 8, 2026
Qatar Study Finds Solar Cooling Cuts Building Emissions

Qatar Study Finds Solar Cooling Cuts Building Emissions

November 8, 2026

Bilateral Preference Algorithm Optimizes Task Scheduling and Energy in Edge Computing

November 8, 2026

Srinagar’s Rapid Urban Growth Drains Wetlands and Raises Heat

November 8, 2026

POPULAR NEWS

  • Proteomic Shifts in Macaques Reveal Alzheimer's Targets

    Proteomic Shifts in Macaques Reveal Alzheimer’s Targets

    29 shares
    Share 12 Tweet 7
  • Sugarcane Molasses Fuels PHB Production by Pseudomonas Strain

    29 shares
    Share 12 Tweet 7
  • Evaluation Reveals Barriers to Implementing Oral Health Care in Nursing Homes

    29 shares
    Share 12 Tweet 7
  • Kidney Disease Decision Toolkit Demonstrates Strong Patient and Clinician Acceptability

    29 shares
    Share 12 Tweet 7

About

We bring you the latest biotechnology news from best research centers and universities around the world. Check our website.

Follow us

Recent News

Proteomic Shifts in Macaques Reveal Alzheimer’s Targets

Sugarcane Molasses Fuels PHB Production by Pseudomonas Strain

Evaluation Reveals Barriers to Implementing Oral Health Care in Nursing Homes

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 86 other subscribers
  • Contact Us

Bioengineer.org © Copyright 2023 All Rights Reserved.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Homepages
    • Home Page 1
    • Home Page 2
  • News
  • National
  • Business
  • Health
  • Lifestyle
  • Science

Bioengineer.org © Copyright 2023 All Rights Reserved.