An integrated federated learning framework that combines variational-autoencoder feature distillation, momentum-guided server aggregation, and phase-based delayed communication addresses key bottlenecks caused by statistical data heterogeneity. In federated learning environments, statistical heterogeneity across client devices presents persistent operational obstacles, typically causing client drift, slow optimization convergence, and lower overall model accuracy.
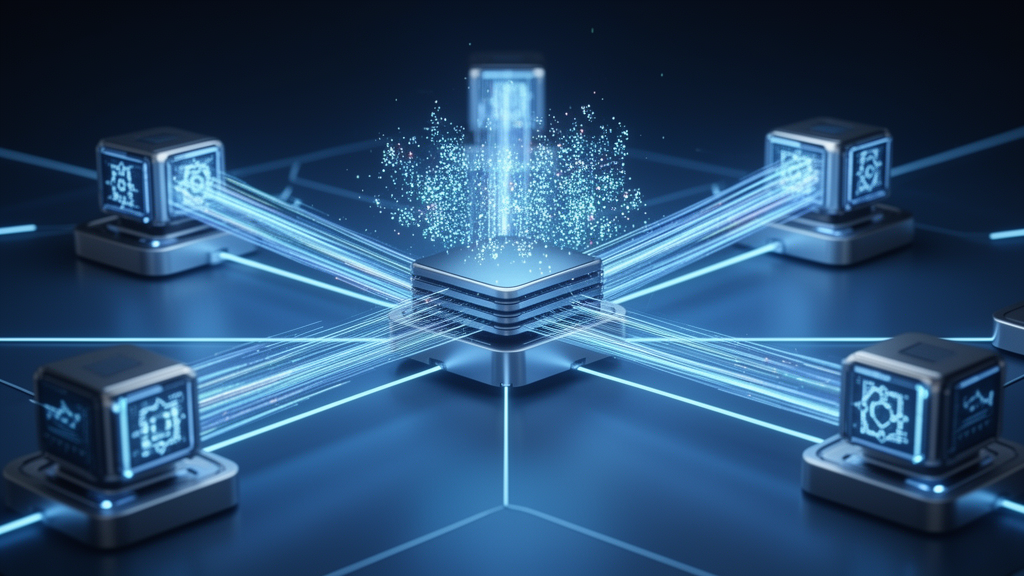
Developed by researchers Linhai Nie, Jin Wang, and Naixuan Hu, the proposed architecture alters how client nodes process and transmit information. Under this framework, each client extracts performance-sensitive residual features directly from local data. Rather than transmitting raw measurements, each client perturbs these residual representations using Gaussian noise and uploads the resulting proxy data, while original data samples remain on the clients.
These uploaded proxy representations supply crucial shared information to guide the collective training process. At the central server, a dedicated momentum term accumulates historical global updates to stabilize model optimization against erratic parameter fluctuations. Furthermore, network traffic is regulated by design, as clients communicate with the central server only during scheduled aggregation phases rather than transmitting updates continuously.
The researchers evaluated the system across three standard image benchmarks: CIFAR-10, CIFAR-100, and SVHN. When utilizing the best-performing communication schedule, the framework reached higher test accuracy than the competing FedFed baseline across every evaluated configuration. The observed accuracy margin over FedFed spanned from 0.02 to 22.55 percentage points, with the advantage remaining small in configurations where FedFed was strongest.
To examine performance under varying non-identical data distributions, the authors conducted an additional sweep across twenty-one configurations. This analysis evaluated seven Dirichlet concentration parameters spanning from 0.02 to 0.09. Across this sweep, the performance margin over FedFed ranged from 1.23 to 22.55 percentage points, confirming consistent accuracy improvements across varied statistical distributions.
In single-host computational runs, the framework demonstrated substantial efficiency advantages when benchmarked against FedAvg. The proposed approach reduced overall communication volume by 78.0 percent to 97.6 percent relative to FedAvg. It simultaneously decreased wall-clock time to target accuracy by 75.9 percent to 98.7 percent, though these operational gains came at the cost of additional proxy-data memory.
The investigation also assessed reconstruction hazards under an evaluated model-inversion attack across CIFAR-10, CIFAR-100, and SVHN. Applying Gaussian perturbation lowered structural similarity index measure values by 64.31 percent to 82.77 percent. The authors highlighted that while this reduction indicates decreased reconstruction risk, the perturbation technique does not constitute a formal privacy guarantee.
Subject of Research: Federated learning optimization under statistical data heterogeneity
Article Title: A robust federated learning method for data heterogeneity with enhanced momentum-guided aggregation
Article References: Nie, L., Wang, J., & Hu, N. (2027). A robust federated learning method for data heterogeneity with enhanced momentum-guided aggregation. Cluster Computing, 30(1), Article 12. https://doi.org/10.1007/s10586-026-06801-7
Image Credits: AI Generated
DOI: 10.1007/s10586-026-06801-7
Keywords: federated learning, statistical heterogeneity, data heterogeneity, variational autoencoders, feature distillation, momentum-guided aggregation, client drift, proxy data, Gaussian perturbation, CIFAR-10, CIFAR-100, SVHN, FedFed, FedAvg, model inversion, structural similarity index, Dirichlet concentration
News Source: Veronica Carney. (November 16, 2026). Momentum aggregation framework reduces federated learning communication volume and improves accuracy. Scienmag.