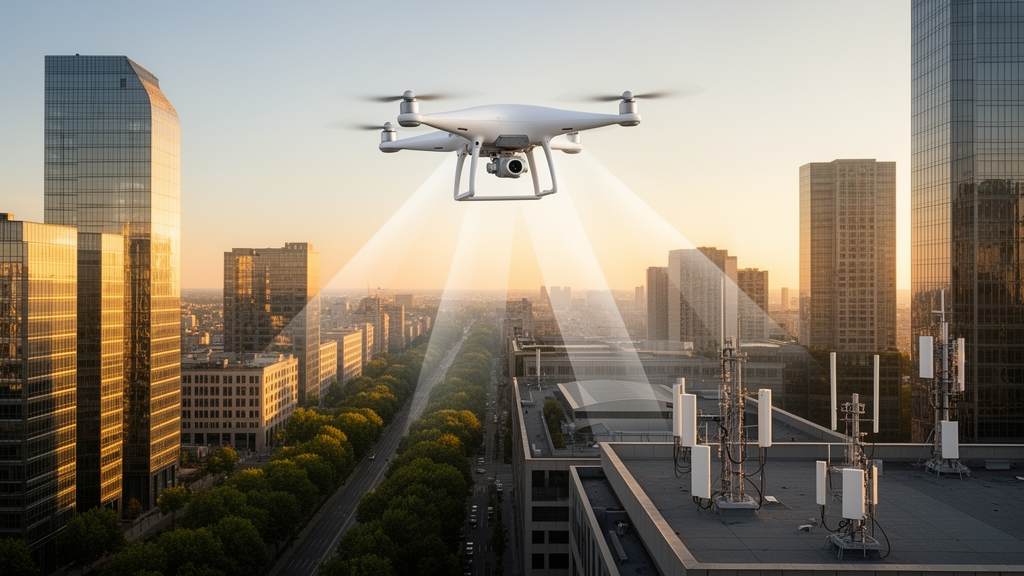
Researchers have developed an integrated computational framework that couples metaheuristic search with twin delayed reinforcement learning to solve complex resource allocation and wireless power transfer problems in drone assisted mobile networks. In next-generation fifth-generation and beyond fifth-generation systems, direct device-to-device links offer substantial improvements in spectral utilization and spatial reuse, yet their practical deployment alongside unmanned aerial vehicles remains heavily constrained by the operational flight time and battery capacity of aerial nodes. To address these critical energy limitations, a newly published study introduces an optimization framework designated as PSOT, which combines particle swarm optimization with a twin-delayed deep deterministic policy gradient reinforcement learning agent. The system model incorporates simultaneous wireless information and power transfer across a millimeter-wave environment, allowing ground-based transmitter units to scavenge radio frequency energy broadcast by aerial platforms. Through systematic computer simulations conducted under rigorous mathematical channel models, the researchers demonstrated that their dual-phase optimization framework achieves higher total energy efficiency and data throughput than prevailing reinforcement learning baselines, while successfully satisfying strict quality-of-service parameters, transmission power boundaries, and physical altitude constraints.
The structural motivation behind the investigation focuses on addressing the severe operational trade-offs encountered when unmanned aerial vehicles are dispatched to assist terrestrial wireless infrastructure. While aerial platforms provide agile mobility, wide geographical coverage, and dependable line-of-sight connectivity—qualities indispensable during emergency disaster recovery, public safety operations, and temporary network congestion—their internal energy storage fundamentally dictates network longevity. Replacing depleted drone batteries in disaster zones or inaccessible environments presents high logistical costs and operational delay. Simultaneous wireless information and power transfer provides an architectural alternative by allowing ground transmitters to capture ambient radio frequency energy emitted by aerial transmitters. Ground devices subsequently utilize power-splitting architectures to partition incoming signals between information decoding and energy harvesting circuitry.
To capture these physical interactions, the investigative team established an analytical channel and propagation model governed by specific geographical and radio properties. In the air-to-ground communication links between aerial units and terrestrial devices, the mathematical probability of maintaining an unobstructed line-of-sight path depends directly on the platform altitude, horizontal spatial separation, and environmental constants reflecting building density. When line-of-sight conditions fail due to urban clutter or geographic obstacles, signals propagate through non-line-of-sight paths subject to substantially steeper attenuation exponents and higher excessive path loss factors. Terrestrial device-to-device communication channels similarly incorporate distance-dependent path loss and obstacle blockage parameters. Within the nonlinear energy harvesting formulation, the maximum obtainable direct current power was calibrated to an empirical saturation limit of twenty-four milliwatts, reflecting the physical capabilities of low-power sensor and communicator hardware. In this architecture, terrestrial transmitters split received radio frequency energy according to a dedicated power splitting ratio, simultaneously drawing energy from the primary aerial platform and interference signals from adjacent aerial units and nearby peer transmitters.
Resolving the coupled challenges of device configuration and continuous power control required a two-stage computational design that divides spatial search from dynamic control. In the initial phase, a particle swarm optimization metaheuristic explores the high-dimensional terrestrial network space to identify optimal node positions and communication candidates based on interference profiles, transmission power limits, and required data rates. Particle swarm optimization provides global search capability across vast decision landscapes, mitigating the risk of premature convergence toward local sub-optimal solutions while supporting parallelized parameter updates. Each particle within the swarm represents a candidate configuration of network policy parameters, updating its directional velocity and spatial position through personal historical bests and global swarm best achievements. By systematically screening device configurations across the entire deployment region, the particle swarm optimization module establishes an organized topological baseline within a fraction of a second, significantly lowering the complexity burden placed upon subsequent dynamic learning components.
In the subsequent phase, the optimized node configurations are transferred into a twin-delayed deep deterministic policy gradient reinforcement learning architecture, where the aerial vehicle acts as an autonomous learning agent interacting with the dynamic network environment. The learning problem is structured as a Markov decision process defined by continuous state spaces, continuous action vectors, and cumulative multi-objective reward signals. At each discrete interaction step, the aerial agent monitors its three-dimensional altitude, current transmission power, and measured signal-to-interference-plus-noise ratios across connected terrestrial receivers. The action space controls continuous policy variables, specifically the power splitting ratio and operational flight altitude. Unlike standard deep deterministic policy gradient methods that suffer from severe value overestimation due to coupled maximization steps, the twin-delayed architecture deploys two independent critic neural networks alongside dedicated target networks. By evaluating action viability through the mathematical minimum of the two independent critic estimates, the algorithm suppresses systemic Q-value bias, stabilizes gradient updates, and accelerates parameter convergence toward optimal policy boundaries.
The training regimen for the neural networks relies on an experience replay buffer that stores interaction tuples containing system states, executed continuous actions, scalar environmental rewards, and subsequent network observations. During mini-batch sampling, the temporal difference error drives gradient descent updates across both critic networks, while delayed policy updates and target policy smoothing using clipped normal distribution noise prevent policy exploitation of narrow value peaks. The primary objective function balances total energy efficiency—defined as the aggregate ratio of transmitted bits to total electrical and circuit power consumption—with network throughput, applying equal weighting constants across both performance targets. Multiple operational constraints govern the optimization landscape, including individual signal-to-interference-plus-noise ratio floors for both aerial and terrestrial receivers, minimum required data rates to preserve quality of service, power splitting ratio boundaries between zero and one, upper transmission power thresholds for all radios, and operational flight altitude limits spanning between one hundred twenty and three hundred meters.
Comprehensive computational evaluations were executed on a dedicated high-performance workstation equipped with an enterprise-grade central processing unit, one hundred twenty-eight gigabytes of memory, and dedicated graphical processing units. Across all simulated operational states, the hybrid PSOT model consistently achieved higher energy efficiency and aggregate throughput than baseline algorithms, including standalone TD3, standalone PSO, soft actor-critic, multi-agent proximal policy optimization, multi-agent deep Q-networks, and double deep Q-networks. Numerical comparisons demonstrated that while network densification increases overall resource utilization, inter-device interference eventually causes a slight rate degradation at extreme device counts, a trade-off that the dual-phase framework managed more effectively than conventional value-based baselines.
The experimental data further revealed strong dependencies between physical propagation geometry and network performance metrics. Aerial platform altitude demonstrated an inverted parabolic performance profile: increasing flight altitude up to three hundred meters expanded line-of-sight coverage and elevated total network throughput to peak levels between eight and nine point three megabits per second, but climbing beyond three hundred meters caused severe free-space path loss that sharply reduced received signal strength. Similarly, adjusting the power splitting ratio demonstrated an optimal operating window, where lower ratios increased energy harvesting opportunities at the terrestrial receiver circuits, whereas elevated ratios shifted received power toward information decoding, expanding transmission capacity at the expense of harvested electrical power.
Algorithmic runtime profiling confirmed the computational feasibility of combining metaheuristics with continuous reinforcement learning. The execution time required for the initial particle swarm optimization phase remained roughly constant at zero point forty-one seconds across training runs. When integrated with the continuous learning agent, total training duration for sixty episodes required forty-four seconds, five hundred episodes required four hundred forty-two point twenty-four seconds, and one thousand episodes required eight hundred ninety-two point thirty-four seconds. In comparative timing evaluations against alternative architectures, the proposed PSOT framework trained faster than a hybrid multi-agent deep Q-network baseline, which required fifty seconds, five hundred six point one seconds, and nine hundred eleven point three seconds across the same episode thresholds. Cumulative reward trajectories verified that the hybrid model achieved stable policy convergence around five hundred episodes, maintaining consistent peak reward returns through one thousand training episodes without exhibiting policy collapse or performance degradation.
Despite its demonstrated computational strengths, the authors documented several technical limitations and real-world deployment challenges that define boundaries for operational implementation. The primary analytical framework assumes a relatively static network layout during the initial particle swarm optimization cycle, which may require computationally intensive recalculations when mobile nodes and aerial platforms encounter frequent, rapid topological changes. Furthermore, the simulated channel model presumes immediate access to accurate channel state information and fixed quality-of-service demands, conditions that prove difficult to track in non-stationary real-world propagation environments influenced by dynamic interference from unlicensed bands. Physical flight considerations, including the drone’s own onboard battery depletion, distributed device synchronization, wireless transmission security, and formal spectrum licensing, represent vital engineering obstacles. Future research directions proposed by the authors include multi-drone collaborative coordination, cognitive radio integration, federated reinforcement learning to reduce centralized overhead, and dynamic beamforming adaptations under imperfect channel observations.
Subject of Research: Resource allocation and nonlinear energy harvesting in drone assisted device to device wireless communications
Article Title: Energy Efficient PSO Integrated TD3 Reinforcement Learning with Nonlinear Energy Harvesting in UAV Assisted D2D Networks
Article References: Pasha, S. A., & Vali Mohamad, N. M. (2026). Energy Efficient PSO Integrated TD3 Reinforcement Learning with Nonlinear Energy Harvesting in UAV Assisted D2D Networks. International Journal of Networked and Distributed Computing, 14(1), Article 12. https://doi.org/10.1007/s44227-025-00068-x
Image Credits: AI Generated
DOI: 10.1007/s44227-025-00068-x
Keywords: wireless communication, device to device networks, unmanned aerial vehicles, reinforcement learning, particle swarm optimization, twin delayed DDPG, energy harvesting, SWIPT, spectral efficiency, throughput optimization, power allocation, line of sight transmission, path loss modeling, 5G and beyond, mobile edge computing, resource management, nonlinear energy harvesting
News Source: Denise Maddox. (November 20, 2026). Hybrid Algorithm Boosts Energy Efficiency and Throughput in Drone Assisted Networks. Scienmag.