Deep excavation and foundation pit support structures serve as essential protective barriers in civil engineering, stabilizing surrounding ground, preventing wall collapse, and mitigating building settlement during underground construction. However, complex hydrological and geological environments frequently introduce structural vulnerabilities, most notably concrete cracking and water seepage. These surface defects progressively impair structural bearing capacity, accelerate groundwater infiltration, soften underlying soils, and create risks of wall displacement or catastrophic support failure. To address the operational limitations of conventional manual inspections, which remain labor-intensive, time-consuming, and prone to incomplete coverage under challenging site conditions, civil engineers have increasingly turned toward automated monitoring solutions powered by machine vision and deep learning.
In a newly reported investigation, a research team led by Chuanqi Si, Yingfu Zhao, Chen Wang, Wenxiu Guo, Yabin Mu, and Fayun Liang developed and validated a real-time surface defect monitoring methodology specifically tailored to excavation support frameworks. Traditional automated image processing approaches, such as binarization and Canny or Sobel edge detection algorithms, frequently fail when deployed in field environments due to non-uniform illumination, sensor noise, and complex background textures. Similarly, earlier machine learning monitoring frameworks often relied on disconnected two-stage workflows that separated data collection from data processing, introducing substantial latency. By systematically evaluating machine learning methods ranging from regression models to autoencoders and advanced neural networks, the investigators formulated an integrated, single-stage detection platform capable of accurately localizing defects and extracting physical parameters in real time.
Prior to designing their operational system, the researchers conducted a comprehensive comparative analysis of existing analytical frameworks utilized for civil infrastructure inspection. Support Vector Regression combined with a Bayesian evidence framework has previously demonstrated proficiency in establishing nonlinear relationships between crack opening degree and influencing factors in dam structures, yet regression techniques lack spatial localization capabilities. Standard Convolutional Neural Networks and derived variants like B-CNN and MixSegNet achieve high classification and segmentation accuracy across concrete surfaces, but their heavy computational demands and multi-scale Transformer integrations impose substantial processing delays. Convolutional Auto-Encoders combine spatial feature extraction with unsupervised reconstruction, but their symmetrical encoder-decoder layers remain constrained by structural optimization hurdles. In contrast, the You Only Look Once object detection family bypasses regional proposal stages by executing end-to-end regression and category classification in a single forward pass, providing superior inference speeds for dynamic, time-sensitive site monitoring.
Building upon the Ultralytics YOLOv8n baseline, the authors introduced two structural modifications engineered to maximize processing speed without sacrificing localization accuracy for subtle, small-scale structural flaws. First, they replaced standard convolution operations with depthwise separable convolution, which decouples spatial filtering from channel projection to substantially reduce redundant computational overhead. Second, the team integrated the Convolutional Block Attention Module directly into the Cross Stage Partial bottleneck with two convolutions architecture, known as the C2f module. This dual-attention mechanism sequentially combines channel and spatial attention maps, directing the feature extractor to focus dynamically on key structural boundaries and critical flaw geometries rather than extraneous environmental noise.
Ablation experiments conducted on the improved architecture confirmed the individual and combined effectiveness of these structural enhancements. Incorporating depthwise separable convolution alone decreased the model’s total parameter count and floating-point computational load by more than 40 percent while producing only a negligible reduction in mean average precision, substantially increasing inference frames per second. Introducing the attention module in isolation raised the mean average precision at an intersection-over-union threshold of 0.50 by two percentage points. When combined, the final lightweight model operated with only 1.9 million parameters and required just 5.3 billion floating-point operations per second, achieving an overall 41 percent parameter reduction, a 39 percent decrease in computational complexity, and a 27 percent increase in frame rate compared to the baseline network. The fully modified model achieved a mean average precision of 0.71, outperforming the baseline score of 0.67 and operating at an inference speed of up to 570 frames per second.
The training and evaluation phases utilized a curated multi-source dataset comprising approximately 3,000 crack images and 2,300 water seepage images normalized to an 800 by 800 pixel resolution. Model optimization was conducted over 120 epochs using a stochastic gradient descent optimizer with momentum set to 0.937, a weight decay coefficient of 0.0005, and a batch size of 16. The training protocol applied a linear learning rate decay schedule starting from 0.001 and tapering down to 0.000053, incorporating Ultralytics standard Bag of Freebies data augmentation strategies including mosaic augmentation with an application probability of 1.0 and mixup augmentation with a probability of 0.1. Confusion matrix analysis on the dedicated crack test set demonstrated that the model correctly identified 240 true positive crack instances while missing 147 samples, yielding a recall rate of 62.0 percent. Out of 439 total positive crack predictions, 363 were accurate and 76 were false alarms, establishing a precision rate of 82.7 percent.
To translate automated visual detections into actionable engineering safety evaluations, the research team integrated an automated contour tangent circle algorithm executed through OpenCV. Once the neural network predicts the spatial bounding box of a crack, the underlying image region is converted to grayscale, binarized, and cleaned of background noise using morphological closing operations. The system then applies a grid-sampling dichotomy strategy that tests whether uniformly distributed boundary coordinates lie within the crack contour, iteratively calculating the maximum inscribed tangent circle to determine maximum crack width with a relative error margin of six percent. Applying standard structural engineering thresholds, such as the 0.4-millimeter threshold defined in national building quality specifications, the platform automatically flags anomalies that exceed design limits, recording the precise physical coordinates, relative defect area ratio, and visual severity indicators.
The end-to-end framework was packaged into an interactive multi-user graphical interface built with Streamlit and backed by a PyTorch execution engine. The user interface provides three distinct operational workflows: a static image recognition mode for individual photo analysis, a video recognition mode for automated frame-by-frame structural inspection, and a live recording recognition mode connected to local inspection cameras for on-site visual patrols. System operators can adjust confidence thresholds, configure sensitivity levels, inspect structural judgment criteria, and review quantitative metrics encompassing defect probabilities, spatial bounding boxes, segmentation masks, and processing speeds in real time.
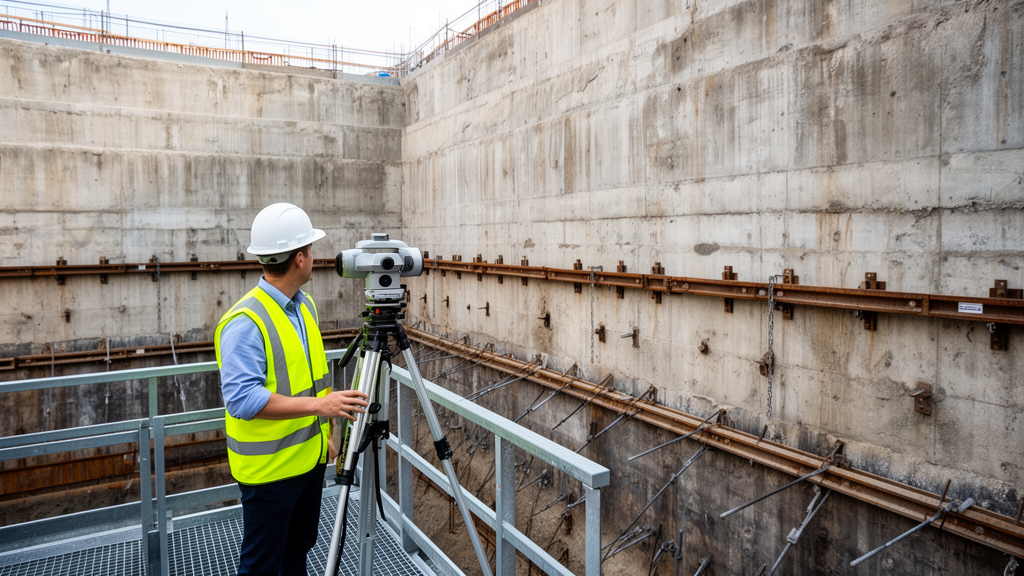
Field validation was executed within an active deep foundation excavation project located in Huzhou. The site is situated within a lake-deposit geological setting characterized by extensive artificial fill and unevenly distributed soft soils featuring high void ratios, elevated natural water contents, high compressibility, low structural strength, and weak permeability. The foundation pit measured 592.484 meters in length, between 13.3 and 28.0 meters in width, and spanned excavation depths ranging from 0.9 to 18.8 meters, supported by varied retaining structures including underground continuous diaphragm walls, construction method piles, and gravity cement-soil walls. An empirical test set consisting of 200 site-captured concave defect images alongside a broader test cohort of 500 images containing 843 defect instances verified the system’s operational stability under complex shadows, rough concrete textures, and shifting daylight conditions.
During field validation across the Huzhou construction site, the system achieved overall defect detection accuracies between 0.7 and 0.8, with recall rates ranging from 0.583 to 0.635, while maintaining structural crack quantification estimates consistently between 2.65 percent and 5.6 percent. Deployed on an NVIDIA RTX 2080 SUPER processing unit, the framework achieved an average single-image inference latency of 1.3 milliseconds, well below the two-millisecond real-time operational target, while completing full 120-cycle training runs in 0.48 hours at training processing speeds between 9.5 and 10.7 iterations per second. Detections falling below a confidence threshold of 0.1 were automatically filtered to suppress spurious false alarms in complex visual scenes.
Despite these operational capabilities, the authors noted several technical boundaries in their current implementation. While the system reliably flags seepage distribution zones and extracts maximum crack widths, it cannot currently resolve complete three-dimensional morphological parameters such as crack depth, total path length, or internal spatial volume. In addition, model generalization remains dependent on the diversity of training imagery, leaving room for performance variations when confronting novel pit geometries, extreme weather disruptions, lens occlusions, or changing groundwater chemistries. To overcome these constraints, future research directions will focus on integrating active learning frameworks to minimize data annotation burdens, exploring domain adaptation algorithms across varied excavation typologies, and formalizing camera positioning protocols to maintain high-accuracy defect surveillance across demanding underground environments.
Subject of Research: Deep learning and machine vision for surface defect detection in excavation support structures
Article Title: Investigation into enabling machine vision and machine learning technologies for surface defect detection of pit support systems
Article References: Si, C., Zhao, Y., Wang, C., Guo, W., Mu, Y., & Liang, F. (2025). Investigation into enabling machine vision and machine learning technologies for surface defect detection of pit support systems. AI in Civil Engineering, 4(1), Article 29. https://doi.org/10.1007/s43503-025-00077-3
Image Credits: AI Generated
DOI: 10.1007/s43503-025-00077-3
Keywords: civil engineering, structural health monitoring, machine vision, deep learning, foundation pits, YOLOv8, crack detection, water seepage, Investigation, enabling, machine, vision
News Source: Denise Maddox. (November 9, 2026). Engineers Adapt Vision AI to Detect Deep Foundation Pit Structural Defects. Scienmag.