Rice serves as a primary staple crop supplying dietary sustenance for more than half of the human global population, yet its cultivation remains routinely threatened by destructive foliar infections including blast, sheath blight, and brown spot that damage plant development and depress harvest yields. In a research study published in Smart Agricultural Technology, investigators Erzhi Wang, Yang Lu, Qi Lv, Shuxin Yin, Fei Li, and Fan Yang introduced ConTransformer, a dual-channel deep learning model engineered to automate the visual identification of rice leaf pathologies. Automated image-based diagnosis has emerged as an active area of precision agriculture, but existing computational frameworks frequently encounter trade-offs between local pattern resolution and wide contextual understanding. Standard convolutional neural networks prioritize local spatial cues but exhibit structural weaknesses when modeling broad contextual interactions across leaf surfaces, while standalone vision transformers build global receptive fields through self-attention but often overlook minute, low-contrast lesion boundaries. To overcome these mutual limitations, the research team designed ConTransformer to integrate the localized feature extraction capabilities of ConvNeXt V2 with a globally oriented Vision Transformer branch enhanced by a Swish-gated multilayer perceptron and an attention-guided fusion module.
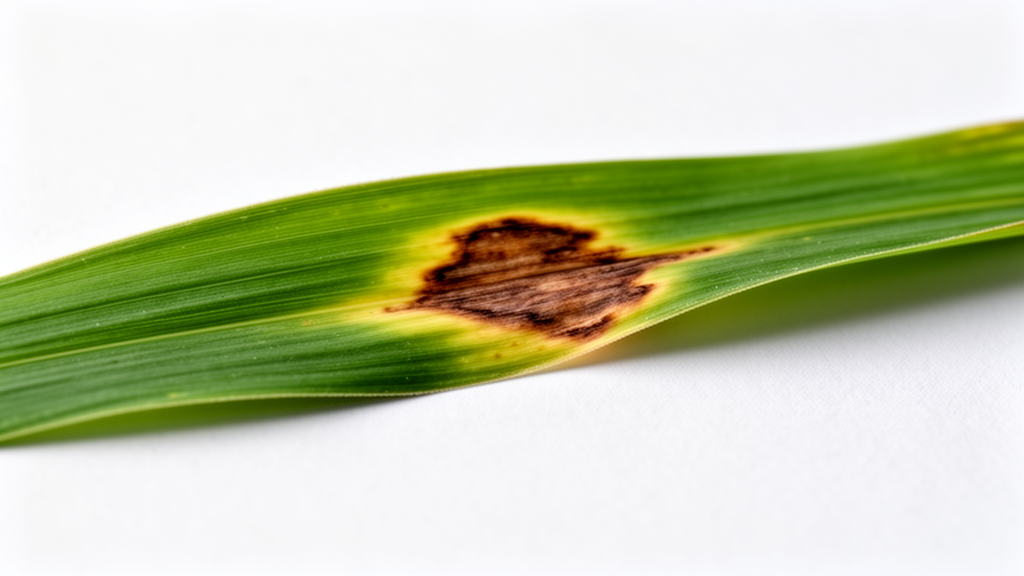
The investigative team developed ConTransformer to address the coexistence of minute lesion markings and expansive infected surfaces that characterize foliar rice pathology. In field environments, rice leaf diseases manifest across vastly disparate scales, ranging from tiny, irregularly circular or elongated necrotic spots to wide pathogen blights spreading across more than half of an individual blade. Earlier hybrid models commonly coupled convolutional networks and transformers through straightforward channel concatenation or unidirectional feature transfer, approaches that frequently introduce semantic misalignment between local textures and global contextual representations. Unidirectional transfer often restricts reciprocal interaction between fine-grained details and holistic representations, while simple concatenation leaves models susceptible to agricultural noise such as soil variations, weed foliage, and aquatic light reflections. The authors structured ConTransformer into four coordinated functional stages: a ConvNeXt local channel, an enhanced Vision Transformer global channel, an attention-driven feature fusion module, and a dedicated classification head designed to categorize leaf health status.
The convolutional channel of ConTransformer employs ConvNeXt V2 rather than conventional backbone networks such as ResNet or EfficientNet to maximize sensitivity toward fine-grained lesion contours, irregular boundaries, and low-contrast surface textures. Processing three-channel red-green-blue input images scaled to dimensions of 224 by 224 pixels, the ConvNeXt pathway begins with a preprocessing stage consisting of a 7 by 7 convolutional layer that broadens the initial receptive field, followed by a rectified linear unit activation and a 3 by 3 convolution with stride one and padding one, downsampling feature maps to 112 by 112 pixels. The channel incorporates three sequential ConvNeXt blocks, each paired with a 2 by 2 max-pooling operation with stride two to lower spatial resolution and computational overhead. Within each ConvNeXt module, feature processing relies on a 7 by 7 depthwise convolution with padding three to extract spatial attributes efficiently without excessive computational costs. This operation is followed by channel-wise Layer Normalization, a Gaussian Error Linear Unit activation, and an inverted bottleneck structure created by two 1 by 1 convolutional layers with an expansion ratio of four. Between these 1 by 1 convolutions, the architecture embeds a Global Response Normalization layer that applies L2-norm channel aggregation, normalized channel competition, and learnable affine transformation parameters to counter feature collapse and strengthen discriminative local pattern learning.
Operating in parallel, the enhanced Vision Transformer channel captures wide-range semantic correlations and macroscopic disease distribution profiles across the leaf surface. The initial patch embedding operation segments the 224 by 224 input image into 196 non-overlapping patches measuring 16 by 16 pixels, flattening them into one-dimensional vectors projected into a feature space alongside learnable classification and positional tokens. Across three successive transformer stages, the sequence passes through enhanced encoder blocks comprising Layer Normalization, multi-head self-attention mechanisms, and a modified multilayer perceptron architecture. To address the vulnerability of standard vision transformers to background clutter, the researchers replaced the standard GELU-activated multilayer perceptron with a dual-branch Swish-gated design. Within this module, an initial linear transformation maps input features into two streams: one branch executes a nonlinear transformation using the Swish activation function, while a parallel gating branch calculates multiplicative feature weights through a sigmoid function. The element-wise multiplication of these branches acts as an adaptive filter that emphasizes disease indicators while dampening field noise. Between stages, PatchMerging modules aggregate adjacent two-by-two patch groups, reducing token sequence lengths by a factor of four while doubling feature dimensions through linear projection to build a hierarchical contextual representation.
Bridging these two distinct analytical pathways, the dedicated feature fusion module synthesizes complementary local and global representations without relying on naive channel stacking. The output from the ConvNeXt branch is adjusted via adaptive average pooling to match the spatial geometry of the reshaped Vision Transformer output, and both feature maps are channeled through independent 1 by 1 convolutions without padding to standardize their channel depth to 512. The resulting representations are concatenated along the channel dimension to form a joint tensor with 1024 channels. To resolve semantic inconsistencies and isolate pathology-bearing leaf zones from irrelevant surroundings, the module extracts global average and maximum pooling vectors across spatial dimensions, concatenates them into a unified feature stream, and executes deep feature extraction using a standard 7 by 7 convolution. A sigmoid activation then transforms these signals into spatial attention weights that recalibrate the joined feature map. The calibrated representation passes into a 3 by 3 depthwise separable convolution to preserve localized correlations at low computational cost, traverses a HardSwish activation layer and a 1 by 1 convolution, and concludes with Layer Normalization to ensure steady numerical gradient flow during training.
To rigorously evaluate the framework, the authors compiled an experimental dataset comprising 14,280 leaf images categorized into seven distinct classes, consisting of healthy leaves alongside six major rice diseases: blast, brown spot, leaf scald, sheath blight, bacterial leaf blight, and leaf smut. The dataset integrated two origins: a self-collected dataset acquired in a demonstration field in Tailai County, Qiqihar City, Heilongjiang Province, using a Huawei Mate 60 Pro smartphone positioned approximately 20 centimeters from specimens under diverse ambient lighting, and secondary imagery compiled from public repositories including Kaggle. The researchers divided the 14,280 images across classes into training, validation, and testing subsets using a stratified 8:1:1 split, yielding 11,424 training images, 1,428 validation images, and 1,428 independent testing images. Data augmentation techniques—including horizontal flips, 15-degree rotations, brightness and contrast adjustments, Gaussian blurring, and Gaussian noise additions—were applied solely to the training set to prevent evaluation leakage while simulating practical agricultural image noise. Computational training was performed using Python 3.8.10 and PyTorch 1.10.0 on a dedicated server equipped with an Intel Xeon Gold 6430 central processing unit, 120 gigabytes of random access memory, and an Nvidia RTX 4090 graphics processing unit with 24 gigabytes of video memory. Optimization utilized the AdamW algorithm over 200 epochs with an initial learning rate of 5e-5, a weight decay coefficient of 0.2, momentum coefficients beta-one of 0.9 and beta-two of 0.999, a training batch size of eight, and a Focal Loss objective with alpha 1.0 and gamma 2.0.
Across the independent 1,428-image test set, ConTransformer attained an overall classification accuracy of 99.07 percent, alongside macro-averaged precision of 99.01 percent, recall of 98.87 percent, and an F1 score of 98.93 percent. In comparative benchmarks against established vision models evaluated under identical dataset partitions and resolutions, ConTransformer surpassed both single-stream architectures and hybrid convolutional-transformer frameworks. Single-channel lightweight MobileNetV3 achieved an accuracy of 97.32 percent, precision of 97.40 percent, recall of 97.33 percent, and F1 score of 97.35 percent, while pure attention-based Swin Transformer registered 98.35 percent accuracy, 96.78 percent precision, 97.45 percent recall, and 97.94 percent F1 score. ConTransformer also demonstrated consistent superiority over existing dual-channel architectures, including LGNet at 88.74 percent accuracy, TinyViT at 97.63 percent accuracy, Efficient-ViT B0Net at 98.13 percent accuracy, LocalViT at 98.20 percent accuracy, and DB-CGANNet at 98.42 percent accuracy. In computational complexity assessments measured on the RTX 4090 GPU with batch size one, ConTransformer contained 10.33 million parameters, required 3.11 floating-point operations in billions, and completed single-image inference in 5.21 milliseconds, presenting a balanced compromise against heavier baselines such as Swin Transformer with 27.01 million parameters and 8.63 milliseconds latency, and DB-CGANNet with 22.31 million parameters and 15.02 milliseconds latency.
To confirm that the observed diagnostic performance was statistically sound rather than an artifact of weight initialization, the investigators conducted five independent training runs comparing ConTransformer against DB-CGANNet, the highest-performing comparative baseline. Across these five separate runs, ConTransformer maintained a mean accuracy of 99.07 percent with a standard deviation of 0.11 percent, exhibiting individual test run accuracies of 98.97 percent, 99.17 percent, 99.08 percent, 99.18 percent, and 98.94 percent. In comparison, DB-CGANNet yielded a mean accuracy of 98.42 percent with a standard deviation of 0.09 percent across run values of 98.32 percent, 98.46 percent, 98.44 percent, 98.53 percent, and 98.35 percent. A two-sided independent samples t-test conducted on these repeated runs produced a p-value of 6.90e-6, establishing that the performance superiority of ConTransformer over DB-CGANNet achieved strong statistical significance. Analysis of category-specific confusion matrices further revealed that ConTransformer generated minimal false classifications, exhibiting near-perfect discrimination between healthy leaves and blast-infected specimens, while showing only minor confusion between brown spot, leaf scald, and sheath blight due to similar color distributions and textural traits.
Systematic ablation trials documented the individual performance contributions of ConTransformer’s architectural components. An isolated ConvNeXt branch without transformer support achieved an accuracy of 97.13 percent, a precision of 97.09 percent, a recall of 96.89 percent, and an F1 score of 96.94 percent, confirming that convolutional extraction alone lacks sufficient long-range modeling. An unenhanced Vision Transformer operating in isolation produced an accuracy of 96.51 percent, which increased to 97.37 percent upon incorporating the Swish-gated multilayer perceptron. Within the dual-channel ConTransformer architecture, omitting the enhanced multilayer perceptron reduced classification accuracy to 98.03 percent, while removing the Global Response Normalization mechanism dropped accuracy to 98.40 percent. Furthermore, replacing the attention-based feature fusion module with direct channel concatenation decreased accuracy to 98.25 percent, precision to 98.10 percent, recall to 97.84 percent, and F1 score to 97.91 percent. The complete ConTransformer assembly, integrating Global Response Normalization, Swish-gated multilayer perceptrons, and spatial attention fusion, achieved peak values across all four evaluation metrics, confirming that the combination of modules generates synergistic performance improvements.
Qualitative inspection of feature activations through heatmap visualizations tracked the progressive aggregation of spatial patterns across intermediate network layers. Visualizations of three successive fusion stages demonstrated that early network layers concentrate activations tightly on localized leaf lesions. In intermediate fusion stages, activation maps broaden across surrounding leaf backgrounds as the network explores contextual dependencies, whereas final fusion stages draw activation intensity back toward infected blade areas while suppressing surrounding background artifacts. Branch-wise visualization confirmed that the ConvNeXt pathway focuses on fine-grained pathological markings, whereas the Vision Transformer pathway maintains broader structural attention across the leaf surface. The final fused representation integrates both traits, retaining sharp sensitivity to local lesions while sustaining coherent contextual coverage of diseased leaf tissue.
To evaluate cross-crop transferability, the researchers transferred the trained network weights to classify soybean leaf conditions using a 3,652-image subset from the public Plant Disease Classification Merged Dataset on Kaggle. The soybean dataset encompassed healthy leaves alongside three specific conditions: South American leaf beetle damage, caterpillar damage, and powdery mildew, each containing 913 images partitioned via the same 8:1:1 training, validation, and testing ratio. Retaining pre-trained parameters and swapping the final classification layer from seven outputs to four, fine-tuned ConTransformer achieved an accuracy of 92.78 percent on the independent soybean test set, outperforming LocalViT at 90.22 percent, Efficient-ViT B0Net at 88.11 percent, and TinyViT at 87.25 percent. Despite these outcomes, the authors identified limitations in their current work, noting that field imagery was sourced primarily from a specific geographic region in Heilongjiang Province, which may constrain model robustness when deployed across differing climate zones, soil types, and capture hardware. Additionally, severe operational conditions—including overlapping lesions from co-occurring pathogens and extreme lighting fluctuations such as heavy shadows or overexposure—pose ongoing technical hurdles that will require broader multi-regional dataset collection and improved feature fusion designs in future research.
Subject of Research: Deep learning architecture for automated rice leaf disease identification
Article Title: ConTransformer: Integrating local and global features for accurate identification of rice leaf diseases
Article References: Wang, E., Lu, Y., Lv, Q., Yin, S., Li, F., & Yang, F. (2026). ConTransformer: Integrating local and global features for accurate identification of rice leaf diseases. Smart Agricultural Technology, 15, Article 102688. https://doi.org/10.1016/j.atech.2026.102688
Image Credits: AI Generated
DOI: 10.1016/j.atech.2026.102688
Keywords: rice leaf disease, ConTransformer, computer vision, deep learning, ConvNeXt V2, Vision Transformer, precision agriculture, crop pathology, Integrating, local, global, features
News Source: Alan Morgan. (November 8, 2026). Dual-Branch ConTransformer Model Improves Rice Leaf Disease Identification Accuracy. Scienmag.