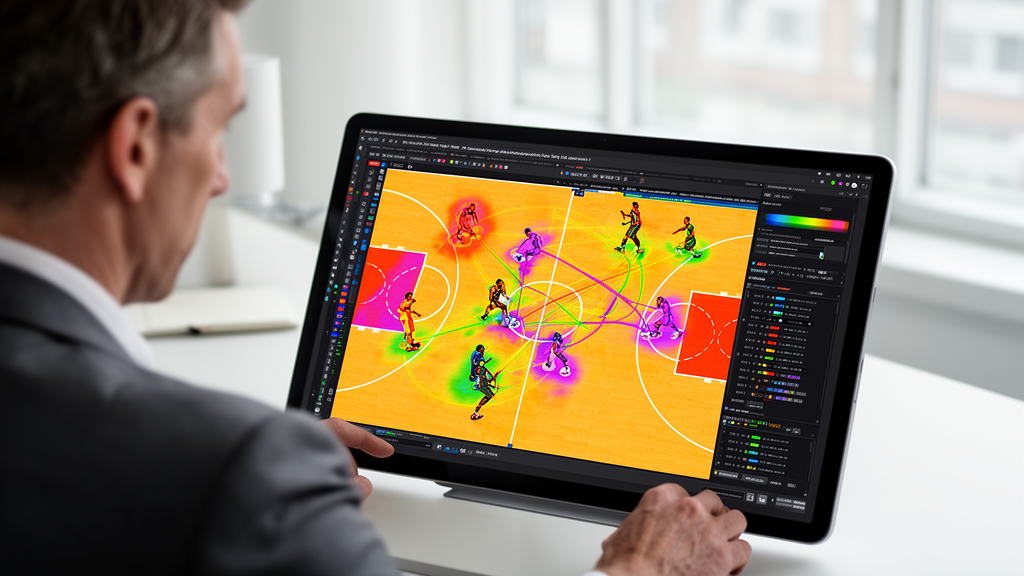
A controlled pedagogical study published in Discover Artificial Intelligence demonstrates that integrating deep reinforcement learning into basketball tactics classes substantially improves the speed, agreement, and overall execution accuracy of instructional coaching decisions. Conducted across an eight-week curriculum involving forty-eight physical education students, the research established that a specialized deep Q-network framework reduced the average latency of teacher interventions from 18.7 seconds under traditional instruction to just 5.2 seconds. Rather than replacing the teacher, the computational framework operates as a continuous state-action-feedback pipeline that tracks five-on-five student interactions across one-second classroom time slices, identifying emergent tactical errors and recommending structured interventions. The classroom experiment confirmed that this dynamic guidance not only expedited instructional delivery but also elevated comprehensive tactical understanding scores from 69.5 percent to 88.4 percent, while tactical execution accuracy rose from 66.7 percent to 87.7 percent compared to standard conventional coaching practice.
Traditional basketball tactical education often relies on retrospective, experience-based feedback delivered during extended pauses or after full practice drills conclude. In typical five-on-five half-court sessions, instructors must simultaneously track player spacing, ball movements, off-ball cuts, screen executions, and defensive rotations across ten dynamic participants within a strict twenty-four-second shot clock. Human observation inevitably experiences perceptual bottlenecks and delayed recognition of positional breakdowns, which impedes timely remediation and limits continuous pedagogical feedback iteration. Prior automated systems in physical education have largely concentrated on post-hoc movement analysis, game outcome predictions, or static training plan generation using genetic algorithms. However, as noted in the study’s theoretical foundation, static scheduling models and competition-focused algorithms struggle to address fluid instructional decisions such as when to call a localized correction, run a tactical reenactment, or rotate tactical roles in real-time training environments.
To resolve these operational constraints, the authors constructed a unified mathematical representation that translates standard 5v5 classroom dynamics into a structured state vector. Operating across a standard fourteen by fifteen meter half-court area, the data collection infrastructure continuously synchronizes thirty frame-per-second video streams with ten-hertz trajectory coordinates, twenty-four-second attack clock states, pass points, screen events, and defensive movement tracking. Every one-second time slice combines the two-dimensional planar coordinates and velocity vectors of all ten students and the basketball, alongside specific categorical variables. These categories encode ball possession phases including dribbling, passing, receiving, and shooting, as well as operational tactical roles such as on-ball offense, off-ball defense, help defense, and perimeter rotations. The input pipeline also registers tactical task identifiers, such as pick-and-roll setups or defensive transitions, and instructor intervention history, forming a comprehensive one-hundred-and-twenty-eight-dimensional classroom state vector for algorithmic processing.
The policy optimization architecture relies on a deep Q-network specifically tailored to balance pedagogical impact against instructional disruption. The model defines a discrete action space containing six distinct teacher interventions: timeout explanations, localized technical corrections, tactical replays, role rotations, group scrimmages or confrontation drills, and individual prompts. To ensure practical pedagogical relevance, each intervention candidate carries explicit trigger conditions based on observable court errors, including spatial positioning deviations, passing delivery delays, help-defense misalignments, and shot-clock depletion. The action selection mechanism explicitly subtracts execution cost penalties, reflecting lost practice time and classroom interruption, alongside perturbation constraints to avoid unnecessary friction in training rhythm. An attention mechanism weights individual student behavioral embeddings based on their tactical centrality, allowing the policy network to evaluate which pedagogical intervention delivers maximal utility for any identified court failure.
A critical engine of the system is its multi-component reward function, which quantifies whether a recommended teacher action produces measurable tactical improvement. The reward combines normalized tactical execution metrics, such as arrival positioning accuracy, passing trajectory rationality, screen completion rates, and defensive recovery speeds, with the directional progress of the team toward a standard tactical template. Interventions that disrupt instructional continuity or introduce excessive physical workload are penalized via designated cost coefficients. Transitions generated during training were stored in an experience replay buffer holding twenty thousand samples. To accelerate learning on rare or acute tactical breakdowns, the system deployed prioritized experience replay governed by temporal difference errors, assigning higher sampling probabilities to severe positioning errors, misaligned defensive rotations, and delayed passes. Mini-batches of sixty-four transitions were sampled to train the three-layer network using the Adam optimizer and Huber loss minimization.
To guarantee that the experimental evaluation in the physical classroom provided genuine out-of-sample validation, the researchers strictly isolated model development from instructional testing. Network parameters were trained across twelve hundred iterations using a fixed random seed of forty-two, gradually decaying the epsilon-greedy exploration probability from 1.00 down to 0.05 over nine hundred rounds, while synchronizing target network weights every two hundred updates to prevent value oscillation. Once training stabilized, showing an average TD error reduction to 0.082 and an action-selection stability rate of 88.9 percent, the deep Q-network weights were completely frozen. Throughout the subsequent eight-week classroom evaluation, the algorithm operated strictly in inference mode: incoming one-second state vectors were assessed, recommendations were gated by cost and load boundaries, and student outcomes were logged for evaluation without permitting online gradient updates to alter the deployed policy.
The classroom trial was conducted with forty-eight enrolled university students, comprising thirty-two male and sixteen female participants with a mean age of 19.6 years and an average of 3.2 years of basketball experience. Baseline examinations evaluated tactical intent recognition, passing decisions, movement path consistency, help-defense judgment, and conceptual tactical knowledge. Using stratified randomization based on these initial scores, the cohort was divided into four balanced groups of twelve students: a traditional instruction control group, an experience-based correction group, a rule-threshold recommendation group, and the DQN dynamic recommendation group. Baseline composite performance scores showed no statistically significant differences across the four cohorts prior to training. All groups completed sixteen standardized forty-minute sessions totaling six hundred and forty minutes of instruction, taught by the same instructor utilizing identical 5v5 task sequences, court environments, and offensive shot-clock constraints.
Classroom intervention episodes under the algorithmic setup operated through an event-triggered decision gate that prevented constant, disruptive signaling. Across each forty-minute session, representing twenty-four hundred candidate one-second decision intervals, the recommendation interface opened only when specific trigger conditions—such as acute spatial deviations, rapid possession changes, or defensive breakdowns—occurred. When gated open, the frozen DQN selected one of the six instructional actions, which the on-court teacher implemented. Reference standards for instructional appropriateness were established by two independent, masked coaching instructors who evaluated de-identified event logs without knowledge of group assignments or model outputs, achieving an inter-rater agreement of Cohen’s kappa equal to 0.86. Discrepancies between the human coders were adjudicated by a third independent instructor to maintain strict empirical consistency across all evaluated instructional events.
Statistical evaluation using participant-level linear mixed-effects models revealed significant Group by Time interactions across all evaluated tactical comprehension and performance metrics. In the primary comparison between traditional instruction and DQN dynamic recommendation, the algorithm-guided cohort exhibited substantial gains across every operational domain. Average intervention response latency was 13.5 seconds shorter in the DQN group compared to traditional instruction, registering 5.2 seconds versus 18.7 seconds. Furthermore, the instructional-action agreement rate reached 89.4 percent in the DQN group compared to 71.6 percent under conventional practice. The invalid intervention rate, defined as instances where targeted tactical deviations failed to decrease over the ten consecutive seconds following teacher action, dropped from 24.3 percent in the traditional group to just 7.9 percent in the DQN condition, demonstrating that rapid delivery was paired with superior contextual precision.
Student learning outcomes demonstrated corresponding advantages in collective tactical execution and teamwork stability. Within the DQN group, positioning accuracy increased from a pretest baseline of 69.7 percent to a posttest mark of 90.7 percent, while screen-coordination completion climbed from 65.8 percent to 86.9 percent, and transition coordination reached 87.8 percent. Teamwork stability, computed as the composite mean of screen coordination, help defense accuracy, and transition coordination, stood at 86.4 percent in the DQN condition compared to 65.3 percent for traditional instruction. Importantly, the DQN system also maintained a statistically significant advantage over the rule-threshold condition, outperforming fixed threshold rules by 7.7 to 8.3 percentage points in tactical understanding indicators and 8.1 to 9.0 percentage points in execution metrics, confirming that continuous value estimation captures subtle collective court dynamics that simple heuristic threshold boundaries miss.
Despite these clear empirical gains, the investigators identified several boundaries to the present study’s scope and generalizability. The classroom evaluation was restricted to a single educational course with forty-eight participants, indicating that broader multi-site investigations with larger and more diverse student cohorts are required to confirm scalability. Furthermore, student skill assessments were recorded immediately within forty-eight hours of course completion; delayed retention assessments at four and eight weeks are necessary to evaluate whether tactical understanding persists over time and transfers effectively to unfamiliar offensive or defensive game systems. The authors also noted that future research could integrate multimodal physiological streams, such as wearable inertial measurement units and heart-rate telemetry, while exploring Double DQN or Dueling DQN architectures to further dissect the comparative contributions of prioritized replay, network structure, and teacher-in-the-loop interaction mechanisms.
Subject of Research: Optimization of physical education basketball tactics instruction using deep Q-networks and prioritized experience replay
Article Title: A study on the optimization of basketball tactics classroom teaching strategies based on deep reinforcement learning
Article References: Liu, Z., & Qian, L. (2026). A study on the optimization of basketball tactics classroom teaching strategies based on deep reinforcement learning. Discover Artificial Intelligence, 6(1), Article 1723. https://doi.org/10.1007/s44163-026-02404-8
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02404-8
Keywords: deep reinforcement learning, deep Q-network, basketball tactics, classroom intervention, physical education, prioritized experience replay, tactical understanding, tactical execution, response latency, educational technology, sports pedagogy, state representation, Huber loss, instructional action space, action agreement rate, teamwork stability, motion trajectory analysis
News Source: Denise Maddox. (November 14, 2026). Deep Reinforcement Learning Accelerates and Enhances Basketball Tactical Classroom Coaching Interventions. Scienmag.