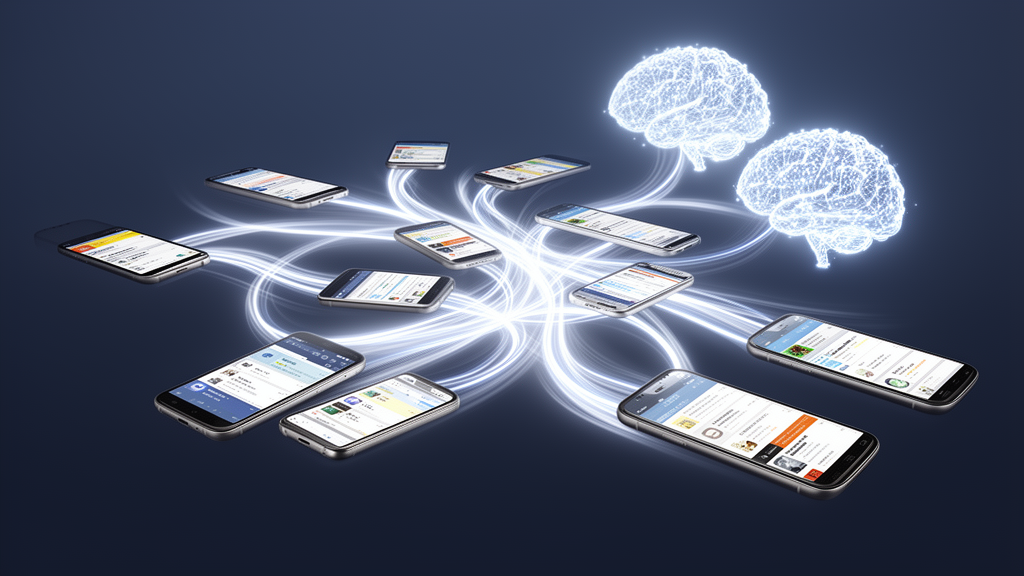
Computer scientists have designed two reinforcement learning routing protocols, RLON and DQON, that significantly improve message transmission across opportunistic networks where fixed cellular infrastructure is unavailable or overloaded. In intermittent mobile networking environments characterized by frequent link disruptions and absence of continuous end-to-end paths, intermediate mobile nodes rely on store-carry-forward mechanisms to physically transport data packets. Evaluating the newly developed protocols in simulation across diverse synthetic human mobility models and established real-world trace datasets, the researchers demonstrated that integrating adaptive tabular learning enables autonomous relay selection. Compared directly against RLProph, a leading policy-iteration baseline, the proposed protocols achieved delivery probability enhancements between 4 percent and 23 percent, overhead ratio reductions from 12 percent to 35 percent, and end-to-end latency decreases between 10 percent and 32 percent across diverse movement conditions.
Opportunistic networks operate as a specialized class of delay-tolerant networks where device movement dictates communication possibilities. Conventional routing techniques developed for these environments traditionally fall into flooding-based paradigms, such as Epidemic routing, or forwarding-based paradigms governed by heuristics, such as PRoPHET or Spray and Wait. Flooding schemes repeatedly replicate messages across encountered devices in an attempt to reach destinations, but rapidly exhaust node buffer capacity and generate unsustainable network overhead through excessive redundant transmissions. Conversely, heuristic forwarding methods depend on static or historical encounter metrics that struggle to dynamically capture the shifting spatial and temporal dynamics of human mobility. The investigative team sought to overcome these structural bottlenecks by formulating the opportunistic message relay problem as an autonomous Markov decision process, allowing individual nodes to learn optimal forwarding policies directly through local interaction feedback.
The first protocol, designated Reinforcement Learning based Opportunistic Networks, or RLON, integrates standard Q-learning to guide message custody transfers between encountering nodes. Within the RLON architecture, every mobile device operates as an independent learning agent maintaining a local Q-table initialised to zero. To ensure systematic policy formulation, the researchers defined a four-dimensional state tuple capturing local buffer occupancy, congestion measured by messages per contact, encounter probability with the intended destination node or its community proximity, and the remaining time-to-live of the message. When nodes encounter one another, the local agent evaluates candidate actions comprising either forwarding the message to a specific encountered neighbour or retaining custody until future contact opportunities arise. The underlying action-value function is updated iteratively upon transmission feedback, weighting immediate delivery rewards against deliberate penalties assigned to buffer overflow and excessive replication.
To overcome fundamental mathematical limitations inherent in standard Q-learning, the researchers introduced Double Q-Learning based Opportunistic Networks, or DQON. In standard Q-learning, action selection and target value estimation both employ a maximization operator, which systematically induces overestimation bias where expected cumulative rewards are evaluated higher than true underlying performance. In sparse opportunistic networks, where contact events are rare and long inter-contact intervals separate encounters, inflated Q-values persist over extended periods without corrective updates, misdirecting traffic toward suboptimal relays and causing catastrophic packet replication. DQON eliminates this positive estimation loop by decoupling action selection from value estimation across two distinct action-value functions, denoted as Q1 and Q2. Updates alternate stochastically between the two functions: one function determines the maximizing candidate action, while the companion function computes the target value, effectively dampening bias and ensuring stable policy convergence.
The operational framework of both protocols is governed by an epsilon-greedy exploration and exploitation schedule combined with dedicated reward propagation and buffer management procedures. During exploration, an agent selects random neighbouring relays with probability epsilon to sample unexplored connectivity opportunities across changing topologies, while with probability one minus epsilon, it exploits accumulated knowledge to forward data along paths maximizing expected cumulative reward. When a message successfully reaches its destination, the receiving terminal issues an acknowledgement containing immediate positive reinforcement. As intermediate custodian nodes encounter peers across subsequent mobility steps, they propagate reward values backward along the delivery path and broadcast message clearance notifications. Intermediate relays holding residual redundant message copies purge them from local storage upon verifying successful destination delivery, directly preventing storage exhaustion and mitigating control overhead.
Extensive simulation experiments were conducted using the Opportunistic Network Environment, or ONE, simulator to benchmark RLON and DQON against Epidemic, PRoPHET, Spray and Wait, and RLProph protocols. The experimental evaluations spanned synthetic mobility configurations, including the Community Aware Heterogeneous Human Mobility Model and Map-based movement patterns, alongside five recognized empirical trace datasets: Infocom05, Infocom06, Cambridge, Reality, and Sassy. These real-world mobility traces encompass diverse operational environments, ranging from dense multi-day academic conferences tracked with Bluetooth-enabled imotes to sparse, long-term organizational deployments spanning dozens of participants across several months. Reliability of performance metrics—comprising delivery probability, overhead ratio, and average latency—was established through ten distinct simulation runs executed under varied pseudorandom seeds, yielding 95 percent confidence intervals bounded within plus or minus two to four percent.
Systematic parameter sensitivity analyses revealed critical operating thresholds governing reinforcement learning performance in disconnected mobile environments. Varying learning rate alpha and discount factor gamma demonstrated that an intermediate learning rate of 0.8 paired with a discount factor of 0.8 provided the optimal trade-off between rapid policy adaptation and long-term reward tracking without triggering erratic value oscillations. Protocol assessments across message time-to-live settings indicated that a 300-minute threshold achieved the peak message delivery success rate, beyond which extended holding times induced diminishing returns alongside increased resource consumption. Similarly, buffer size evaluations identified 100 megabytes as an optimal operational capacity; smaller buffers caused packet drops during sustained congestion, while capacities expanded beyond 100 megabytes failed to yield meaningful delivery improvements, validating the resource efficiency of the proposed learning framework.
Comparative simulation results confirmed the measurable performance superiority of the reinforcement learning protocols, with DQON consistently outperforming both RLON and the baseline methods. Flooding protocols like Epidemic generated the highest overhead across all mobility scenarios due to unconstrained replication, whereas DQON restricted message forwarding strictly according to balanced action values. Separating total network overhead into control signalling and data forwarding confirmed that while control overhead remained nearly identical between RLON and DQON due to shared signalling structures, DQON consistently lowered forwarding overhead by 12 percent to 18 percent compared to RLON and RLProph. Furthermore, in targeted baseline comparisons against alternative algorithms including SARSA and Dyna-Q under sparse mobility traces such as Reality and Sassy, DQON achieved 6 percent to 11 percent higher delivery probability than SARSA and 9 percent to 14 percent higher than Dyna-Q, while simultaneously reducing average latency by 8 percent to 15 percent.
Algorithmic complexity evaluations demonstrated the practical viability of deploying RLON and DQON on resource-constrained mobile and Internet of Things nodes. Because each tabular update requires constant time, both protocols maintain a computational complexity of O(1) per interaction step, with empirical CPU cycle measurements showing DQON consuming only 8 percent to 12 percent more processing cycles than RLON. In terms of physical memory, maintaining two separate Q-tables in DQON increases worst-case space complexity from O(N) to O(2N) relative to encountered neighbours; however, due to alternating update dynamics, actual memory utilization remains approximately 1.3 times that of RLON, avoiding storage bottlenecks on standard mobile hardware.
The researchers noted specific operational limitations inherent in tabular reinforcement learning for opportunistic networking. In extremely dense network environments where contact pools expand rapidly, storing distinct state-action values for every encountered peer increases local table dimensions, indicating that future protocol iterations could benefit from linear or neural function approximators to compress state representations. Additionally, because Q-tables remain uninitialized at deployment onset, early message forwarding decisions lack historical guidance; the authors suggest that bootstrapping early routing states using heuristic encounter metrics or social similarity scores could bridge performance gaps until nodes accumulate sufficient operational experience.
Subject of Research: Reinforcement learning protocols for opportunistic network routing
Article Title: Q-Learning and Double Q-Learning Based Routing in Opportunistic Networks
Article References: Gandhi, J., & Narmawala, Z. (2026). Q-Learning and Double Q-Learning Based Routing in Opportunistic Networks. International Journal of Networked and Distributed Computing, 14(1), Article 13. https://doi.org/10.1007/s44227-026-00090-7
Image Credits: AI Generated
DOI: 10.1007/s44227-026-00090-7
Keywords: opportunistic networks, reinforcement learning, Q-learning, Double Q-learning, RLON, DQON, delay tolerant networks, store carry forward, overestimation bias, ONE simulator, network routing protocols, delivery probability, overhead ratio, average latency, RLProph, mobile ad hoc networking
News Source: Denise Maddox. (November 19, 2026). Dual Reinforcement Learning Protocols Improve Message Delivery in Mobile Opportunistic Networks. Scienmag.