Researchers have engineered an advanced computer vision architecture known as SFMDet, specifically tailored to overcome the severe visual interference, extensive occlusion, and extreme scale variations inherent to dynamic construction environments. By integrating state-space scanning mechanisms, multi-scale cross-attention, directional partial convolutions, and task-specific prediction decoupling into the single-stage YOLOv12 network foundation, the system substantially advances detection precision across challenging work zones. In benchmark evaluations on an extensive dataset of actual construction operations, the detector achieved an overall mean average precision of 72.6 percent at an intersection over union threshold of 0.5, surpassing its standard baseline model by 4.3 percentage points while maintaining real-time processing capabilities on high-performance graphical hardware.
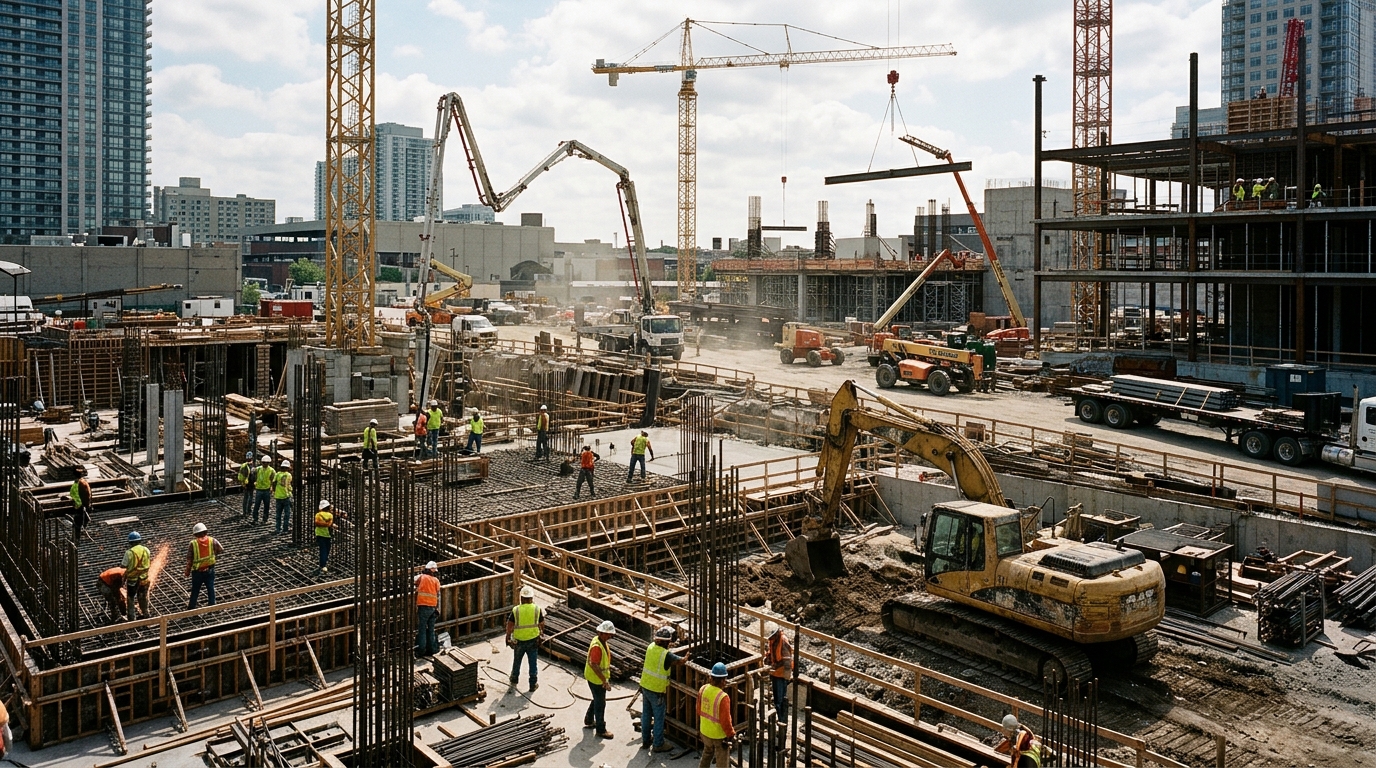
Operational construction sites represent uniquely difficult domains for autonomous image understanding systems due to the simultaneous coexistence of visually similar heavy machinery, intricate scaffolding, diverse raw building supplies, temporary housing facilities, and personal transport vehicles. Traditional deep learning frameworks frequently falter when deployed in these real-world industrial environments because fine-grained categories share overlapping silhouettes, such as differentiating box trucks, general freight haulers, and compact utility vans. Furthermore, physical dimensions within a single camera capture can span several orders of magnitude, ranging from diminutive discarded drainage pipes to massive multi-story structures, while severe physical occlusions and disordered visual backgrounds frequently confound both spatial bounding-box localization and category assignment.
To systematically address these failure modes, the researchers scrutinized three fundamental architectural bottlenecks that hinder standard single-stage and two-stage object detectors when applied to structural job sites. At the core representation stage, conventional convolutional neural network backbones rely on localized receptive fields, which fundamentally limits their ability to capture long-range spatial context required to disambiguate objects separated by wide visual expanses. At the feature aggregation level, standard feature pyramid networks execute shallow scale fusion through simple element-wise addition or channel concatenation, providing insufficient semantic cross-talk across disparate resolutions. Finally, coupled prediction heads force classification categories and spatial coordinate regression to share identical feature maps, generating severe task conflicts given that classification relies primarily on high-level semantic context while bounding box localization requires precise high-frequency physical boundaries.
The SFMDet architecture remedies these limitations through four coordinated structural modules strategically embedded throughout the network topology. In the deeper stages of the backbone network, precisely preceding the fourth and fifth area-attention convolutional blocks, the engineers introduced the Selective Feature Scanning module. Rather than passing all channels through dense global operators, this component applies layer normalization and splits the incoming feature map into main, guide, and auxiliary streams. The guide stream is routed through a two-dimensional selective scan mechanism based on state-space model formulations, unfolding spatial features along four complementary trajectories to aggregate broad contextual relationships with linear computational complexity, while the main and auxiliary pathways preserve essential localized details through depthwise convolutions.
At the structural junction connecting the feature-extracting backbone to the aggregation neck, the framework incorporates a dedicated Multi-level Cross-Attention Module to replace standard shallow fusion operations. This mechanism ingests feature representations across four distinct backbone hierarchical levels, spanning from fine-grained low-level maps to abstract high-level tensors. Each input map is reshaped, projected to a uniform internal channel width, flattened into token sequences, and concatenated along the sequence length. By formulating scale-specific query representations against unified key and value matrices, each spatial resolution directly extracts and assimilates complementary structural context from all other pyramid levels simultaneously, mediated by instance normalization and sigmoid gating mechanisms.
Because the simultaneous integration of global scanning and comprehensive cross-attention inevitably incurs computational overhead, the researchers designed Directional Partial Convolutions to replace select full-convolutional operations in the aggregation neck. Building upon the partial-channel concept wherein only a fraction of feature channels undergo convolutional processing, this operator isolates one-quarter of the incoming channels and subdivides them into four directional groups. Each group is processed via asymmetric one-by-three or three-by-one directional kernels configured with distinct spatial padding offsets to construct an effective cross-shaped receptive field. The resulting directional features are subsequently concatenated with the untouched three-quarters bypass stream and compressed through a final two-by-two convolution, substantially curtailing redundant floating-point calculations.
To eliminate representation interference at the prediction stage, the framework employs a Context-Aware Decoupling Module at all three output detection scales. The module normalizes incoming feature maps by subtracting global spatial averages to derive a dynamic context-aware scaling coefficient. Following non-linear activation, the modulated representations enter a multi-orientation spatial decomposition block that isolates spatial features across distinct frequency bands. The resulting low-frequency semantic representations are directed specifically to the classification branch, whereas the high-frequency edge and boundary details are routed toward bounding-box coordinate regression, ensuring neither sub-task degrades the feature quality demanded by the other.
Optimizing this composite framework required the formulation of a Hybrid Adaptive Loss function that dynamically coordinates disparate learning objectives over the course of training. The loss framework pairs Varifocal Loss for refined positive and negative sample classification with Wise-IoU version one and distribution focal loss for bounding-box boundary regression, while adding an explicit auxiliary regularization term that penalizes feature divergence between the selective scanning backbone and cross-attention neck.
Empirical validation was performed on an extensive construction scene dataset gathered across twelve operational sites in Henan Province, comprising 5,000 aerial and ground-level photographs encompassing 21,988 individually annotated objects across 49 distinct categories. Experimental benchmarking against twenty-three existing state-of-the-art detection systems established clear performance advantages. When compared against modern real-time models such as RT-DETR-R50 and MambaYOLO-s, the architecture demonstrated substantial improvements of 6.5 and 2.9 percentage points, respectively, with targeted super-category gains peaking in raw building materials and heavy construction machinery.
High-throughput hardware evaluation conducted on an NVIDIA RTX 4090 processor under TensorRT 16-bit floating-point precision demonstrated network-only inference speeds of 287 frames per second at standard 640-by-640 input resolutions, which translates to a compact forward latency of 3.48 milliseconds per frame. When incorporating real-world preprocessing, host-to-device data transfers, and non-maximum suppression decoding, end-to-end throughput registered at 233 frames per second.
Subject of Research: Computer vision architecture for object detection in construction scenes
Article Title: A selective feature scanning and context-aware decoupling framework for construction scene object detection
Article References: Wang, X., & Luo, X. (2026). A selective feature scanning and context-aware decoupling framework for construction scene object detection. Discover Computing, 29(1), Article 858. https://doi.org/10.1007/s10791-026-10799-2
Image Credits: AI Generated
DOI: 10.1007/s10791-026-10799-2
Keywords: Computer Vision, Object Detection, Deep Learning, Construction Safety, YOLOv12, State Space Models, Artificial Intelligence, Pattern Recognition, selective, feature, scanning, context-aware
News Source: Blake Davidson. (November 6, 2026). Novel Architecture Enhances Computer Vision for Complex Construction Site Object Detection. Scienmag.