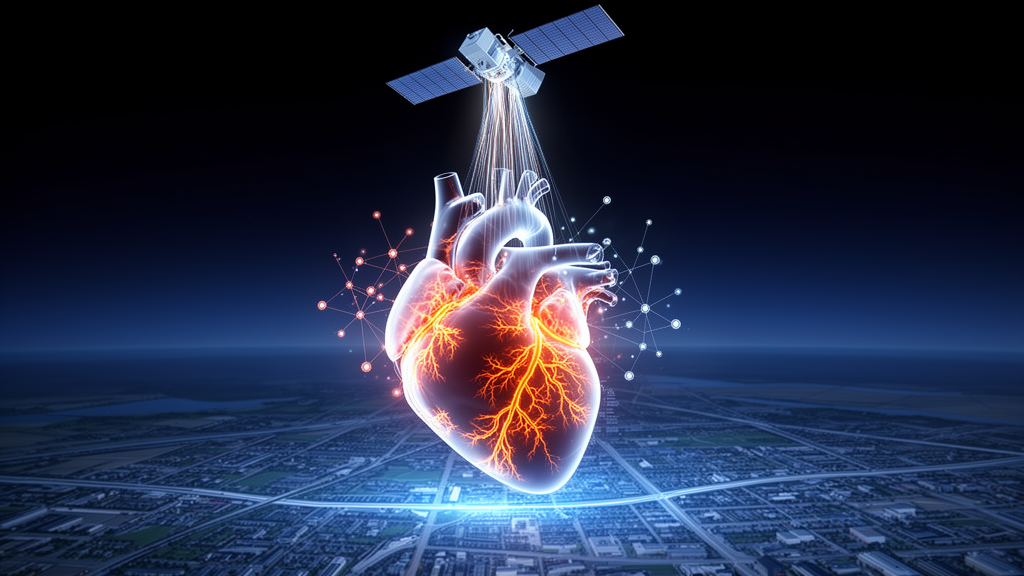
Cardiovascular disease kills an estimated 18 million people each year, roughly a third of all deaths worldwide, yet most risk prediction models still rely almost exclusively on clinical variables such as age, blood pressure, cholesterol and smoking status. A new open-access study published in Discover Artificial Intelligence on 28 August 2026 proposes a different approach: a Hybrid Explainable Artificial Intelligence and Machine Learning framework, abbreviated HXAI-ML, that predicts cardiovascular risk at the level of entire communities by fusing health data with satellite-derived environmental measurements. The work, led by Ismail Hossain, Kazi Md. Tanvir Anzum and Jarin Tasnim Mumu, was designed for area-level risk assessment rather than individual diagnosis.
The dataset at the heart of the study was assembled by merging two heterogeneous sources. The SatHealth dataset supplied satellite-based environmental variables, including air quality, weather conditions, land surface attributes and water-related features, aggregated as area-weighted annual averages. To capture the cumulative effects of long-term exposure, the researchers also constructed three-year lagged variables using rolling three-year windows. From the Ohio dataset they extracted records coded under ICD-099, the diagnostic code family for cardiovascular diseases. After removing records with incomplete geographic identifiers or missing environmental or health information, the final dataset contained 329 CBSA-year observations described by 80 attributes. Each observation was labeled as either Safe or Risk according to area-specific cardiovascular thresholds, producing an imbalanced distribution of 109 Safe cases and 220 Risk cases.
Class imbalance is one of the most persistent technical problems in medical machine learning, because models trained on skewed data tend to favor the majority class and neglect the minority cases that often matter most. The authors confronted this challenge systematically, evaluating seven resampling strategies: Random Oversampling, which duplicates existing minority examples; SMOTE, the Synthetic Minority Over-sampling Technique, which generates new synthetic samples along line segments between neighboring minority instances; Tomek Links, which removes pairs of nearest neighbors belonging to different classes to clean the class boundary; Instance Hardness Threshold, which discards majority samples that a model would likely misclassify; and three hybrid combinations of these methods. Crucially, all balancing was performed only on the training data after an 80:20 train-test split, leaving the test set untouched to prevent information leakage.
On top of the balanced data, the team trained five ensemble classifiers: Decision Tree, Random Forest, Extra Trees, Gradient Boosting and Extreme Gradient Boosting, commonly known as XGBoost. Preprocessing included median imputation of missing values, which is less sensitive to skewed distributions than mean imputation, standardization with a Standard Scaler fitted only on training data, and conservative correlation-based filtering that removed one feature from any pair with an absolute Pearson correlation above 0.95. The best-performing configuration combined SMOTE with XGBoost, whose hyperparameters were set to 600 estimators, a maximum tree depth of 3, a learning rate of 0.05, a subsampling rate of 0.8 and a column sampling rate of 0.7, with isotonic regression used for probability calibration and the decision threshold tuned between 0.30 and 0.70 to maximize the F1-score.
The results were striking. The SMOTE-plus-XGBoost model achieved 95.45 percent accuracy, 97.67 percent precision, 95.45 percent recall and a 96.55 percent F1-score on the held-out test set. Agreement metrics reinforced the picture of balanced classification, with Cohen’s Kappa reaching 89.89 percent and the Matthews Correlation Coefficient 89.94 percent, while the model recorded the lowest error rates among all tested configurations, with MAE and MSE of 4.55 percent and an RMSE of 21.32 percent. The confusion matrix showed 42 Risk regions correctly identified with only 2 misclassified as Safe, and 21 Safe regions correctly identified with only 1 misclassified as Risk, a balance that matters greatly in public health, where false negatives could cause high-burden areas to be overlooked. By comparison, a Decision Tree trained without balancing performed worst, and Random Forest and Gradient Boosting without resampling landed in between, underscoring how much the resampling step contributed: SMOTE alone lifted accuracy from 86.70 percent to 95.45 percent and MCC from 71.41 percent to 89.94 percent.
Stability was assessed with 5-fold stratified cross-validation, in which all preprocessing steps, including imputation, filtering, balancing, standardization, calibration and threshold optimization, were repeated independently within each fold. The framework averaged 93.31 plus or minus 2.26 percent accuracy, 95.24 plus or minus 1.48 percent ROC-AUC and 95.03 plus or minus 1.73 percent F1-score across folds, with the relatively small standard deviations indicating consistent performance across different data partitions. Against a conventional logistic regression baseline, which achieved the highest ROC-AUC at 98.70 percent but only 87.69 percent accuracy, the SMOTE-plus-XGBoost configuration offered a stronger overall balance of discrimination, classification accuracy and reliability. Computational efficiency was another advantage: XGBoost trained in 0.563 seconds and predicted in 0.004 seconds, whereas Gradient Boosting required more than 5 seconds in total.
What distinguishes the framework from many high-performing but opaque models is its explainability layer. The researchers applied three complementary techniques: SHAP, or Shapley Additive Explanations, a game-theoretic method that quantifies each feature’s contribution to predictions; LIME, which approximates the complex model locally with a simpler interpretable one to explain individual predictions; and Permutation Importance Analysis, which measures how much model performance drops when a feature’s values are randomly shuffled. From the original 80 variables, the team focused on the 17 most influential features identified by mean absolute SHAP values and permutation scores.
The three methods converged on a consistent set of environmental drivers, with atmospheric and hydrological variables dominating the predictive structure. Among the most influential predictors were bare-coverfraction, lake_total_layer_temperature_1yr and water-seasonal-coverfraction, suggesting that land surface exposure, reduced vegetation cover and surface water thermal dynamics carry substantial predictive weight. The global SHAP analysis showed that higher values of dewpoint temperature, lake temperature and seasonal water coverage were positively associated with Risk predictions, while lower values aligned with the Safe class, and multi-year temperature features contributed more strongly than short-term ones, hinting at cumulative exposure effects. A local LIME explanation for one high-risk CBSA revealed that reservoir content, runoff, soil moisture and precipitation increased the predicted probability of risk for that region, while snow density, radiation flux and certain temperature-layer variables pushed in the opposite direction. The authors are careful to stress that these feature contributions represent statistical associations learned by the model, not evidence of direct causal relationships between environmental conditions and cardiovascular disease.
Previous research cited in the paper links urban vegetation to lower rates of ischemic heart disease, stroke, hypertension and diabetes, and associates pollutants such as PM2.5 and nitrogen dioxide with elevated blood pressure and cardiovascular events, providing context for why satellite-derived environmental features might carry predictive signal. The authors are candid about the study’s limitations. The final dataset contains only 329 CBSA-level observations, which may limit generalizability, and the aggregated regional data mask individual patient variation; the model predicts area-level risk, not individual risk. The framework used only classical ensemble methods rather than deep learning architectures, and it did not explore transformer-based or spatial deep learning designs that might better capture environmental exposure trends over time and space. Performance may also vary across regions with different climates, healthcare systems and population characteristics, and real-world deployment would require regularly updated satellite data and standardized regional health records.
Future work, the team says, will explore deep learning approaches, richer multimodal data integration and external validation across multiple regions. Even with these caveats, the study offers a concrete demonstration that explainable machine learning, careful attention to class imbalance and satellite environmental data can be combined into a single, interpretable pipeline for population-scale cardiovascular risk monitoring, potentially supporting health officials in targeting prevention efforts toward the communities that need them most.
Subject of Research: Explainable machine learning prediction of area-level cardiovascular disease risk using satellite-derived environmental data
Article Title: Hybrid explainable machine learning for population level cardiovascular disease risk prediction using satellite environmental data
Article References: Hossain, I., Anzum, K. M. T., & Mumu, J. T. (2026). Hybrid explainable machine learning for population level cardiovascular disease risk prediction using satellite environmental data. Discover Artificial Intelligence, 6(1), Article 945. https://doi.org/10.1007/s44163-026-02061-x
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02061-x
Keywords: cardiovascular disease, machine learning, explainable AI, satellite data, SMOTE, XGBoost, public health, environmental health, SHAP, LIME, risk prediction, class imbalance
News Source: Frances Kline. (October 28, 2026). Satellite Data and Explainable AI Predict Regional Heart Disease Risk. Scienmag.