Suicide claims more than 700,000 lives every year and stands among the leading causes of death in young adults, yet the tools clinicians rely on to catch it early have barely changed. Self-report questionnaires and structured interviews remain the backbone of suicide-risk screening, but they share a stubborn weakness: they depend on what a person is willing to say. Underreporting, social desirability, stigma, and plain subjectivity can all blur the picture, which is why researchers have long sought objective, scalable ways to measure the risk that a patient may not put into words. Now, a team has built an artificial intelligence framework that does something unusually ambitious in this field: it reads brainwaves and spoken language from the same person, at the same clinical visit, and fuses them into a single risk assessment.
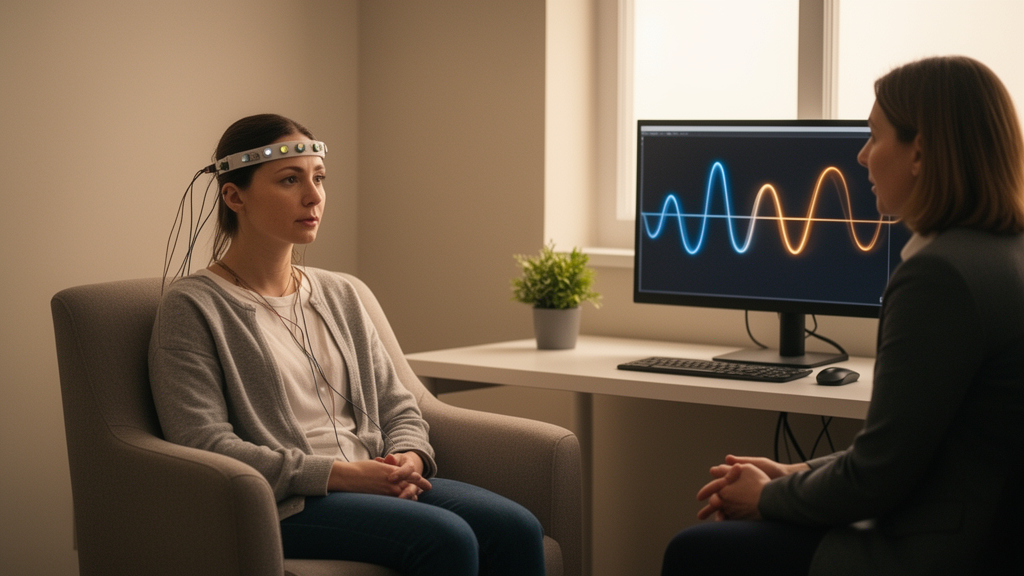
The study, framed explicitly as a controlled proof-of-concept, collected a genuinely paired multimodal dataset from 520 participants recruited between February and September 2024 at the Ticoman Psychology Clinic and the Centro de Investigación en Computación of the Instituto Politécnico Nacional in Mexico. Each participant, aged 18 to 65 and evenly split between 260 males and 260 females, completed a single synchronized assessment session. That session included ten minutes of resting-state EEG, five with eyes open and five with eyes closed, recorded on a 64-channel Brain Products actiCHamp Plus system sampled at 500 Hz, followed by a semi-structured clinical interview lasting 25 to 40 minutes that was audio-recorded and transcribed with Whisper large-v3 and verified manually by two independent annotators. Standardized instruments, including the Columbia-Suicide Severity Rating Scale, the PHQ-9, the BDI-II, the GAD-7, and the MINI diagnostic interview, rounded out the record.
Ground-truth labels were not left to a single clinician. A multidisciplinary team of two board-certified psychiatrists and one clinical psychologist, each with more than five years of experience, independently assigned a five-level suicide-risk category to every participant, resolving disagreements by consensus. Their inter-rater agreement, quantified with Fleiss’ kappa, reached 0.88, a level the authors describe as strong. The resulting cohort spanned the full severity spectrum, from 120 participants with no suicidal ideation to 80 classified as imminent risk, with the remaining 320 distributed across low, moderate, and high categories. Because EEG, transcripts, and labels all come from the same individual within the same temporal window, the design eliminates the artificial cross-subject pairing that has weakened many earlier multimodal attempts in psychiatric AI.
The architecture itself is a hybrid of established building blocks arranged around a novel neuro-semantic fusion core. On the EEG side, three complementary encoders process the signals in parallel: a Temporal Convolutional Transformer that captures both fast cortical oscillations and long-range temporal dependencies through dilated convolutions, a Graph Attention Network v2 that treats electrodes as nodes and functional connections as edges to model cortical connectivity, and a Vision Transformer that reads time-frequency spectrograms as image patches to extract spectral-spatial patterns. A Mixture-of-Experts layer adaptively weighs the three branches, so the model can lean on whichever encoder is most informative for a given recording. On the language side, ClinicalBERT and RoBERTa-large with LoRA fine-tuning process the interview transcripts, enriched with 128-dimensional symbolic embeddings derived from DSM-5 ontology and suicide-related lexicons, allowing the model to reason over clinically meaningful constructs like hopelessness, self-devaluation, and social withdrawal rather than surface keywords alone.
What binds the two modalities together is the framework’s central methodological contribution. Contrastive Language-EEG Pretraining, or CLEP, pulls the embeddings of a participant’s own EEG and transcript toward each other in a shared latent space while pushing apart mismatched pairs, teaching the model which neural patterns co-occur with which semantic content. Domain-adversarial regularization with a gradient-reversal discriminator then aligns the two embedding distributions so that representations remain informative across data domains. Finally, a hypernetwork-driven fusion module computes dynamic weighting coefficients based on each modality’s estimated uncertainty and signal complexity, meaning the model can shift its trust between brain and language from person to person. A multi-task transformer decoder produces both a binary ideation prediction and an ordinal severity estimate, while Monte Carlo dropout supplies confidence-aware uncertainty quantification for every output.
Under strict subject-independent splitting, with zero participant overlap between training, validation, and test partitions, the framework reported an overall accuracy of 99.97 percent, a Macro-F1 of 99.93 percent, and a quadratic weighted kappa of 0.991 on the held-out clinical test set of 104 participants. Repeated ten-fold cross-validation, run ten times to yield 100 fold-level evaluations, produced a mean accuracy of 99.91 percent with a standard deviation of just 0.04. The authors are careful to treat these near-ceiling numbers as an upper-bound estimate under controlled paired conditions rather than expected real-world performance, and they subjected the result to an unusually thorough battery of leakage checks. Pairwise cosine similarity between training and test EEG embeddings peaked at 0.21, far below the 0.85 duplication threshold; recording durations and transcript lengths showed no significant association with risk labels; a deliberately leaky synthetic experiment showed that subject overlap would inflate a simplified baseline from 88.7 to 96.5 percent, demonstrating that the evaluation protocol is sensitive to the very mechanism the team sought to rule out.
Robustness testing pushed the model well beyond its home cohort. On DAIC-WOZ, a public multimodal interview corpus, the framework achieved 99.72 percent accuracy out of distribution, and on a cross-corpus setting pairing DEAP and AMIGOS emotion EEG with CLPsych online suicide-related text at the class level, it reached 98.99 percent. The authors stress that these external benchmarks, which also include the TUH EEG corpus, PhysioNet motor-imagery data, and Reddit social-media posts, were not collected for suicide-risk assessment and lack native clinical labels, so their results are interpreted as distribution-shift stress tests of representation robustness, not as independent clinical validation. Within the clinical cohort itself, the model stayed above 99.1 percent accuracy under Gaussian EEG noise, ten percent channel dropout, temporal misalignment of up to 50 milliseconds, and ten percent random word deletion from transcripts. Injecting five percent random label noise reduced in-distribution accuracy to 96.3 percent, a result the team reads as evidence that performance depends materially on label fidelity rather than on overfitting to spurious correlations.
The explainability analyses, reported as exploratory and associational, offer some of the study’s most intriguing technical findings. Modality-level relevance estimates assigned 61.2 percent of total feature importance to EEG, 38.1 percent to text, and 0.7 percent to global cross-modal interaction. Within the neural stream, LRP and DeepLIFT independently converged on frontal and bilateral temporal theta and alpha activity as dominant contributors for the two highest risk categories, with frontal-theta relevance of 0.74 from DeepLIFT against 0.71 from LRP and an electrode-level correlation of 0.87 between the two methods. Cross-modal attention consistently aligned left-frontal electrodes such as F3 and Fp1, along with temporal nodes T3 and T4, with ideation-related language, and attention weights peaked at 0.82 for high-risk and imminent-risk cases against 0.43 for low-risk controls. On the language side, token-level attribution ranked ideation and hopelessness terms as top-weighted with a mean relevance of 0.83, and DSM-5 semantic clusters accounted for 41.3 percent of textual relevance. Counterfactual masking confirmed attribution faithfulness: removing the five top tokens cut high-risk logits by 26.4 percent, attenuating frontal theta by 30 percent lowered logits by 18.7 percent, and stripping both modalities’ top ten percent of features dropped model confidence by 38.5 percent.
Ablation studies quantified how much each component matters. Removing the contrastive alignment produced the largest single-module decrement, a 1.56-point drop in Macro-F1, followed closely by the domain-adversarial module at 1.44 points, while stripping out all three EEG encoders reduced accuracy to 96.2 percent. The high post-ablation scores also reveal substantial redundancy among branches, a finding the authors present candidly. Against within-study baselines, the full framework outperformed text-only RoBERTa, EEG-only encoders, early concatenation, transformer late fusion, cross-modal attention networks, and hypernetwork-only fusion, with McNemar’s test on paired predictions yielding p-values below 0.001 for the in-distribution comparisons. The team emphasizes that comparisons with prior studies in the broader literature are contextual rather than head-to-head, since tasks, cohorts, and label definitions differ so widely across the field.
The path from proof-of-concept to clinic remains long, and the authors are unusually explicit about it. The cohort was Spanish-speaking and drawn from two named sites in Mexico, and the analysis does not fully control for psychotropic medication exposure, psychiatric comorbidity burden, or longitudinal substance-use history, all of which can independently shape both EEG and language. The study is cross-sectional, with labels assigned at the index assessment, so it says nothing about whether deployment would improve clinician performance, reduce false negatives, or change patient outcomes. No automated clinical decisions were made from model outputs, and the framework’s roughly 182 million parameters, of which about 23 million are trainable through parameter-efficient adaptation, run in about five milliseconds per EEG window on an A100 GPU, a timing that excludes all preprocessing. What the work does establish is that genuinely paired brain and language data can support neuro-semantic modeling with strong calibration, external robustness, and physiologically plausible explanations, and that the next step, independent prospective multi-site validation with richer confounder characterization, is now clearly defined.
Subject of Research: Multimodal neuro-symbolic AI framework for suicide risk detection using paired EEG and clinical interview data
Article Title: Explainable neuro-symbolic multimodal framework for suicide risk detection using genuinely paired clinical EEG and interview data
Article References: Abdullah, Ather, M. A., Fatima, Z., & Sidorov, G. (2026). Explainable neuro-symbolic multimodal framework for suicide risk detection using genuinely paired clinical EEG and interview data. Results in Engineering, 32, Article 113077. https://doi.org/10.1016/j.rineng.2026.113077
Image Credits: AI Generated
DOI: 10.1016/j.rineng.2026.113077
Keywords: suicide risk detection, EEG, clinical interviews, multimodal AI, neuro-symbolic framework, ClinicalBERT, contrastive learning, explainability, proof-of-concept, psychiatric AI, Explainable, neuro-symbolic
News Source: Glenn Wilkins. (October 25, 2026). AI reads brainwaves and speech together to flag suicide risk in clinical interviews. Scienmag.