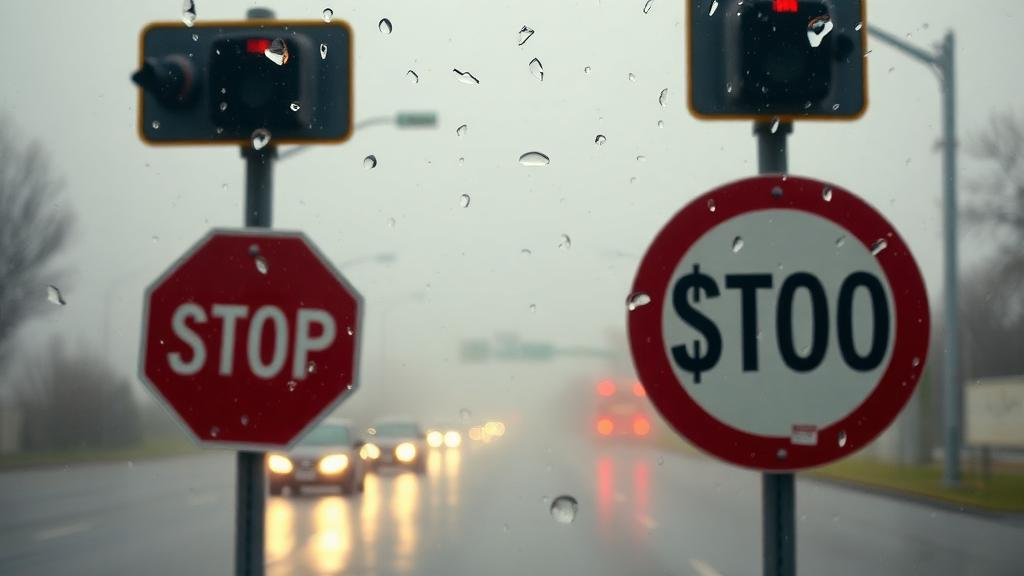
Traffic signs are the quiet workhorses of road safety, but for the vision-language models that autonomous vehicles increasingly rely on, a sign half-hidden behind a tree branch or smeared by driving rain can become nearly meaningless. A new study published in Discover Artificial Intelligence by Ning Wang and Jian Qu tackles exactly this vulnerability, presenting a framework called OATA that lets a trained image-text matching model adapt itself to occluded images on the fly, without ever seeing the original training data or a single labeled example of the corruptions it must survive.
The problem the researchers set out to solve is deceptively simple to state and notoriously hard to engineer around. Image-text matching, or ITM, is the task of linking a picture to the right description from a pool of candidates, for example pairing a photograph of a speed-limit sign with its correct caption among thousands. In driving scenes this capability underpins retrieval-based perception, where a system might need to fetch the right instruction or category from a text database given what the camera sees. Weather, optical artifacts, and physical obstructions all push the input away from the clean distribution the model was trained on, and crash studies on visibility in fog and smoke show these degradations are not academic concerns but genuine safety issues.
The obvious fix, augmenting the training set with occluded samples and retraining, runs into two walls. First, collecting large numbers of severely occluded traffic-sign image-text pairs is costly and sometimes unsafe, since gathering such data on real roads can require closing lanes or entire test towns. Second, and more subtly, synthetic corruptions carry their own trap: a model retrained on artificial rain streaks or mask patterns may learn those artificial textures as shortcuts rather than the semantic cues that actually identify a sign. And even a perfectly augmented model can fail when the corruptions at test time differ in texture, geometry, or severity from those seen during training. The authors therefore turned to source-free test-time adaptation, a paradigm in which a deployed model adjusts to the distribution it currently faces, using no labels, no source data, and no fresh occlusion annotations.
OATA works in two carefully separated stages. The first stage borrows TENT, a well-known test-time adaptation method that minimizes prediction entropy on incoming batches while updating only a tiny slice of the network: the BatchNorm scale and shift parameters in the image encoder. The intuition is that occlusion shifts the global feature statistics of the visual input, and recalibrating normalization parameters can correct that shift cheaply and safely. Crucially, the text encoder stays completely frozen, because the synthetic occlusions alter only the images while the candidate captions remain unchanged. Limiting the update to a handful of parameters also reduces the risk of destroying the cross-modal alignment learned during source training, which is the model’s most valuable asset.
But BatchNorm adaptation alone cannot verify whether the visible sliver of a sign actually corresponds to particular words, and entropy minimization rests on an assumption that severe or ambiguous occlusion can violate: that more confident predictions are more accurate. That is where the second stage comes in. After TENT has recalibrated the features, a lightweight image-text pair reranker, implemented as a two-layer multilayer perceptron, re-examines only the top five candidates returned by the dual encoder. For each candidate pair it takes the image embedding, the text embedding, their absolute difference, and their element-wise product, and produces a learned matching score that reorders the shortlist. This division of labor mirrors the classic retrieve-then-rerank architecture from text search, but applied at a fraction of the cost of running a full transformer cross-encoder over every pair in the pool.
The evaluation was built on a traffic-sign dataset of 190 sign types, 15,120 images, and 30,240 captions, with each image paired with two natural-language descriptions and signs captured from varied road locations and viewing angles. The authors constructed a controlled synthetic occlusion benchmark by overlaying six corruption categories on the test images: rain, snow, fog, fire-like artifacts, light glare, and tree branches, each at light, medium, and strong severity, yielding eighteen stress subsets. The main test pool contained 1,512 images and 3,024 captions, and the protocol counted every caption of a query image as a valid match, evaluating retrieval in both directions. The image encoder was a ResNeXt-32x4d, the text encoder DistilBERT-base, and both were projected into a shared 512-dimensional alignment space, with experiments run on a single NVIDIA GeForce RTX 3080 Ti.
The headline numbers show a framework that refines an already strong baseline rather than rescuing a broken one. Under the dataset-level protocol, full OATA achieved 96.69 percent image-to-text Recall@1 and 96.43 percent text-to-image Recall@1, with Recall@5 and Recall@10 saturated at 99.87 percent across all variants. The pair reranker lifted image-to-text top-rank accuracy from 96.43 to 96.69 percent, while text-to-image performance stayed essentially flat. The per-occlusion stress analysis revealed where adaptation matters most: TENT produced its largest Recall@1 gains under strong rain and medium rain, at 48.35 and 44.31 percentage points respectively, though fire-like medium occlusion was an exception where performance actually dipped slightly by 1.88 points.
Visualization experiments added mechanistic color to the results. Grad-CAM heatmaps showed that before adaptation, the model’s attention was often scattered across high-frequency occlusion regions such as raindrops, glare, and fire-like textures, whereas after TENT the attention migrated back toward semantically meaningful sign regions like borders, arrows, and visible symbol structures. A t-SNE analysis showed feature distributions that were scattered across occlusion types before adaptation becoming more compact and separable afterward, supporting the picture of TENT as a coarse feature-statistic corrector. In qualitative case studies, OATA without the reranker corrected 12 baseline errors and full OATA corrected 18, though the pipeline also flipped some correct predictions, and it cannot recover a valid caption that falls outside the initial top-five list, a hard boundary the authors are explicit about.
The study is candid about its limits, which is part of what makes it useful. The synthetic occlusions, while resembling real degradations, do not capture motion blur, camera exposure dynamics, sensor failure, temporal context, or physically accurate fire and fog behavior. An auxiliary experiment on Flickr30k, with a much larger pool of 11,070 captions, showed only modest recovery from occlusion, and a supplementary test with CLIP ViT-B/32 highlighted a structural constraint: CLIP uses LayerNorm rather than BatchNorm, so TENT cannot be applied to it directly. The authors also stress that OATA is an image-text retrieval component, not an autonomous-driving system, and that deployment would require testing on real driving video with bounded latency, explicit failure checks, and integration with planning and control. The computational cost is nontrivial too: 20 adaptation steps took just over 61 minutes for the full 1,512-image stream, though the reranking itself added only about 2.23 seconds.
What the work ultimately offers is a template for a class of problem that will only grow as vision-language models move into safety-critical settings: adapting deployed multimodal systems to distribution shifts they were never trained on, without access to the data that shaped them. By pairing a minimal, surgical adaptation mechanism with a cheap candidate-level verification step, and by publishing a reproducible evaluation protocol with six occlusion types at three severities, Wang and Qu have given future robustness research a concrete benchmark to build on. The gains are modest in absolute terms because the baseline was already near saturation, but the architecture of the solution, feature correction first, pairwise verification second, may prove more durable than any single number in the results tables.
Subject of Research: Occlusion-robust test-time adaptation for traffic-sign image-text retrieval in autonomous driving
Article Title: Occlusion-aware test-time adaptation for robust traffic sign image-text matching
Article References: Occlusion-aware test-time adaptation for robust traffic sign image-text matching. (n.d.). https://doi.org/10.1007/s44163-026-02399-2
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02399-2
Keywords: test-time adaptation, traffic signs, image-text matching, occlusion robustness, autonomous driving, TENT, entropy minimization, reranking, vision-language models, BatchNorm, synthetic occlusion, retrieval
News Source: Denise Maddox. (October 12, 2026). AI Learns to Read Traffic Signs Through Rain, Fog and Glare Without Retraining. Scienmag.