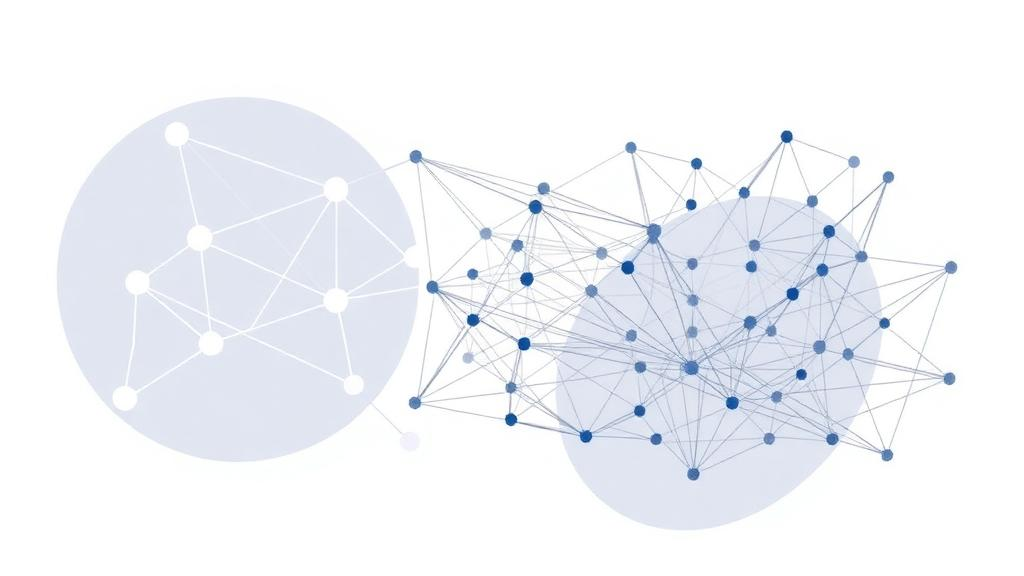
Every time a person signs up for a new social platform, a fragment of their identity is duplicated into a different network. The same individual may appear as a node in a microblogging service, a movie-rating community and a professional forum, yet the platforms rarely advertise that these accounts belong to one person. The task of discovering such hidden correspondences, known as anchor link prediction, has become one of the most consequential problems in data mining: it underpins cross-platform recommendation, user profiling and the fusion of knowledge scattered across separate networks. A team of researchers led by Qiming Yang and Wei Wei of Beihang University, together with collaborators at Hengshui University and the Complexity Science Hub Vienna, now reports a new unsupervised approach that promises to make this matching process markedly more accurate and more resilient when networks are noisy or sparse.
The work, published in the journal Data Mining and Knowledge Discovery, is titled IGA: isomorphism-aware graph alignment for robust unsupervised anchor link prediction. Its central insight is deceptively simple. Most existing unsupervised alignment methods treat the two networks they compare as raw collections of nodes and edges, learning embeddings from whatever structure is directly observable. What they tend to ignore is that different networks are generated by different processes, and that these generative processes only partially overlap. Where they do overlap, the networks contain regions that reflect shared structural information: stable backbone components that are consistently observed on both sides. IGA, short for Isomorphism-aware Graph Alignment, is built around the assumption that identifying and aligning these backbones is the key to reliable matching without any labelled anchor links.
To understand why this matters, it helps to consider what makes unsupervised anchor link prediction so difficult. Supervised methods can be trained on known correspondences between accounts, but in realistic scenarios such supervision is scarce or absent altogether. Unsupervised methods must instead decide, purely from structure and attributes, which node in one network corresponds to which node in another. This is a cousin of the notorious graph isomorphism problem, which asks whether two networks are structurally identical up to a relabelling of nodes. Classical tools for probing this question date back to the Weisfeiler-Lehman test, a relabelling procedure introduced in 1968 that iteratively refines node labels by hashing together each node’s own label with the multiset of labels held by its neighbours. If two graphs are isomorphic, the procedure assigns identical labels to corresponding nodes, a property the authors prove formally by induction in the paper’s appendix.
IGA translates this classical idea into the language of modern deep learning through the Graph Isomorphism Network, or GIN. The GIN architecture, introduced by Keyulu Xu and colleagues in 2019, is provably as powerful as the Weisfeiler-Lehman test in distinguishing graph structures. Its update rule mirrors the relabelling procedure: each node’s embedding at the next layer is produced by a multilayer perceptron applied to a weighted combination of the node’s current embedding, scaled by a learnable constant epsilon, and the sum of its neighbours’ embeddings. In effect, GIN replaces the non-learnable hash function of the classical test with a trainable neural network, allowing gradient-based optimisation while retaining the theoretical expressive power that makes the test so effective at telling structurally different nodes apart.
The authors go one step further by enriching the initialisation. In the standard setting, the Weisfeiler-Lehman test starts every node with the same label, or with a label derived only from its degree, which limits its ability to separate nodes that look structurally alike. The paper’s first lemma shows that initialising the relabelling process with node-specific feature vectors increases its discriminative power within a single graph: if two nodes carry different features, they receive different colours from the outset, and even nodes with identical computational-graph topology can then be distinguished through the iterative hashing. Because GIN consumes these features as initial embeddings, the same benefit carries over, giving the network a learnable, expressive and theoretically grounded alternative to the classical procedure. The team proves that if two nodes in the source and target networks share isomorphic neighbourhoods and identical features under recursive matching, their embeddings remain equal at every layer of a shared GIN, which is precisely the property an alignment method needs.
Training such a model unsupervised, however, hides a subtle trap that the authors expose in one of the paper’s most striking results. A natural way to learn embeddings without labels is to reconstruct the adjacency matrix, pushing the embeddings of connected nodes towards a dot product of one. The team shows that this recipe manufactures what are known as hard negatives. If two nodes v and u are connected in the source graph and the reconstruction is trained properly, their normalised embeddings converge to the same vector. Now suppose v has a true counterpart v’ in the target network. Because the embeddings of v and u are identical, the alignment score between u and v’ equals the score between v and v’, and the alignment process can no longer tell which of the two is the genuine match. The very nodes that helped train the model become indistinguishable competitors in the downstream task.
The remedy proposed in the paper is elegant: change the reconstruction target. Instead of the adjacency matrix, IGA reconstructs the normalised Laplacian, whose off-diagonal entries for connected nodes equal minus one over the square root of the product of their degrees. Trained against this target, connected nodes acquire embeddings whose cosine similarity is negative, meaning they spread apart in the embedding space rather than collapsing onto one another. The paper’s second lemma demonstrates that this choice mitigates the formation of hard negatives and thereby protects the quality of the downstream alignment. It is a reminder that in unsupervised graph learning, the choice of what to reconstruct can matter as much as the architecture used to reconstruct it.
On top of this backbone-alignment machinery, IGA introduces a refinement strategy that adaptively augments both structural and semantic information as training proceeds, improving the quality of the alignment. The overall learning principle is one of consistency and disparity: embeddings of corresponding backbone nodes should agree across networks, while non-corresponding structures should be pushed apart. This echoes a broader line of research on balancing consistency and disparity in network alignment, but here it is anchored in the isomorphism-aware guarantees of the GIN encoder, giving the method a firmer theoretical footing than purely heuristic competitors.
The empirical evaluation spans real-world benchmarks of genuinely different kinds. One pair of networks comes from Douban, a Chinese social platform, aligning its online and offline friendship graphs through 1,118 anchor links. Another pair aligns Allmovie and IMDb movie networks, in which two films are connected if they share at least one actor, with 5,176 anchor links based on film identity. The team also evaluates on the Cora and Citeseer citation networks, containing 2,708 papers with 5,278 citation links and 3,312 papers with 4,732 citation links respectively. For controlled stress tests, synthetic source and target networks are generated by randomly removing a percentage of edges from the originals, introducing structural noise while keeping node identity unchanged, and all node features are compressed to twenty dimensions via truncated singular value decomposition. Across these benchmarks, the authors report that IGA consistently outperforms existing unsupervised methods in both accuracy and robustness, with its advantages most pronounced under the noisy and sparse conditions that realistically mirror how partial, imperfect network data arrive in practice.
The implications reach well beyond social media. Network alignment has a long history in computational biology, where aligning protein interaction networks across species helps transfer functional knowledge between organisms, and the same mathematics surfaces in ontology matching and anonymised social network analysis, where it raises pointed privacy questions about how much structure alone can reveal. By showing that a theoretically grounded, isomorphism-aware encoder can deliver robust unsupervised alignment without a single labelled example, the Beihang-led team offers a template that other domains grappling with mismatched, incomplete networks may soon adopt. As people continue to fragment their digital lives across ever more platforms, methods that can stitch those fragments back together from structure alone are likely to become indispensable infrastructure for the web’s next decade.
Subject of Research: Unsupervised anchor link prediction across social networks using isomorphism-aware graph neural network alignment
Article Title: IGA: isomorphism-aware graph alignment for robust unsupervised anchor link prediction
Article References: Yang, Q., Wei, W., Zhang, R., Lv, Y., Li, C., & Feng, X. (2026). IGA: isomorphism-aware graph alignment for robust unsupervised anchor link prediction. Data Mining and Knowledge Discovery, 40(6), Article 111. https://doi.org/10.1007/s10618-026-01277-w
Image Credits: AI Generated
DOI: 10.1007/s10618-026-01277-w
Keywords: anchor link prediction, graph alignment, graph neural networks, unsupervised learning, Weisfeiler-Lehman test, Graph Isomorphism Network, network embedding, social networks, data mining, hard negatives, structural noise, cross-platform user matching
News Source: Denise Maddox. (October 5, 2026). New Graph Alignment Method Matches Users Across Networks Without Any Labelled Data. Scienmag.