In an agricultural phenotyping study evaluating seven fenugreek genotypes, researchers demonstrated that tabular machine-learning algorithms combining digital image measurements with physical seed dimensions successfully discriminated among seed lots, whereas full-frame deep convolutional neural networks derived substantial predictive cues from imaging backgrounds rather than seed morphology alone. The investigation, carried out by Sevim Akcura and Mahmut Kaplan using seed material grown in Kayseri, Türkiye, addressed persistent methodological challenges in digital seed classification, where data leakage, pseudoreplication, and imaging artifacts frequently compromise the biological validity of automated phenotyping pipelines.
Fenugreek, scientifically designated as Trigonella foenum-graecum L., serves globally as a multipurpose legume across food, feed, nutraceutical, and pharmaceutical industries. Its seeds house proteins, lipids, carbohydrates, dietary fibre fractions, and galactomannan, with natural variation among genetic strains influencing both agronomic utility and processing quality. Conventional seed characterization typically demands labor-intensive physical manual measurements or destructive chemical procedures that yield aggregate rather than individual seed-level profiles. While digital imaging provides a high-throughput, non-destructive alternative to capture external seed geometry, automated classification models often conflate intrinsic seed features with experimental artifacts when sampling hierarchies and imaging environments are not rigorously audited.
To evaluate these classification boundaries under leakage-safe conditions, the research team cultivated seven distinct fenugreek genotypes, designated TF1 through TF7, during the 2024 growing season under uniform field management arranged in a randomized block design with three field replications. Following harvest, seed yields from the three field replications were pooled and homogenized within each genotype before phenotyping. From each pooled lot, exactly 252 individual seeds were sampled without visual pre-screening, yielding an experimental cohort of 1,764 seeds. Because harvest replication identity was eliminated during homogenization, the individual seeds represented analytical subsamples rather than independent field-level biological replicates, a foundational distinction that shaped the study’s analytical design.
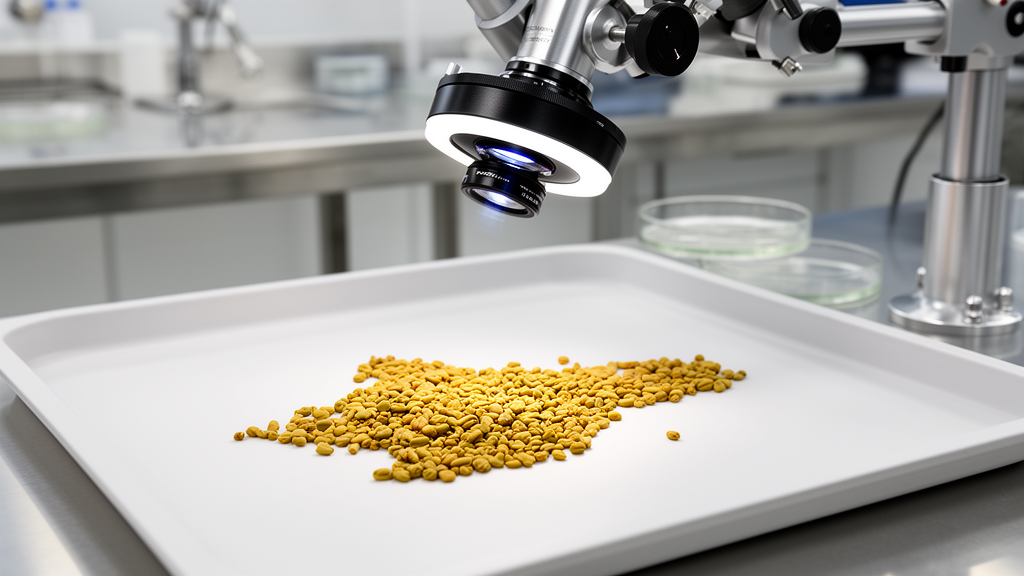
The phenotyping pipeline acquired individual seed mass and caliper-measured thickness alongside high-resolution flatbed scanner images captured at 1,200 dots per inch against a standardized dark background. All automated software image enhancements were disabled to maintain acquisition uniformity. The segmented image records furnished primary descriptors comprising seed area, perimeter, length, width, and normalized red, green, and blue color channels. From these values, mathematical routines derived additional shape indices including hue, roundness, elongation, aspect ratio, sphericity, geometric mean diameter, projected area, estimated volume, and surface area. In parallel, reference chemical analyses and near-infrared spectroscopy characterized bulk seed chemistry, but these aggregate determinations were deliberately maintained as a descriptive data layer and excluded from individual-seed classifier inputs to prevent pseudoreplication.
The full 1,764-seed dataset was divided using a single, locked genotype-stratified partition of 70 percent for training, 15 percent for validation, and 15 percent for held-out testing, corresponding to 1,232, 266, and 266 individual seeds, respectively. This split was locked prior to image augmentation, ensuring that augmented variations produced during deep learning training never crossed into validation or testing sets. The researchers subsequently benchmarked four tabular machine-learning algorithms on the validation set using three feature sets: an 11-feature set restricted to two-dimensional optical metrics, an expanded 19-feature set integrating physical and three-dimensional metrics, and a redundancy-controlled 15-feature set denoted as AB15.
On the redundancy-controlled AB15 validation subset, multilayer perceptron neural networks achieved a macro-averaged F1-score of 0.787, while support vector machines with radial basis functions achieved 0.765, outperforming random forests at 0.657 and classification trees at 0.614. Because the support vector machine classifier produced the highest mean macro F1-score across all evaluated feature representations during pre-test tuning, it was selected as the common model for locked test evaluation. On the locked test set, feature ablation confirmed that physical descriptors were critical: test macro F1-score rose from 0.449 under two-dimensional image traits alone to 0.886 when three-dimensional physical traits were added, reaching 0.894 and an accuracy of 0.895 under the AB15 representation.
Model interpretation techniques, including correlation-aware grouped permutation importance and Shapley Additive Explanations, confirmed that predictive performance in tabular models was primarily anchored by seed mass, thickness, and a collinear size-related cluster consisting of area, perimeter, length, and geometric mean diameter. Meanwhile, four deep convolutional neural network architectures—DenseNet121, ResNet50, InceptionResNetV2, and Xception—were trained on full-frame seed images under an identical data split. In locked test evaluations, DenseNet121 attained the highest full-image classification performance with a macro F1-score of 0.708 and an accuracy of 0.714, operating with a compact computational footprint of 7.17 million parameters and 9.93 single-image inference gigaflops, whereas ResNet50 reached an F1-score of 0.660.
Despite apparent success on full-frame imagery, diagnostic perturbations revealed that deep convolutional networks relied heavily on contextual background information. When researchers applied counterfactual background swaps—replacing a seed’s original scanner background with real background pixels sampled from images of different genotypes while holding seed appearance and position constant—model performance dropped precipitously across all architectures, with predictions actively shifting toward the background donor genotype. Gradient-weighted class activation mapping confirmed non-zero gradient attention over seeds, but an independently trained DenseNet121 model restricted exclusively to segmented seed regions of interest achieved a locked test macro F1-score of only 0.491, demonstrating that intrinsic visual appearance accounted for only part of full-frame deep learning predictions.
The study highlights critical constraints in translating laboratory image classifiers to commercial agronomic environments. Because individual seeds were sampled from pooled harvest lots rather than tracked field plots, the high tabular classification performance reflects within-dataset discrimination rather than biological generalization across independent growing environments or seasons. The authors emphasized that automated phenotyping platforms must explicitly separate composite chemical descriptors from individual seed predictors, implement locked partitioning before image augmentation, and systematically probe deep neural networks against acquisition context shortcuts before deploying vision models for fenugreek cultivar verification or industrial seed sorting.
Ultimately, these findings show that while quantitative single-seed morphology and physical dimensions offer a viable framework for characterising fenugreek genotypes within controlled accessions, computer vision models can inadvertently learn scanner-level acquisition artifacts instead of genetic traits. Ensuring future reliability in digital crop phenotyping will require multi-environment field validation where replicate identities are preserved from harvest through analysis, paired with rigorous background-invariance testing across diverse imaging hardware.
Morphometric profiling across the seven accessions revealed substantial baseline variation in seed dimensions and physical traits. Across the 252 individual seeds measured per genotype, seed mass ranged from 0.014 grams in TF2 to 0.021 grams in TF6, while seed thickness spanned from 1.64 millimeters in TF2 to 2.03 millimeters in TF6. Genotype TF5 exhibited the largest average seed area at 14.29 square millimeters and the longest seeds at 5.39 millimeters, whereas TF2 displayed the smallest area at 10.51 square millimeters and shortest length at 4.51 millimeters. Optical color measurements also varied considerably, with mean seed hue spanning from 85.25 degrees in TF3 and 136.67 degrees in TF6 to 318.19 degrees in TF4 and 307.55 degrees in TF5.
Laboratory analyses of composite seed samples documented parallel chemical divergence that the researchers kept as a separate descriptive layer. Acid detergent fibre concentrations ranged from 17.91 percent of dry matter in TF3 to 23.62 percent in TF5, alongside neutral detergent fibre levels that peaked at 42.28 percent in TF5 compared to 35.95 percent in TF2. Crude protein content showed pronounced differences, registering at 32.75 percent in TF6 and 32.67 percent in TF2, compared to 20.83 percent in TF7 and 24.49 percent in TF5. Total carbohydrate levels reached 44.24 percent in TF3, which also showed a total soluble sugar concentration of 29.22 percent compared to under 16.1 percent across other genotypes. Galactomannan concentrations spanned from 20.91 percent in TF5 to 30.25 percent in TF2.
Classifier tuning within the training partition established locked configurations for each machine-learning algorithm. The multilayer perceptron incorporated two hidden layers of 128 and 64 units, the random forest used 400 trees with unrestricted depth, the classification tree required at least three samples per leaf, and the support vector machine operated with a cost of 100 and gamma of 0.01. During validation on 105 seeds under the 15-feature representation, the multilayer perceptron posted a multiclass Matthews correlation coefficient of 0.756 and accuracy of 0.790. The support vector machine achieved a validation correlation coefficient of 0.736 and accuracy of 0.771, whereas random forest attained 0.614 and classification trees recorded 0.570. Confusion matrices showed that classification errors clustered between specific genotypes, with TF6 and TF7 proving consistently more difficult to discriminate.
Detailed profiling of the deep learning architectures demonstrated substantial performance and complexity contrasts. On the locked test partition, InceptionResNetV2 yielded an accuracy of 0.533, a macro F1-score of 0.520, a Matthews correlation coefficient of 0.463, and a log-loss of 1.147, requiring 26.38 inference gigaflops and 54.54 million parameters across a 447.1-megabyte saved model. The Xception model produced an accuracy of 0.514, a macro F1-score of 0.503, a Matthews correlation coefficient of 0.442, and a log-loss of 1.290, with 21.13 million parameters and 16.77 inference gigaflops. All vision architectures followed a two-stage transfer learning routine featuring initial classifier head training followed by fine-tuning, with individual seeds centered at native scale on 800-by-800 black canvases before resizing to 299-by-299 pixels. Technical validation confirmed non-zero gradients across all 28 model-by-genotype panels without resorting to fallback activation methods.
Subject of Research: Seed phenotyping and machine learning discrimination across fenugreek genotypes
Article Title: Seed phenotyping for genotype discrimination in fenugreek ( Trigonella foenum-graecum L.): Machine learning, deep learning, and image-context robustness
Article References: Akcura, S., & Kaplan, M. (2026). Seed phenotyping for genotype discrimination in fenugreek (Trigonella foenum-graecum L.): Machine learning, deep learning, and image-context robustness. Journal of Agriculture and Food Research, 32, Article 103431. https://doi.org/10.1016/j.jafr.2026.103431
Image Credits: AI Generated
DOI: 10.1016/j.jafr.2026.103431
Keywords: fenugreek, Trigonella foenum-graecum, seed phenotyping, machine learning, deep learning, convolutional neural networks, computer vision, support vector machines, DenseNet121, morphometry, image classification, Grad-CAM, agricultural phenomics, feature ablation, data leakage, crop science, seed morphology
News Source: Blake Davidson. (November 16, 2026). Machine Learning Distinguishes Fenugreek Seeds but Exposes Deep Learning Context Flaws. Scienmag.