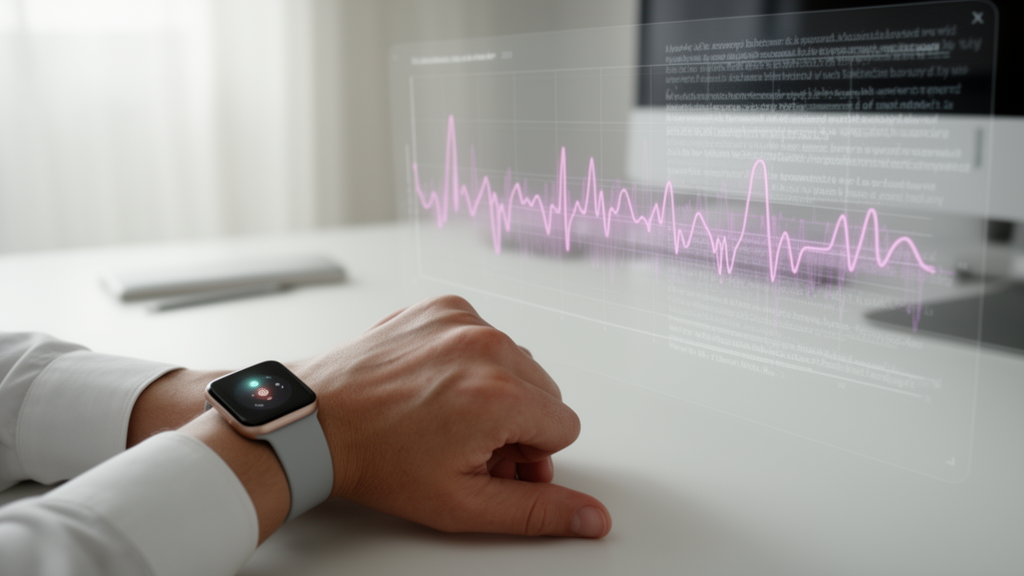
Researchers have developed a unified multimodal learning framework designed to detect mental stress by integrating physiological data from wearable sensors with textual analysis of social media posts. The study, published in Discover Internet of Things, introduces the UML-RADT-WOA architecture, which combines Internet of Things (IoT) biomarkers with Natural Language Processing (NLP) to improve the accuracy of stress detection. By addressing the limitations of unimodal methods, the framework aims to provide a more comprehensive view of human affective states, which are often characterized by complex and heterogeneous signals.
The central challenge addressed by the research is the scarcity of synchronized datasets where physiological and textual data are collected simultaneously from the same individuals. Traditional multimodal approaches often rely on strictly paired data, which is costly and difficult to obtain at scale. To overcome this, the proposed framework utilizes a synthetic Unpaired Multimodal Learning (UML) protocol. This method aligns independent datasets based on shared ground-truth stress labels, allowing the model to learn cross-modal representations without requiring subject-level correspondence between the physiological and textual sources.
The physiological component of the framework relies on the WESAD dataset, a widely used resource for wearable stress and affect recognition. The study utilized data from 15 retained subjects, who wore chest-worn RespiBAN devices and wrist-worn Empatica E4 sensors. These devices captured continuous physiological signals, including electrocardiogram (ECG), electrodermal activity (EDA), electromyogram (EMG), respiration (RESP), temperature (TEMP), and acceleration (ACC). The raw signals were segmented into 45-second windows with a 15-second stride, and each window was summarized into a 48-dimensional feature vector using statistical descriptors such as mean, standard deviation, and median.
To handle the non-Gaussian distributions and extreme outliers common in wearable IoT data, the researchers applied Modified Median Absolute Deviation Normalization (MMADN). This robust scaling method relies on the median rather than the mean, making it less susceptible to distortion from motion artifacts and irregular physiological fluctuations. The normalization parameters were fitted exclusively on the training partition of each cross-validation fold to prevent data leakage, ensuring that the model’s performance metrics reflected its ability to generalize to unseen subjects rather than its capacity to memorize training data.
The textual component of the framework utilizes the Dreaddit dataset, which consists of stress-related posts derived from Reddit. The corpus includes approximately 190,000 posts, with 3,553 annotated instances used for stress classification across five domains: abuse, anxiety, financial, PTSD, and social stress. The text was processed using a pre-trained DistilBERT architecture to extract dense, contextualized representations. To complement these deep semantic embeddings, the pipeline also computed six explicit lexical features, including the proportional frequency of stress-related vocabulary, positive sentiment words, negations, and pronouns, alongside metrics of post length and lexical diversity.
The core of the UML-RADT-WOA framework is the Modality-Token Return-Aligned Decision Transformer (RADT). This architecture projects both the 48-dimensional physiological vectors and the 774-dimensional textual vectors into a shared 192-dimensional latent space. By treating these projections as distinct modality tokens, the RADT encoder allows the model to process the heterogeneous data as a unified sequence. This approach facilitates the extraction of complex cross-dimensional features that are structurally compatible for transformer-based modeling, effectively bridging the gap between continuous biological signals and discrete linguistic tokens.
Following the RADT encoding, the framework employs a Gated Multimodal Fusion (GMF) mechanism to integrate the contextualized modality representations. A learnable sigmoid gate is estimated from the concatenated token representations, allowing the model to adaptively balance global information with modality-specific evidence. This gating mechanism helps suppress modality-specific noise, ensuring that the final fused vector emphasizes the shared global summary when beneficial while preserving complementary details from either the physiological or textual branch. The fused representation is then passed to a residual multilayer perceptron (MLP) head for the final binary classification of stress versus non-stress.
To optimize the model’s performance, the researchers utilized the Wombat Optimization Algorithm (WOA), a bio-inspired metaheuristic optimizer. WOA was tasked with tuning four critical hyperparameters: learning rate, dropout probability, residual hidden dimension, and the number of transformer layers. By dynamically balancing global exploration and local fine-tuning, the algorithm identified an optimal configuration that included three transformer layers, four attention heads, a hidden dimension of 168, a dropout rate of 0.3839, and a learning rate of 0.000424. This automated approach eliminated manual tuning biases and maximized model convergence during the training process.
The framework was evaluated using a rigorous 15-fold Leave-One-Subject-Out (LOSO) cross-validation protocol. In each fold, one subject was held out for testing, two subjects were used for validation, and the remaining twelve were used for training. This strict protocol ensures that the model is tested on completely unseen physiological data, providing a realistic assessment of its generalization capabilities. Under this evaluation setting, the UML-RADT-WOA framework achieved a mean accuracy of 84.52%, a macro-F1 score of 84.11%, a ROC-AUC of 89.52%, and an AUPRC of 85.88%. These results indicate that the model maintains high discriminative capacity across varying classification thresholds.
Comparison with internal baselines revealed that the proposed multimodal framework significantly outperformed unimodal deep learning models, including Physio-Only and BERT-Only MLPs. The multimodal approach also surpassed classical machine learning methods such as Logistic Regression and SVM-RBF. An ablation study further highlighted the importance of the RADT encoder; removing this component caused a drastic 6.6% drop in the Macro-F1 score, confirming that the structural alignment of physiological and textual data is essential for robust stress detection. The GMF module and WOA optimization also contributed to performance, with their removal resulting in measurable, though smaller, degradations in accuracy.
Despite the promising results, the study acknowledges several limitations. The multimodal instances were synthetically constructed using class-conditioned pairing, meaning the reported metrics validate the architecture’s feature-learning capabilities under controlled conditions rather than direct biological correspondence. The evaluation was also constrained by the sample size of the WESAD dataset, which included only 15 subjects. The observed standard deviation in fold-wise metrics suggests uneven generalization across held-out subjects, highlighting the inherent challenge of modeling individualized physiological stress responses.
Future work will focus on validating the framework on naturally co-recorded multimodal datasets, such as continuous smartwatch monitoring paired with active text journaling. Such datasets would allow for the assessment of the RADT framework in real-world environments with broader demographic diversity. By bridging the gap between theoretical architectural validation and deployable clinical tools, this research provides a foundation for non-invasive, multimodal mental healthcare monitoring systems that can offer timely interventions for stress-related conditions.
Beyond general architectural design, the study establishes specific demographic and operational parameters for data processing. The physiological dataset retained 15 participants, comprising 12 males and 3 females with a mean age of 27.5 years, following the exclusion of two individuals from the original cohort of 17. Segmenting the continuous chest-sensor signals yielded 2,172 sliding windows of 45 seconds each, which resolved into 1,521 non-stress instances and 651 stress instances once baseline and amusement recordings were combined. Exploratory evaluations indicated pronounced non-linear boundary overlap between classes alongside severe sensor outliers induced by motion artifacts. Concurrently, lexical analysis of the Reddit text revealed that stress posts contained elevated frequencies of self-referential pronouns, urgency cues, and anxiety vocabulary relative to broader, neutral entries.
To construct the multimodal inputs, the synthetic pairing protocol assembled up to 300 class-matched pairs per category for training, permitting sample replacement whenever class pools were restricted. For validation and testing, the routine generated up to 60 pairs per category without replacement, bounded by the smaller class partition. Each fused 822-dimensional instance combined a 48-dimensional physiological vector with a 774-dimensional textual vector before entering the internal projection stage. The experimental training workflow utilized the AdamW optimizer with a weight decay of 0.0005, gradient clipping at 1.0, a batch size of 64, and early stopping after 12 epochs without validation gain across an 80-epoch limit. Computational execution relied on a hybrid environment combining a Google Colab setup running an NVIDIA T4 GPU with a local workstation equipped with an AMD Ryzen 7 7445HS processor and an NVIDIA RTX 4050 GPU. To select model dimensions without excessive computational delays, the metaheuristic optimizer deployed an eight-candidate population across ten iterations, assessing each candidate through a three-epoch proxy training loop restricted to a single fold.
Detailed subject-level performance metrics illuminated substantial dispersion across cross-validation iterations, illustrating the difficulty of generalizing physiological patterns to unseen individuals. For example, Subject 8 achieved a macro-F1 of 0.960 alongside an area under the receiver operating characteristic curve of 0.996, whereas Subject 10 yielded a macro-F1 of 0.588 and a curve area of 0.694. This pronounced divergence indicates that fixed decision thresholds are particularly sensitive to subject-specific distribution shifts. In ablation and baseline comparisons, naive linear feature concatenation lacking the decision transformer achieved a macro-F1 of 0.7749, still outperforming the unimodal text model at 0.7414, the unimodal physiological model at 0.7315, and the non-linear support vector machine baseline at 0.4874. The authors noted that prior standalone physiological studies reporting accuracies above 91 percent frequently used randomized cross-validation schemes that risk subject-level data leakage, contrasting with the strict leave-one-subject-out protocol maintained throughout this evaluation.
Subject of Research: A unified multimodal learning framework for stress detection using IoT biomarkers and NLP with return-aligned decision transformers
Article Title: A unified multimodal learning framework for stress detection using IoT biomarkers and NLP with return-aligned decision transformers
Article References: Bhoi, S. R., Joshi, A., Bag, M., Bhoi, T., Dansana, D., Acharya, B., Prasad, V. K., & Deferisha, A. D. (2026). A unified multimodal learning framework for stress detection using IoT biomarkers and NLP with return-aligned decision transformers. Discover Internet of Things, 6(1), Article 132. https://doi.org/10.1007/s43926-026-00480-x
Image Credits: AI Generated
DOI: 10.1007/s43926-026-00480-x
Keywords: unified, multimodal, learning, framework, stress, detection, biomarkers, return-aligned, decision, transformers
News Source: Denise Maddox. (November 13, 2026). Multimodal AI Detects Stress Using Wearable and Text Data. Scienmag.